Cloudflare's Auto Router picks the model per request, cutting AI costs up to 30%
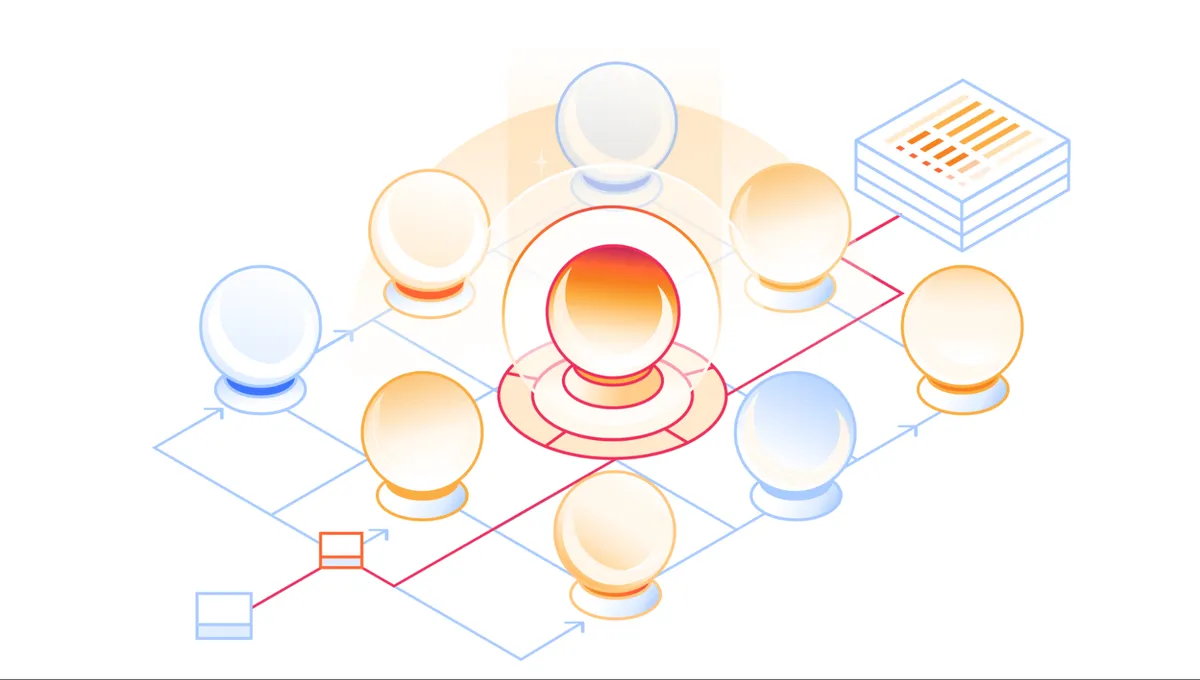
Cloudflare has released Auto Router in public beta through AI Gateway. Setting the model to cloudflare/auto lets the gateway choose, request by request, a model that is capable enough for the task, and the company says early internal results show savings of up to 30% compared with using only frontier models.
- Cloudflare's Auto Router is in public beta via AI Gateway; users set the model to cloudflare/auto.
- Cloudflare reports savings of up to 30% versus using only frontier models in internal OpenCode use.
- On an internal benchmark, auto scored 86.6% at $0.0084 per success, against 96.6% at $0.0210 for Claude Opus 5.5 and 84.2% at $0.0108 for GPT-6 Sol.
- A classifier on Workers AI scores task category and four difficulty dimensions, and the router weighs quality against cost and cache-switching penalties.
- Cloudflare plans additional routers such as cloudflare/auto-best.
Savings users do not have to think about
Cloudflare says that as companies formalize their AI adoption, they want to manage and oversee token spend, but budgets and rules only go so far. In its words, "The best savings are the ones users never notice."
In many harnesses, including OpenCode, Claude Code and Codex, individual users still pick models manually. According to Cloudflare, people often end up with models that are overkill for their work. Summarizing an email or a chat thread, for example, does not need Opus-level intelligence. The company also says it would not want to block that model entirely from a security engineering team.
Cloudflare wants AI Gateway to act as the control plane for organizations deploying AI internally. Because every request from every user, agent and tool already flows through it, the gateway can make decisions on the user's behalf instead of relying on budgets, spend limits and identity-aware analytics alone.
What the internal benchmark shows
Cloudflare uses Auto Router internally in its OpenCode deployment and in Cloudflare OS, its custom agent harness. The company reports results comparable with frontier models for coding tasks, and says the router performs best across a wide range of knowledge-work tasks, spanning technical and non-technical teams.
It evaluated cloudflare/auto against OpenAI's GPT-6 Sol and Anthropic's Claude Opus 5.5 on an internal general knowledge work benchmark. The benchmark uses simulated workspace tools and covers email, calendars, Slack, files, travel and finance. It has 97 tasks, with three samples per model per task. The results:
- cloudflare/auto: 252/291 successful trials, 86.6% success rate, total cost $2.10, $0.0084 per success.
- Anthropic Claude Opus 5.5: 281/291, 96.6%, total cost $5.91, $0.0210 per success.
- OpenAI GPT-6 Sol: 245/291, 84.2%, total cost $2.64, $0.0108 per success.
Cloudflare says Auto Router came in at 80% of the cost of Sol and 35% of the cost of Opus, with performance similar to other state-of-the-art daily-driver models. Opus 5.5 still had the highest success rate in the table. The company adds that lower token prices do not always mean lower-cost outcomes, since a cheaper-looking model may use disproportionately more tokens to solve a problem.
How the routing works
When a request arrives, AI Gateway first builds a pool of models that can serve it. It filters out models that do not support the request format or execution mode, and takes into account credentials, billing configuration, access control policies and spend limits. Unhealthy providers or models are removed during downtime and returned to the pool after an outage.
The router then looks at a compact view of the conversation, prioritizing the newest turns. A multi-head classification model running on Workers AI, deployed on GPUs across Cloudflare's edge network, assigns probabilities across 14 task categories such as coding, planning, research and data analysis. It also rates the request from one to five on four dimensions: complexity, ambiguity, stakes and dependence on earlier context.
A scoring matrix combines those signals with model benchmark results to estimate how well each model fits. The router then weighs expected quality against each model's input and output token prices. On straightforward requests price carries more weight, while harder requests ease the cost penalty. Cloudflare summarizes it as utility = expected quality - adaptive cost penalty.
For long agentic sessions, the router also accounts for cache costs. Switching models discards the cache and forces the new model to write the whole context again, so the router applies a switching penalty that grows with the tokens already in context. Within a turn it prefers to keep the same model. The result is a ranked list: AI Gateway tries the winner first and can fall back to another eligible model if the provider cannot serve the request.
What it means for teams
Cloudflare points to several design benefits. Because the task classifier and the scoring matrix are separate stages, routing decisions are legible: teams can inspect a task's predicted category and complexity to see how it led to a model choice. When a new model is released, the router does not need retraining, as Cloudflare only adds its benchmark-derived weights to the scoring matrix.
The company also plans further routers, including cloudflare/auto-best, which would use the same classification and model pool but select the highest expected quality without the cost tradeoff. It also wants the router to prefer staying within the same model family when it switches, since most models cannot read another model's reasoning tokens.
For organizations, the pitch is lower spend without asking employees to change habits, while users keep access to the most capable models when their work needs them. The figures come from Cloudflare's own internal benchmark and usage, so results in other environments may differ.
Cloudflare: Cut your AI spend with AI Gateway's Auto Router