Cloudflare previews Clairic, a System One model that extracts typed values
Cloudflare has launched a preview of Clairic, the first of a new class of System One extraction models, hosted on Workers AI as @cf/cloudflare/clairic. According to Cloudflare, it extracts, computes, estimates and forecasts values from unstructured inputs with higher accuracy, faster latency and lower cost than traditional LLMs.
- Cloudflare previews Clairic, a System One extraction model, on Workers AI as @cf/cloudflare/clairic.
- It extracts, computes, estimates and forecasts typed values, with confidence scores and 80% intervals for numeric estimates.
- It answers in one parallel pass, charges only for input and typically responds in under a second, according to Cloudflare.
- Cloudflare intends to release the model open-weights soon.
A new class of System One models
Cloudflare says Clairic builds on the System One idea that TypeSafe introduced a month earlier with its model Jev. The term comes from Daniel Kahneman's book Thinking, Fast and Slow: a System One model should be fast and precise, in contrast to System Two models such as LLMs, which are capable of deliberate reasoning.
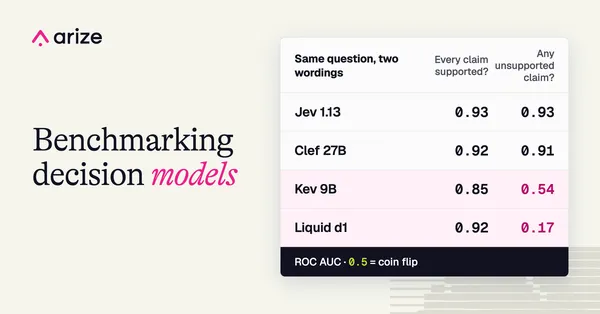
Until now, every System One model has been a decision model. According to Cloudflare, Jev and Clef take an input state and a list of questions and return probabilities for the options you list. Clairic is the first in a different class. Instead of choosing from a finite set, it answers with values pulled directly from the input, computed from it, or predicted beyond it.
Cloudflare points to a common pattern: many structured-output calls to frontier LLMs ask the same kinds of questions again and again, such as the invoice total, the delivery date, how many days late an order is, what a repair will cost, or what traffic will look like over the next 24 hours. Those answers cannot be listed in advance, so a decision model does not fit. The company says it intends to release the model open-weights soon.
What Clairic returns
Cloudflare splits model output into three kinds: a number, a choice from a fixed set, or open-ended text. Clairic handles the first, returning numbers with an 80% range, and also pulls typed values such as names, dates and lists from the input. Clef handles the second, and LLMs handle the third. In Cloudflare's framing, extraction models turn raw input into typed values, decision models turn values into decisions, and LLMs turn decisions into words.
- Extracted values: text copied from the input, returned as a span with character offsets and a confidence score.
- Computed values: numbers, dates, times, datetimes, durations and lists, read from the input or worked out from it. They follow the rules of their type, for example two decimals for cents.
- Estimated values: values the input does not state but gives evidence for, returned as a distribution inside the bounds you declare, with a median and an 80% interval.
- Forecasted values: future values of a series, one estimate per step ahead, each with its own 80% interval.
Outputs are either a value of the requested type or null when no answer is found in the input. Every scalar answer includes p_null, the probability that the value is not in the inputs, and a confidence score. Estimates include a median and an 80% interval (p10 to p90), plus all 99 percentiles on request.
Single pass, no output tokens
Cloudflare says Clairic answers in a single parallel forward pass, without reasoning or generating tokens. It charges only for input and typically responds in under a second, while an LLM that reasons through the same step takes several seconds, according to the company. Because it generates no tokens, Cloudflare says it cannot produce a mistyped answer or hallucinate in the same way as an LLM, though it can still make mistakes.
A request consists of a state, meaning the text to read plus up to four optional images, and a map of typed fields. Each field has a name, a type and optional plain-language instructions. The supported types are text, number, date, time, datetime, duration, list, estimate and forecast. There is no limit on the number of fields. If they do not fit beside the input in one pass, the server splits them into parallel passes that each see the whole input, then merges the answers. Cloudflare says asking for thirty fields costs about the same as asking for three.
Why it matters for extraction pipelines
Cloudflare argues that LLM-based extraction works most of the time but fails in ways that are hard to catch: invalid JSON, a misread digit, and no way to trace a returned excerpt back to its place in the source. Teams often build pipelines with layers of parsing, schema validation, retries and spot checks, while paying for reasoning and output tokens on every field of every document.
Clairic's span offsets, confidence scores, strict typing and explicit null handling are meant to replace much of that scaffolding. The source walks through a customer support email as an example, with an order arrival date, a price and tax amount, and a request for a fix or refund, called from a Worker through env.AI.run. The available text ends before the full example and results, so details of its output are not covered here. Clairic is a preview, and Cloudflare has not yet set a date for the open-weights release.
Cloudflare: Introducing Clairic, a new System One class of extraction models