CoreWeave and NVIDIA Say AI Factories Must Be Proven Before Production
CoreWeave argues that having GPUs is no longer enough to be ready for AI workloads, and that the full stack must be co-designed and validated before customers depend on it. In a blog post, the company describes its work with NVIDIA, its ARENA validation lab and a series of benchmark results.
- CoreWeave says AI readiness now means the whole stack holds together for weeks, not just that GPUs are racked.
- CoreWeave reports Vera Rubin NVL72 delivered 10x tokens-per-second per megawatt versus GB200 NVL72 on the same DeepSeek R1 workload.
- In MLPerf Training v6.0, it completed DeepSeek-V3 671B in 2.02 minutes on 8,192 Blackwell Ultra GPUs.
- CoreWeave ARENA lets customers test training, inference and agent pipelines on production-grade infrastructure before deployment.
Why GPUs alone no longer prove readiness
According to CoreWeave, the old test was simple: rack the GPUs, power them, cool them, and wait for the dashboards to go green. Real AI workloads ask something different. They need compute, networking, storage, scheduling and recovery to hold together for two weeks straight without stalling at the seams.
The company points to agentic workloads as a driver of the rising bar. Users do not want to wait for results, and an agent calling tools or running a multi-step reasoning loop can spike demand at any hour. Teams therefore have to prepare infrastructure for variable demand, and AI clouds cannot sacrifice reliability for speed, CoreWeave says.
The costs of failure are concrete, according to the post. A stalled job can constrain GPU resources and delay project timelines. A lost checkpoint means redoing work on the same valuable hardware. Underutilized resources still run up the bill.
Co-design with NVIDIA, from planning to networking
CoreWeave says it and NVIDIA co-design a full-stack platform for model builders, enterprises and AI natives. NVIDIA provides the accelerated computing platform, while CoreWeave supplies the AI-native cloud software and operations layer. The collaboration expanded in January 2026 to deploy the Vera Rubin platform on CoreWeave using the NVIDIA DSX platform, which the post describes as NVIDIA's reference design for planning, building and operating AI factories.
CoreWeave says it recently shared early benchmarks showing Vera Rubin NVL72 generated 10x tokens-per-second per megawatt compared with NVIDIA GB200 NVL72 on the same DeepSeek R1 workload.
The company says networking, cooling, storage and software are planned together before it breaks ground on a data center. On the network side, it uses both NVIDIA Spectrum-X Ethernet and NVIDIA Quantum InfiniBand, plus CoreWeave AI Object Storage with LOTA for data delivery. It says it was among the first cloud providers to deploy NVIDIA Spectrum-X Ethernet SN6600-LD, described as the industry's first fully liquid cooled 102.4 Tb/s Ethernet switch, and is an early adopter of NVIDIA Photonics co-packaged optics networking.
Exemplar Cloud, MLPerf and the ARENA lab
NVIDIA Exemplar Cloud is a validation initiative that measures performance per TCO against real workloads rather than synthetic ones. CoreWeave says it was among the first to achieve Exemplar Cloud status for training on NVIDIA GB200 NVL72. That validation ran on a cluster of 576 Blackwell GPUs connected with NVIDIA Quantum-2 InfiniBand and optimized by CoreWeave Mission Control, and it met NVIDIA's performance reference targets for large-scale training. CoreWeave also reports Exemplar Cloud validation for inference on Blackwell GPUs across DeepSeek-R1, Llama 3.3 and GPT-OSS.
CoreWeave says it was the first AI cloud provider to deploy NVIDIA GB300 NVL72 last year, and that it brought those systems up with CKS, SUNK, observability and the Rack LifeCycle Controller in a matter of weeks.
In MLPerf Training v6.0, the company says it completed the DeepSeek-V3 671B benchmark in 2.02 minutes on 8,192 Blackwell Ultra GPUs, the largest GB300 NVL72 cluster in the round, with completion time falling near-linearly as the cluster doubled. In MLPerf Training v5.0, CoreWeave, NVIDIA and IBM submitted the largest GB200 NVL72 cluster benchmarked at the time, completing Llama 3.1 405B in 27.3 minutes, which the post says is more than 2x faster than Hopper-based systems at the same cluster size.
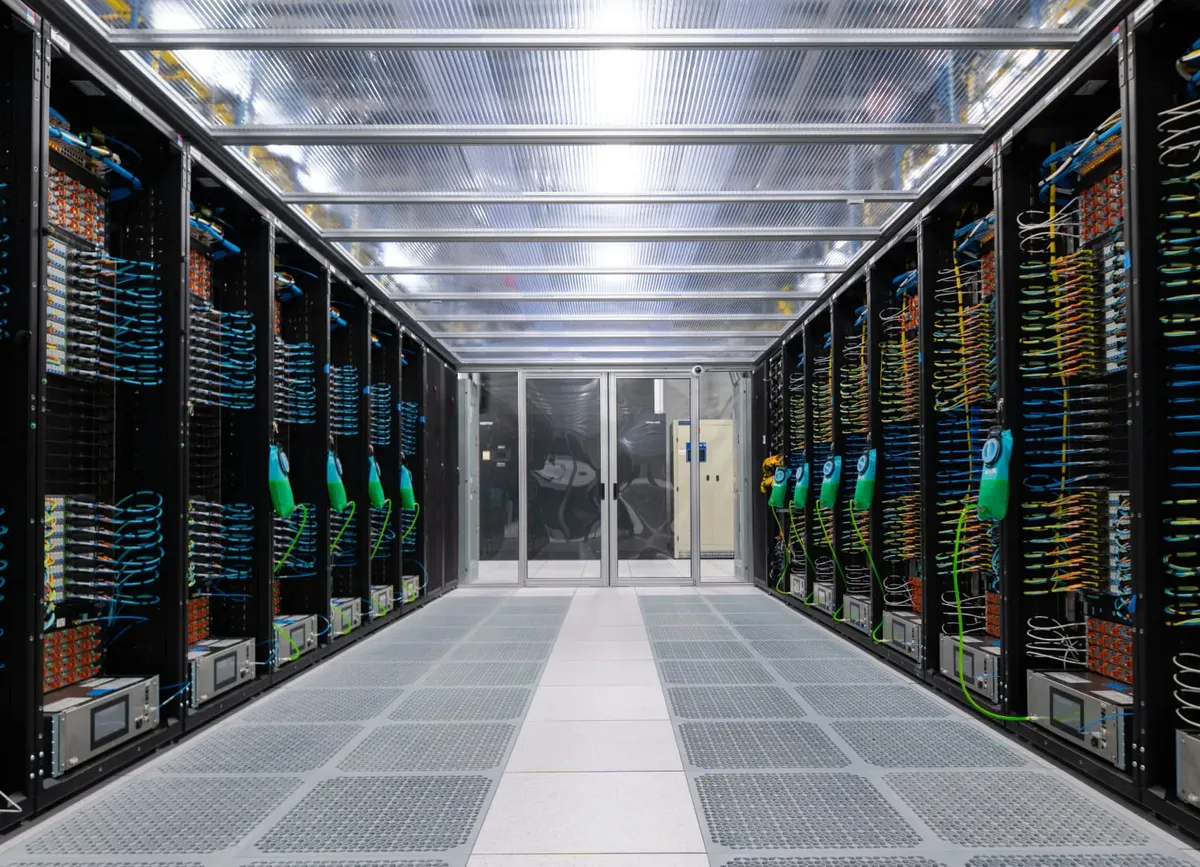
For customers, CoreWeave offers ARENA, a production-scale validation lab. Teams run training jobs, inference workloads and agent pipelines on production-grade infrastructure to surface bottlenecks and check scaling and cost behavior before deployment, with reproducible results. The lab runs the same stack a customer would, including GPU compute, CKS, Slurm and SUNK, AI Object Storage with LOTA, networking and Mission Control.
What it means for customers
The message from CoreWeave is that buyers of AI infrastructure should expect evidence of how a stack behaves under real load before committing production workloads. The company says ARENA lets customers learn scaling characteristics and cost drivers in advance rather than discovering them in production. The post is the first part of a series, with a second part promised on how the stack operates at scale and carries into the next hardware generation.
CoreWeave: Why AI Factories Need Proof Before Production