CoreWeave says it is first cloud provider to deploy NVIDIA H200 GPUs
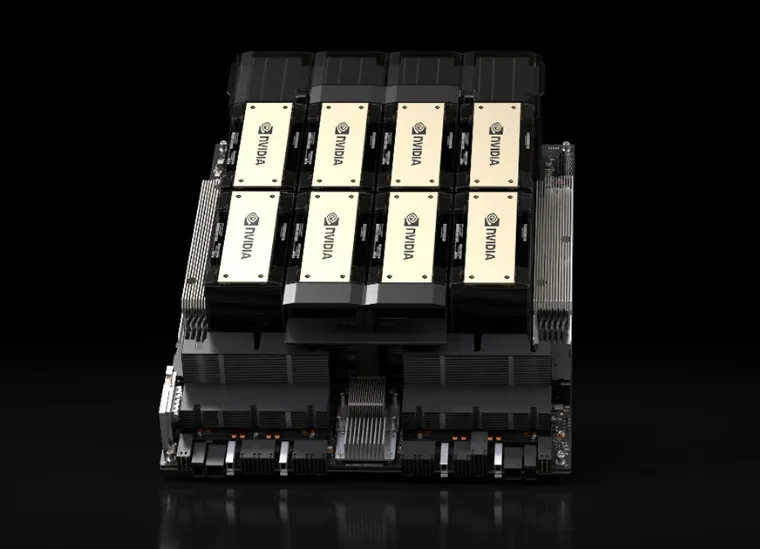
CoreWeave says it is the first cloud provider to bring NVIDIA H200 Tensor Core GPUs to market. According to the company, its H200 instances run in clusters of up to 42,000 GPUs and come with managed tools for reliability, orchestration and observability.
- CoreWeave says it is the first cloud provider to bring NVIDIA H200 Tensor Core GPUs to market.
- H200 offers 4.8 TB/s memory bandwidth and 141 GB HBM3e, up to 1.9X higher performance than H100, according to the company.
- Instances combine Intel fifth-generation Xeon CPUs, BlueField-3 DPUs and 3200Gbps Quantum-2 InfiniBand, in clusters of up to 42,000 GPUs.
- Mission Control, CKS, SUNK and Observability Services handle reliability, orchestration and monitoring.
- CoreWeave says it will soon be among the first to offer NVIDIA Blackwell.
H200 instances: hardware and claimed performance
CoreWeave describes the launch as an addition to its range of high-end NVIDIA GPUs and its growing portfolio of managed cloud services for generative AI. The company calls itself the AI Hyperscaler™.
According to CoreWeave, the NVIDIA H200 Tensor Core GPU offers 4.8 TB/s of memory bandwidth and 141 GB of HBM3e GPU memory, which help deliver up to 1.9X higher performance than H100 GPUs.
CoreWeave's H200 instances pair the GPUs with several other components:
- Intel's fifth-generation Xeon CPUs (Emerald Rapids)
- NVIDIA Bluefield-3 DPUs, which offload node networking, storage and other management functions
- 3200Gbps of NVIDIA Quantum-2 InfiniBand networking
The instances are deployed in clusters with up to 42,000 GPUs. CoreWeave says this provides the industry's highest performance and lets customers lower their time and cost to train generative AI models.
The company points to its track record with the previous generation. It says it was one of the first cloud providers to go live with NVIDIA HGX H100 instances in November 2022. In the MLPerf v3.0 benchmark, according to CoreWeave, it built the world's fastest supercomputer, which trained a full GPT-3 LLM workload in under 11 minutes using 3,500 H100 GPUs, 4.4x faster than the next best competitor.
Mission Control, CKS and SUNK
CoreWeave argues that each GPU generation brings 2-3X more raw compute than the one before, but also adds complexity when nodes and systems fail. Its Mission Control platform is meant to address this. The company says it verifies that hardware is correctly connected, up to date and tested, and that proactive health checking runs automatically on idle nodes and swaps out problematic ones before they cause failures. Extensive monitoring, it says, identifies hardware failures faster, so interruptions to training jobs are shorter and less expensive. Two components, the Fleet LifeCycle Controller (FLCC) and the Node LifeCycle Controller (NLCC), work together to provide this reliability.
For getting clusters running, CoreWeave offers CoreWeave Kubernetes Service (CKS), a managed Kubernetes product built for AI applications. According to the company, CKS clusters use bare-metal nodes without a hypervisor and an NVIDIA BlueField DPU-based architecture with cluster-private VPCs for isolation and acceleration.
CoreWeave also provides Slurm on Kubernetes (SUNK), which integrates Slurm as a Kubernetes scheduler so Slurm jobs run inside Kubernetes. The company says this lets burst and batch workloads share one platform and one pool of compute, and lets customers use either the Kubernetes or Slurm side concurrently.
Observability and what comes next
CoreWeave Observability Services give customers node-level and system-level metrics to complement Mission Control. The company says faults can come from bad user configuration such as memory allocation issues, misbehaving software updates, server component malfunctions or problems in the high-speed node-to-node network. Customers can set up alerts and dashboards for a whole cluster or individual jobs, and, according to CoreWeave, identify root causes in a matter of minutes.
Looking ahead, CoreWeave says it will soon be among the first to market with the NVIDIA Blackwell platform. It also reports that since the start of 2024 it has set up nine new data centers globally, with 11 more in progress, and that it anticipates starting work on 10 more in 2025.
For AI teams, the announcement means access to H200 capacity bundled with managed orchestration and monitoring from a single provider. The source gives no pricing or availability details, and the performance figures are the company's own claims.