CoreWeave to Offer NVIDIA GH200 Grace Hopper Instances in Q1 2024
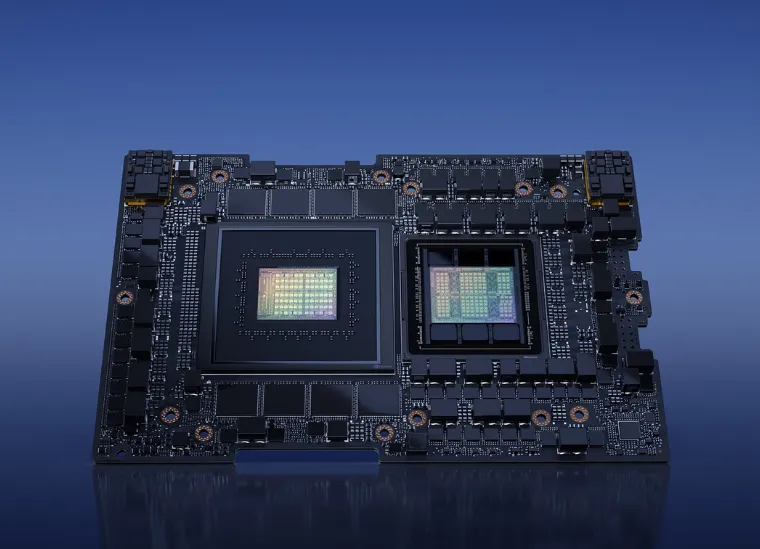
CoreWeave plans to offer new instances powered by the NVIDIA GH200 Grace Hopper Superchip in the first quarter of 2024. The company made the announcement at the SC23 conference, where it also named several partner collaborations.
- CoreWeave plans to offer NVIDIA GH200 Grace Hopper Superchip-powered instances in Q1 2024.
- The company expects to be among the first cloud providers to deploy the NVIDIA HGX H200 platform, starting next year.
- CoreWeave says the H200 GPU has higher throughput and more memory than the H100, which it expects to lower customers' cost of ownership.
- At SC23 booth #1373, CoreWeave will present its MLPerf Training 3.0 submission with NVIDIA, its serverless infrastructure and Slurm SUNK.
- Named partners include VAST Data, SchedMD, Weights and Biases, and Zeet.
GH200 and H200 plans
According to CoreWeave, the NVIDIA GH200 Grace Hopper Superchip will come to its platform in Q1 of 2024. The company also pointed to the new NVIDIA HGX H200 platform, which includes the recently announced NVIDIA H200 Tensor Core GPU, and said it expects to be among the first cloud providers to deploy these starting next year.
CoreWeave describes the NVIDIA H200 GPU as a part that "supercharges generative AI and high-performance computing", enabling faster development times and lower total costs. The company says it offers higher throughput and more memory than the NVIDIA H100 GPU, which accelerates inference when handling large language models. In CoreWeave's view, this will translate into a lower cost of ownership for its customers.
The company also said it intends to integrate the HGX H200 platform with its own software stack and systems. It calls this another milestone and says the aim is cloud infrastructure that performs at scale and helps clients get to market faster than their competitors. These are CoreWeave's own claims, and the source gives no benchmark figures or pricing for the new instances.
Partners and booth presentations at SC23
CoreWeave said it is announcing collaborations with NVIDIA and other key partners at this week's SC23 conference. The named partners are VAST Data, SchedMD, Weights and Biases, and Zeet.
At booth #1373, the company said it will present on three topics:
- Its submission with NVIDIA to MLPerf Training 3.0, which CoreWeave says delivered record-breaking performance results on the machine learning benchmarks.
- CoreWeave's serverless infrastructure, and the argument that bare metal is better for serving inference, model training and modern AI and ML workloads.
- Slurm SUNK, developed by SchedMD, which is designed for scheduling and orchestrating massively parallel jobs, alongside Kubernetes for running production applications such as inference.
Context: demand for scale
CoreWeave says its customized GPU clusters, built with NVIDIA H100 Tensor Core GPUs, are trusted by leading AI labs and enterprises to build, train and deploy some of the industry's most complex models. The company argues that these large models continue to push the limits of today's systems and require immense scale to address bottlenecks in the expansion of generative AI.
That demand for accelerated computing is the backdrop to the new hardware plans. CoreWeave says it continues to deliver specialized compute power for generative AI and high-performance computing workloads as the AI boom continues.
What it means for customers
For customers running large language model inference and other AI and HPC workloads, the announcement signals that newer NVIDIA hardware is planned for CoreWeave's platform from early 2024. CoreWeave frames the benefit as better performance and efficiency and a lower cost of ownership. The source does not give exact availability dates beyond Q1 2024, nor pricing or performance numbers, so those details remain to be confirmed by the company.


