CoreWeave to offer NVIDIA HGX Rubin NVL8 for agentic AI and HPC
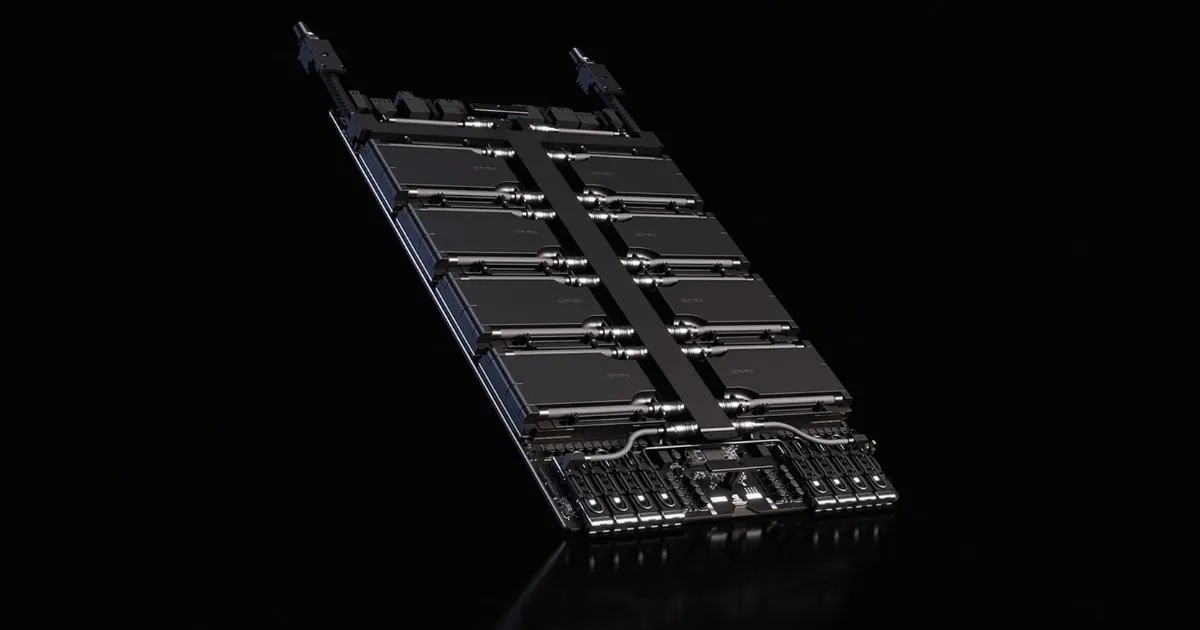
CoreWeave says NVIDIA HGX Rubin NVL8, an eight-GPU node built around HBM4 memory and sixth-generation NVLink, is coming to CoreWeave Cloud this quarter. The company is positioning the system for agentic AI, high-performance computing (HPC) and large-scale data analytics.
- NVIDIA HGX Rubin NVL8 is coming to CoreWeave Cloud this quarter, according to CoreWeave.
- The node pairs eight Rubin SXM GPUs with 2 TB of HBM4 and 130 TB/s of aggregate memory bandwidth.
- NVIDIA indicates up to 10x higher token throughput and matching training performance with 4x fewer GPUs.
- The system is 100% liquid cooled and managed through CoreWeave Mission Control, CKS and SUNK.
- Customers can request a briefing or an ARENA Pass to test workloads.
What the HGX Rubin NVL8 node offers
HGX Rubin NVL8 integrates eight NVIDIA Rubin SXM GPUs onto a single baseboard. CoreWeave notes that for agentic AI, large-scale analytics and HPC, memory capacity and bandwidth are often the limiting factors, and the node is designed around that problem.
According to CoreWeave, NVIDIA indicates the system delivers up to 10x higher token throughput than previous architectures, while matching training performance with 4x fewer GPUs. NVIDIA also projects up to 10x more tokens per second per megawatt than HGX B200 when running Kimi K2 Thinking (4K input/4K output), and says the node matches HGX B200 training throughput on DeepSeek-R1 using 4x fewer GPUs.
The key specifications listed are:
- Memory: 2 TB of total HBM4 and 130 TB/s of aggregate memory bandwidth.
- Interconnect: sixth-generation NVLink with 24 TB/s of within-node NVLink Switch bandwidth.
- Scale-out networking: eight NVIDIA ConnectX-9 SuperNICs, providing up to 800 Gb/s of backend connectivity per GPU.
- Offload: NVIDIA BlueField-4 for frontend connectivity, with networking, storage and security offloads that help preserve host CPU resources.
Where CoreWeave says it fits
For agentic AI, CoreWeave argues that the 2 TB of HBM4 can host large key-value caches for million-token context windows, so multiple agent sessions can stay active at once. It adds that single-node deployments can run models and caches, and that the 24 TB/s NVLink bandwidth removes fabric latency during tensor-parallel serving.
For data analytics, the company points to GPU-accelerated ETL, dataframe query processing, vector indexing and embedding generation scaling across nodes over the backend network. It says the 130 TB/s of memory bandwidth delivers superior cost-per-row processing for large pipelines.
For HPC, CoreWeave cites 265 TFLOPS of FP64 double-precision performance per eight-GPU node, aimed at scientific simulations, molecular dynamics and computational finance. It also describes hybrid pipelines that combine classical simulations with AI surrogate models on the same hardware.
The company gives examples of the practical effect: a drug discovery team could screen more candidate compounds per day, and a financial services firm could rerun risk analytics on the day's transactions before markets open.
The CoreWeave platform around the hardware
CoreWeave says it completed the industry's first bring-up, validation and benchmarking of NVIDIA Vera Rubin NVL72. According to the company, customer Cognition achieved 4.8x higher SWE-2 inference throughput and 3.8x faster output token speed for RL on that system.
HGX Rubin NVL8 is 100% liquid cooled. CoreWeave Mission Control monitors infrastructure as one system, from rack power and cooling to GPU behavior. For cooling, CoreWeave custom-built two components: Racky, the rack-level control point, and Valvey, which executes cooling and isolation actions. A Rack Life Cycle Controller orchestrates bring-up, health and recovery workflows.
Other platform pieces include CoreWeave Kubernetes Service (CKS), a managed cluster foundation, and SUNK, which combines Slurm scheduling with Kubernetes containerization so teams can run HPC and data-processing jobs on shared infrastructure. Customers also get Direct-to-Expert Support from the engineers who brought up Rubin-generation systems.
What it means for customers
Teams running agentic AI, analytics or HPC workloads on CoreWeave Cloud can plan for Rubin-generation hardware this quarter. CoreWeave invites customers to request a briefing on capacity planning, onboarding timeline and workload fit, or to request an ARENA Pass to test their own workload on HGX Rubin NVL8. The performance figures come from NVIDIA and CoreWeave, and the source does not give pricing or detailed availability terms.