CoreWeave brings NVIDIA Vera Rubin NVL72 to its cloud, with Cognition first
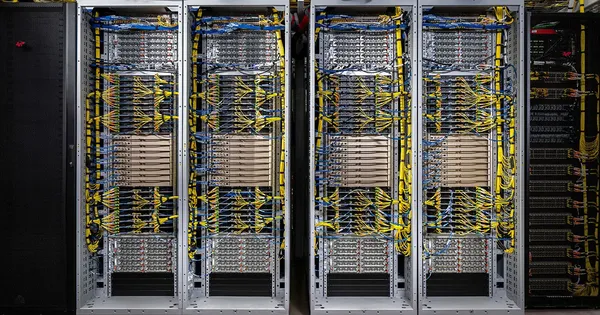
CoreWeave has announced availability of NVIDIA Vera Rubin NVL72 systems with Spectrum-X 102.4T Ethernet networking on its cloud, with Cognition, the lab behind the Devin AI software engineer, as the first customer running production workloads on the platform. The company also launched CoreWeave Forge, a connected environment for training, evaluating and improving models and agents.
- CoreWeave announced availability of NVIDIA Vera Rubin NVL72 with Spectrum-X 102.4T Ethernet, with Cognition as first production customer.
- Cognition saw up to 4.8x higher total token throughput for SWE-2 inference versus GB200 NVL72 in early tests.
- NVIDIA Vera CPU will come to CoreWeave Cloud, with more than 3x faster agent sandbox startup in testing.
- CoreWeave Forge unifies Weights & Biases, OpenPipe and marimo, with ARIA and Sandboxes now generally available.
- Canva, Capital One and MasterClass are among the first companies building on Forge.
Cognition sees up to 4.8x token throughput
The announcement was made at CoreWeave Fully Connected in San Francisco. According to NVIDIA, CoreWeave received its first Vera Rubin NVL72 production racks earlier this month and stood up a production cluster for Cognition in days.
Cognition runs training, reinforcement learning and production inference for Devin on CoreWeave. It benchmarked Vera Rubin against a GB200 NVL72 baseline using a real-world software engineering workload, sampling a subset of tasks from FrontierCode and deploying AI agents to solve them. In early tests, Cognition saw Vera Rubin NVL72 deliver up to a 4.8x increase in total token throughput for SWE-2 inference workloads over GB200 NVL72. For Devin, NVIDIA says this means faster real-time code generation and more responsive multistep reasoning.
"Agentic coding is a complex workload: long contexts, high concurrency and token volumes where cost per token decides what we can ship," said Silas Alberti, founding team at Cognition.
Capacity can be operated through CoreWeave Kubernetes Service, SUNK, CoreWeave Mission Control, CoreWeave Sandboxes and CoreWeave Inference. Early-access customers can use the platform on CoreWeave Cloud.
Vera CPU targets agent sandboxes
CoreWeave will also offer NVIDIA Vera, described as the first CPU built for AI agents. NVIDIA frames agentic AI as putting pressure on infrastructure from two directions: serving agents needs low-latency compute at scale, while post-training requires thousands of isolated environments running at once.
CoreWeave's Vera deployment puts 128 CPUs and 11,264 cores in a single rack, enough for more than 11,000 concurrent environments at one core each. Spectrum-X Ethernet switches and BlueField-4 DPUs handle secure, low-latency agent communication.
In testing, CoreWeave reported more than 3x faster agent sandbox startup times on Vera CPUs. On Terminal-Bench, it saw a 1.7x performance gain on Vera CPU across all passing tasks.
CoreWeave Forge connects production and training
Forge is meant to close the loop in which production behavior informs the next training run and each evaluation improves the next version. NVIDIA says this loop has historically been split across tools from different vendors, with signal lost at every handoff. Forge combines Weights & Biases, post-training expertise from OpenPipe and the open source marimo notebook project, and stays open across models, frameworks and clouds.
- CoreWeave ARIA, now generally available, analyzes runs, proposes experiments and recommends code changes, storing them in GitHub.
- CoreWeave Agent Lens, a new service, turns production agent observability into improvements. It improves failure detection by 20% and fixes issues at half of the cost, according to the source.
- CoreWeave Sandboxes, now generally available, run agents, tool calls, RL and evaluations in isolated CPU or GPU environments.
- Serverless supervised fine-tuning and serverless RL let users test their own training recipes. Serverless RL trains 1.4x faster at 40% lower cost than a self-managed setup.
- RL Rollouts, in private preview, loads new checkpoints into a live deployment so reinforcement learning continues without redeploys. It is powered by NVIDIA Dynamo, as is CoreWeave's managed inference service.
Canva, Capital One and MasterClass are among the first companies building on Forge. NVIDIA Nemotron open models give Forge teams a path to customizing and deploying reasoning and multimodal models.
Customers and what it means
Ennoble Care, a home-based care provider serving about 50,000 high-need Medicare patients across 15 states, selected CoreWeave for clinical AI inference. It will use reserved NVIDIA RTX PRO 6000 GPU capacity on CoreWeave Kubernetes Service to scale AI agents for clinical documentation, decision support and back-office automation.
CoreWeave says it holds the Platinum ranking in SemiAnalysis ClusterMAX 1.0, 2.0 and 3.0 and serves nine of the 10 leading AI labs. NVIDIA's Ian Buck noted that CoreWeave's V100 GPUs are still running customer workloads nearly a decade after Volta launched, even as Vera Rubin NVL72 enters production.
For teams building coding and other agents, the announcement bundles new hardware, CPU capacity for sandboxes and tooling for the training loop on one cloud. The performance figures come from early tests by Cognition and CoreWeave, and were not independently verified in the source.