CoreWeave reports 10x more tokens per megawatt from Vera Rubin NVL72
CoreWeave says NVIDIA Vera Rubin NVL72 generated 10x more tokens per second per megawatt than NVIDIA GB200 NVL72 in a DeepSeek R1 evaluation. The comparison measured throughput at a matched interactivity target, linking energy efficiency with the responsiveness experienced by users and AI agents.
- CoreWeave compared Vera Rubin NVL72 with NVIDIA GB200 NVL72 on DeepSeek R1.
- Vera Rubin NVL72 delivered up to 10x more tokens per megawatt at similar TPS/user.
- The evaluation used TensorRT-LLM, NVIDIA Dynamo and multiple inference optimizations.
- The rack includes 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs.
- CoreWeave says further software and systems tuning could improve results.
Vera Rubin performance measured at production scale
CoreWeave said it completed the industry's first bring-up and validation of NVIDIA Vera Rubin NVL72 in early June. The company stood up the rack-scale system end to end, verifying power, cooling, networking and compute, and said the platform was running at production scale.
For its first measured silicon performance results, CoreWeave ran DeepSeek R1 across Vera Rubin NVL72 and NVIDIA Blackwell NVL72. The evaluation compared token throughput per megawatt with interactivity, measured as TPS/user. According to CoreWeave, Vera Rubin NVL72 delivered up to 10x higher tokens per megawatt than NVIDIA GB200 NVL72 on the same workload while providing similar per-user interactivity.
Efficiency work targets reasoning-heavy AI workloads
CoreWeave said the evaluation used major inference optimizations on both platforms. These included large-scale expert parallelism, NVFP4 precision, multi-token prediction, and disaggregated prefill and decode, enabled through NVIDIA TensorRT-LLM and NVIDIA Dynamo.
The company said the result could allow customers to run more reasoning-model traffic within the same power budget, or run the same traffic using less power. CoreWeave also linked the performance improvement to lower cost per token and additional room to scale at the same infrastructure investment.
That matters for agentic workloads because reasoning models can plan, check their work and revise their answers, producing more tokens per query than a typical response. CoreWeave said every token must move through memory and across the NVLink domain, making interactivity a key measure of whether an agent feels responsive.
A rack designed for high-throughput inference
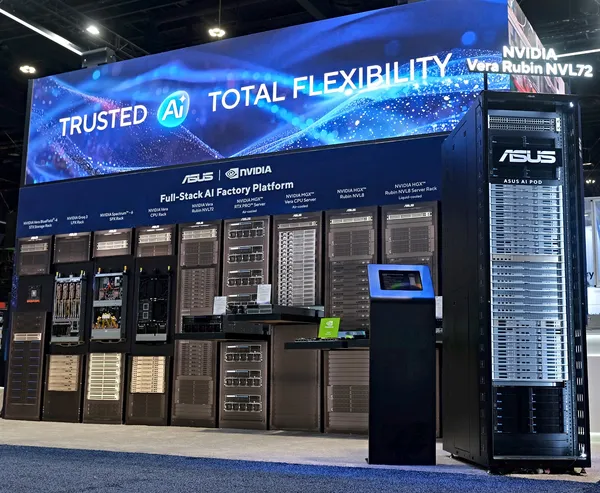
NVIDIA Vera Rubin NVL72 combines 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs in one rack. CoreWeave said the components are connected by a 260 TB/s all-to-all NVLink 6 fabric, with native NVFP4 support built into the Transformer Engine.
CoreWeave also described the operational systems supporting the rack-scale platform as a cloud service. These include patent-pending liquid cooling in Valvey, unified rack control in Racky, and coordination through its Rack LifeCycle Controller.
CoreWeave expects further gains as the system is tuned
CoreWeave said its first Vera Rubin NVL72 measurement is a starting point. The company reported that when it brought GB200 NVL72 online, inference results improved substantially over the following months as it tuned scheduling, networking and the software stack. It expects a similar trajectory for Vera Rubin NVL72 and plans to publish updated numbers as optimization work continues.
For customers running agentic security, coding or search workloads, the reported efficiency could support more inference within existing power or infrastructure limits. CoreWeave cited a global cybersecurity company, an autonomous coding agent company and an AI-native search engine as examples of organizations expecting higher performance per watt or throughput per GPU from the platform.