d-Matrix Launches Squadron Clusters With Up to 1,024 Corsair XPUs for AI Inference
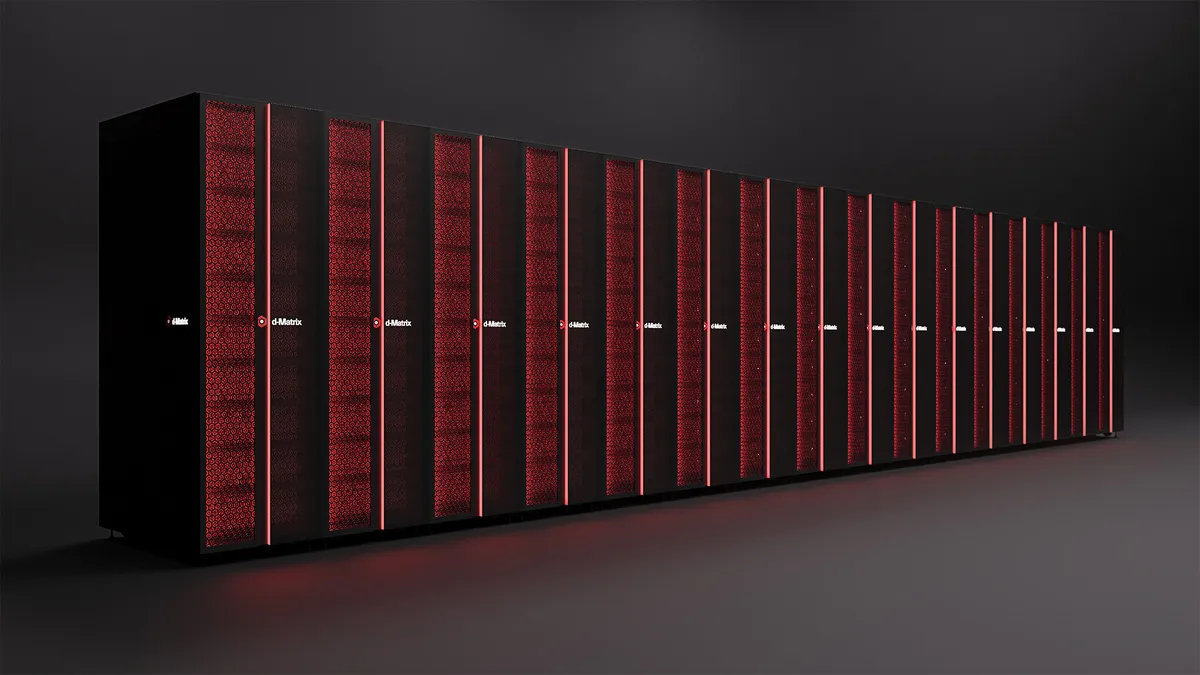
d-Matrix has announced Squadron, a fleet of multi-rack systems that offers megawatts of inference compute for running AI models at data center scale. According to the company, Squadron is now shipping to priority customers, and its Corsair servers and SquadRacks are generally available.
- d-Matrix announced Squadron, multi-rack inference clusters scaling to 1,024 Corsair XPUs.
- Squadron is shipping to priority customers; Corsair servers and SquadRacks are generally available.
- The clusters are air-cooled and industry-standard, so they can fit existing data centers, according to d-Matrix.
- A heterogeneous AFD demo with GPU servers reached 845 tokens per second per user, and 20,415 tokens per second with 64 concurrent users.
- Arista, Broadcom and Supermicro were partners in developing Squadron.
What Squadron is and who it targets
d-Matrix describes Squadron as a set of multi-rack systems built on its memory-centric compute architecture. The company says the clusters suit AI labs, enterprises and sovereign organizations running latency-sensitive applications, including coding, personal agents, cybersecurity and high-frequency trading.
Squadron was developed in partnership with Arista, Broadcom and Supermicro. d-Matrix says it has already deployed the system in its own Arizona data center for internal research and development, and it is now shipping to priority customers who will install it in their own facilities.
Sid Sheth, founder and CEO of d-Matrix, unveiled the product in his keynote on the opening day of OCP Global Summit at the San Jose Convention Center. He framed the launch as part of the company's shift "from a specialized chip company to a data center compute infrastructure business," according to the press release.
Configurations and deployment
Squadron scales up to 16 SquadRacks, each a single rack holding eight servers, into one integrated cluster with up to 1,024 Corsair XPUs. The clusters are interconnected with d-Matrix JetStream NICs and use d-Matrix Aviator software for deployment.
d-Matrix stresses that the clusters are air-cooled and built on industry standards. In the company's words, customers can integrate them into data centers they already operate, avoiding liquid cooling or costly and time-consuming data center buildouts.
The wider Corsair platform is also available in smaller units. Customers can deploy a single Corsair server, a full SquadRack, or a multi-rack Squadron cluster, all on the same architecture. Charles Liang, president and CEO of Supermicro, said the collaboration shows Supermicro's ability to deliver AI technologies through its Data Center Building Block Solutions.
Attention-FFN Disaggregation demo
Squadron clusters can run full models exclusively on Corsair XPUs. They are also designed for heterogeneous setups where work is split between GPUs and XPUs, an approach the company calls disaggregated compute.
During the keynote, Sheth said d-Matrix has implemented Attention-FFN Disaggregation (AFD) on a Squadron system paired with GPU servers. According to d-Matrix, offloading Experts/FFN to Corsair racks let the heterogeneous system generate 845 tokens per second per user. With 64 concurrent users, the setup delivered a total throughput of 20,415 tokens per second.
The company says AFD has been discussed across the industry in theory, and claims it is the first to show it running on real silicon available today. These figures are d-Matrix's own and come from the company's demonstration.
What it means for customers
For organizations that need low-latency inference, the announcement offers a route to large-scale capacity without changing their cooling infrastructure, if the company's claims hold in practice. Availability is limited: Squadron is described as generally available for select customers, while Corsair servers and SquadRacks are generally available more broadly. The source does not give pricing or delivery dates.
d-Matrix researchers planned to present the AFD demo at the company's OCP booth #C82 on Wednesday, Oct. 14, at 11am PT and 2pm PT, and on Thursday, Oct. 15, at 11am PT. Interested buyers can contact the company through its sales page.