Dharma Field Extractor turns documents into structured JSON fields
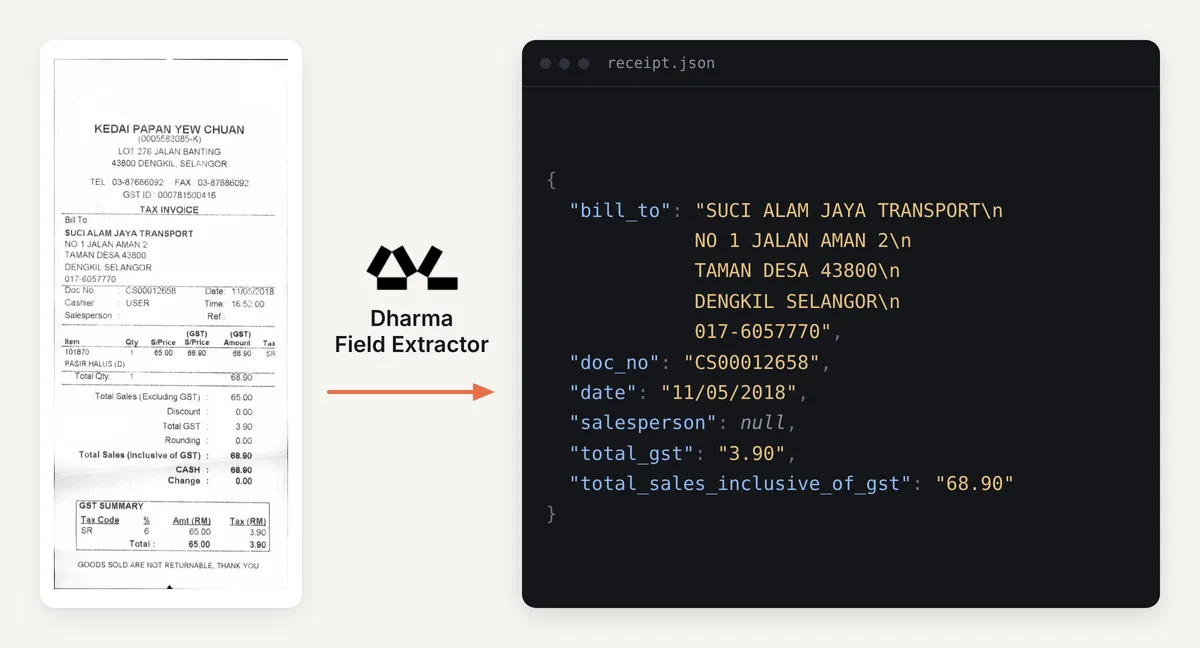
Dharma-AI has published a Hugging Face post on Dharma Field Extractor, which it describes as taking any document in and returning structured fields in JSON. The page links one model, eight datasets and one demo Space.
- Dharma-AI published a Hugging Face post titled "Dharma Field Extractor: Any Document In, Structured Fields in JSON Out".
- The linked model is tagged Image-Text-to-Text and labeled 4B.
- The post mentions one model, eight datasets and one Space.
- The DharmaOCR Lite Demo Space is described as extracting text and tables from document images.
- The source gives no benchmarks, licensing or schema details.
What the post presents
The post is titled "Dharma Field Extractor: Any Document In, Structured Fields in JSON Out" and appears on Hugging Face under the Dharma-AI author name. The title sets out the goal: a user supplies a document and receives its contents as structured fields in JSON, a format that other software can process directly.
The linked model is tagged Image-Text-to-Text and labeled 4B. That tag means it works from an image plus text input and produces text output, which fits a task where a scanned or photographed document is the input and the extracted fields are the output. The model listing carries an update marker of April 17.
Models, datasets and the demo
According to the page, the article mentions one model, eight datasets and one Space. The Space is called DharmaOCR Lite Demo and is described as a tool to "Extract text and tables from document images". It lets readers try document extraction in the browser rather than only reading about it.
The source text available for this report is sparse. It consists mostly of page navigation and metadata, so it does not include details such as benchmark results, supported document types, the JSON schema the model uses, licensing or how the eight datasets were built. Those points are not covered here because the source does not state them.
Other work from the same author
The page also lists two other posts from the same author. One is "How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications", dated October 21, 2026. The other is "Same Cluster, 33 Points More Utilization: What Changed Was the Order", dated August 17, 2026.
The titles suggest the author is working on practical efficiency questions around small language models and compute use, though the source does not explain how, or whether, these posts relate to the field extractor. The 77 percent and 33 point figures appear only in those titles and are the author's own claims.
What it means for users
For developers who handle documents such as forms or scans, a model that outputs structured JSON directly aims to cut out a separate parsing step. The public demo Space and the linked datasets give a way to test the approach. Because the source gives no performance data, anyone considering the model will need to check accuracy and fit on their own documents.
Hugging Face: Dharma Field Extractor: Any Document In, Structured Fields in JSON Out