ExecuTorch Adds Cortex-M Backend to Run PyTorch Models on Microcontrollers
PyTorch has added a Cortex-M backend to ExecuTorch, allowing PyTorch models to run directly on Arm Cortex-M CPUs with CMSIS-NN acceleration. According to the PyTorch team, this removes the need to convert models to other framework formats before deploying them on microcontrollers.
- ExecuTorch now has a Cortex-M backend that runs PyTorch models on Arm Cortex-M CPUs with CMSIS-NN acceleration.
- One workflow covers Scalar, DSP and MVE (Helium) tiers, from Cortex-M0 to M85.
- On the Alif Ensemble E8, four of five MLPerf Tiny models run in 21.5 ms or less and use under 90 KiB of RAM on one Cortex-M55 core, per PyTorch.
- The ExecuTorch core runtime is under 20 KiB of flash, according to PyTorch.
- The backend can handle CPU operations alongside Ethos-U NPU delegation in the same graph.
Removing the conversion step for microcontrollers
Microcontrollers power wearables, industrial sensors, voice interfaces and smart home appliances. PyTorch describes these devices as operating under extreme constraints: often less than 1 MB of SRAM, single-digit megabytes of flash, and power budgets measured in milliwatts.
Until now, the post says, deploying ML on Cortex-M meant leaving the PyTorch ecosystem. Developers had to convert models to alternative formats, maintain separate toolchains for training and deployment, and debug numerical mismatches introduced during conversion. PyTorch notes that it accounts for over 90% of the research code published at top ML conferences, so the translation step adds friction to every iteration cycle for teams that train in it.
Arm MCU support in ExecuTorch was already available through the Ethos-U NPU. The new backend extends it to Cortex-M CPUs, so a model can run on parts with or without an accelerator. The model is exported, quantized and lowered within the same stack that serves models on mobile, desktop and server.
How the Cortex-M backend works
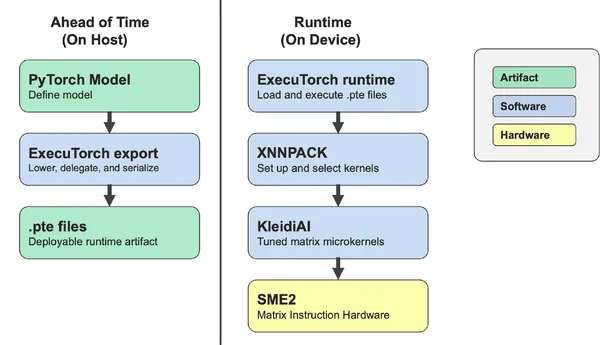
The backend replaces standard PyTorch operators with CMSIS-NN-backed custom operators through ahead-of-time compiler passes. At inference time, these operators call into Arm's CMSIS-NN library, an open source collection of optimized neural network kernels for Cortex-M processors.
- Quantized operations: linear, conv, add, mul, softmax and activations are swapped for optimized implementations.
- Target-aware compilation: the CPU variant (M0 through M85) and ISA tier are set at compile time, so the correct CMSIS-NN backend is selected and runtime dispatch overhead is eliminated.
- Purpose-built quantizer: it produces INT8 quantized graphs that match CMSIS-NN data layout requirements, using PyTorch's PT2E quantization framework.
- Single toolchain: lowering works directly on the ExecuTorch edge dialect.
The backend covers three capability tiers from one workflow: Scalar (M0, M0+, M3, M23), DSP (M4, M7, M33, M35P) and MVE, also known as Helium (M55, M85). PyTorch says Helium is where the biggest performance gains are, because CMSIS-NN uses its beat-based execution model to pipeline data movement and compute, which helps the depthwise and pointwise convolutions common in edge ML.
Compile-time decisions and the developer workflow
Microcontroller deployments target a fixed hardware profile, and ExecuTorch's ahead-of-time stack is built to exploit that. According to PyTorch, graph-level optimizations, memory planning, weight packing and kernel selection are all target-aware at compile time. For Cortex-M this includes:
- Removal of redundant dtype conversions, quantize/dequantize pairs and memory format transposes during lowering.
- Precomputing scale and zero-point arithmetic into integer multiplier/shift form at export, so quantized inference stays in fixed-point.
- Transposing convolution weights from PyTorch's OIHW layout to CMSIS-NN's OHWI format at export, so the cost is paid once during compilation.
- Static memory planning that can span multiple memory regions such as TCM and SRAM, with no heap allocator, no fragmentation and no runtime memory management.
The workflow has five steps: export the model, quantize and calibrate it with the CortexMQuantizer, re-export, lower to Edge with the CortexMPassManager configured for a target such as the M55, and serialize to a .pte file. That binary is linked into firmware alongside the ExecuTorch runtime and CMSIS-NN library, then flashed to the device.
Working alongside Ethos-U and benchmark results
Many Cortex-M MCUs pair the CPU with an Ethos-U NPU such as the U55, U65 or U85. ExecuTorch's EthosUPartitioner delegates supported operations to the NPU via the Vela compiler, and the remaining operations run on the Cortex-M CPU within the same graph. Where an operation meets the backend's quantization, layout and shape constraints, it uses CMSIS-NN. Otherwise it falls back to ExecuTorch's portable kernels, which PyTorch calls functional but not accelerated.
PyTorch says the practical benefit is that NPU operator coverage is not an all-or-nothing gate: a model with a few undelegated operations can ship on mixed CPU/NPU execution and move more of the graph to the NPU as coverage grows.
The team benchmarked four of the five MLPerf Tiny models on the Alif Ensemble E8. According to PyTorch, each model runs in 21.5 ms or less and uses under 90 KiB of RAM on a single Cortex-M55 core. It also says the ExecuTorch core runtime is under 20 KiB of flash, and that selective builds link only the operators a model needs, so code size scales with the model rather than the framework.
For teams that already train in PyTorch, the change means a single path from training to a wide range of Cortex-M devices, from basic scalar cores to Helium-equipped parts, without a separate conversion toolchain.
PyTorch: Bringing ExecuTorch to Arm Cortex-M CPUs