GIGABYTE adds 64 GB unified memory version of AI TOP ATOM desktop AI system
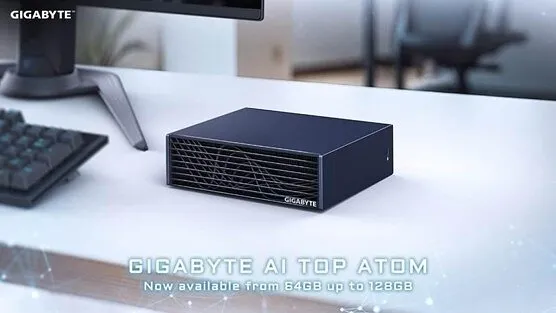
GIGABYTE has introduced a 64 GB unified memory version of its AI TOP ATOM desktop AI system, joining the existing 128 GB model. According to the company, the new configuration is available from October 23, 2026.
- GIGABYTE adds a 64 GB unified memory version of the AI TOP ATOM, alongside the existing 128 GB model.
- The new configuration is available from October 23, 2026 and uses the NVIDIA DGX Spark platform.
- ConnectX-7 networking allows clustering of up to 4 units with NVIDIA Sync.
- The software stack combines NVIDIA CUDA with the GIGABYTE AI TOP utility, including model downloading, inference and RAG.
- Availability, channels and prices vary by region.
Same hardware design, smaller memory option
GIGABYTE announced the new version of the AI TOP ATOM on October 8, 2026. It keeps the hardware design of the AI TOP ATOM, which is based on the NVIDIA DGX Spark platform, and adds a lower memory tier to a range that previously offered 128 GB.
According to GIGABYTE, the choice gives developers, researchers and enterprise teams more flexibility to pick the configuration that fits their AI workloads and memory needs. It also allows dedicated on-premises AI development environments to be set up.
Users can weigh memory capacity against the size of their models, their workflows and their multitasking needs. GIGABYTE says this lets them build AI applications on a single platform and move from early proof of concept to real deployment.
Local AI work in a compact desktop format
GIGABYTE points to the growing role of generative and agentic AI in daily development, where model testing, data processing and application validation are increasingly routine. The AI TOP ATOM packs AI computing into a compact desktop PC format, so users can run model inference, build prototypes and analyze data in offices, laboratories and educational institutions.
By running models and processing data locally, the company says, users keep more control over development resources and project data, and depend less on cloud computing.
For scaling up, the integrated ConnectX-7 networking technology lets developers cluster up to 4 units with NVIDIA Sync to get a larger memory pool and more computing power.
Software stack and agentic AI demonstration
On the software side, the AI TOP ATOM combines the NVIDIA CUDA-accelerated AI software ecosystem with the GIGABYTE AI TOP utility. The features include:
- model downloading
- inference
- retrieval-augmented generation (RAG)
GIGABYTE says developers can explore open models, test AI assistants, or use their own documents to build knowledge-based question-and-answer applications.
The company is also exploring the system for agentic AI. In a multi-node scientific computing demonstration, GIGABYTE integrated NVIDIA Nemotron open models with the NVIDIA NemoClaw open agent model, linking the formulation of research hypotheses to simulation workflows. GIGABYTE presents this as a sign of the potential of AI agents to support scientific research.
What it means for buyers
With the addition, the AI TOP ATOM is now offered in 128 GB and 64 GB configurations, aimed at users at different stages of AI development and at different application scales. GIGABYTE says it will keep expanding its AI TOP product line and software ecosystem.
The source gives no prices. GIGABYTE states that product availability, distribution channels and pricing may vary by region, and it directs interested buyers to its official announcements and authorized local distributors.