Google details Streaming DiLoCo for LLM training across data centers
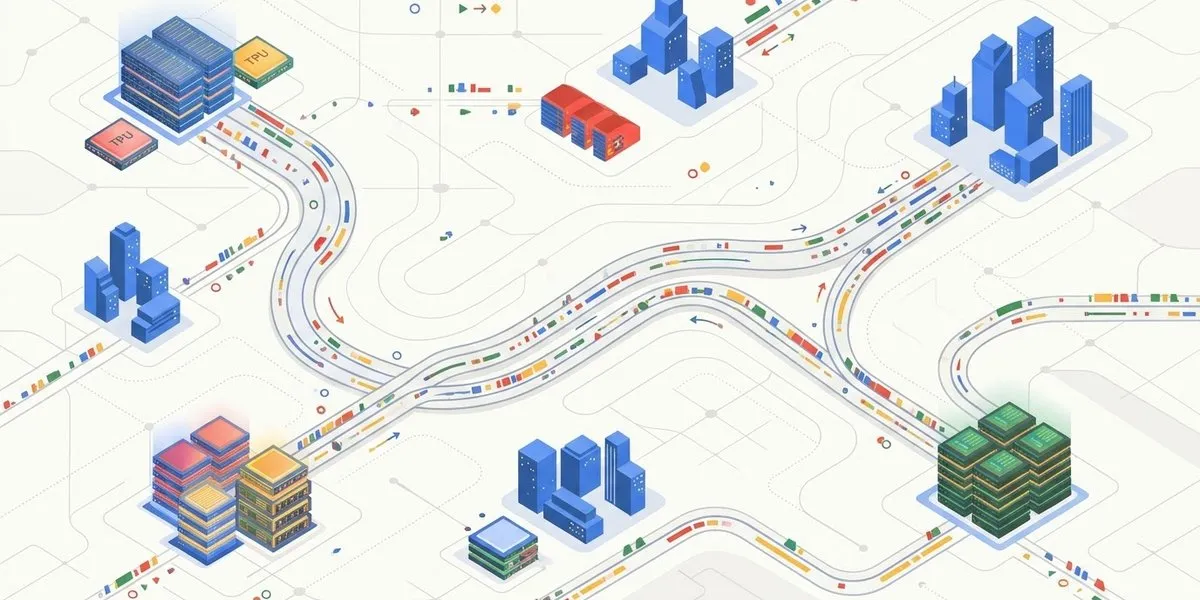
Google has detailed Streaming DiLoCo, an approach implemented in its open-source MaxText framework to support large language model training across geographically distributed compute slices. The method spreads model synchronization across training steps instead of sending the entire model at once over slower network links.
- Streaming DiLoCo is implemented in Google's open-source MaxText framework.
- It synchronizes model fragments across steps instead of sending the full model at once.
- Google's Qwen3-32B example uses 65 fragments and 65 local steps.
- The benchmark reduced cross-slice traffic from 4,258.8 GB to 67.0 GB over 65 steps.
- The tests used 2× TPU v5p-32 slices and 10 Gbit/s and 30 Gbit/s limits.
A different approach to distributed training
Training state-of-the-art large language models traditionally depends on a single, tightly connected accelerator cluster. Google says that physical and cost constraints make scaling one cluster increasingly difficult, while connecting compute slices across data centers introduces a different problem: wide-area networks have higher latency and lower bandwidth than local interconnects.
Standard data-parallel training synchronizes gradients across devices at every step. When that synchronization crosses a congested or geographically distributed network, computation can stall while the system waits for communication. DiLoCo, which stands for Distributed Low-Communication, addresses this by dividing training among independent compute groups called learners.
Each learner performs H local optimization steps before the groups communicate. At the end of that interval, the learners calculate changes to their weights, average those changes through a distributed all-reduce operation and apply an outer optimizer. Google says this cuts communication frequency by a factor of H while achieving comparable convergence and model quality.
Streaming synchronization avoids network spikes
Vanilla DiLoCo reduces the total amount of communication, but it still sends the full model's weight deltas at once every H steps. Google says that can create a large, periodic stall on a limited network connection.
Streaming DiLoCo addresses this by dividing the model into P fragments. In MaxText, the fragments consist of one group for non-scanned parameters and one for each scanned Transformer decoder layer. Rather than exchanging the entire model at the end of an interval, the system synchronizes one fragment at a time, with the timing determined by Δh=max(1,round(H/P)).
When H=P, one fragment is synchronized on every step. The total communication over the interval remains the same as with vanilla DiLoCo, but the traffic is distributed more evenly. MaxText also interleaves fragments from different depths of the network, so synchronization does not focus on adjacent layers while leaving another part of the model unchanged.
Google describes a further adjustment for embeddings. The fragment containing token embeddings, the pre-logits layer norm and the output head can be much larger because its size depends on vocabulary dimensions. Large matrices from that fragment are therefore split and merged with other layer fragments to reduce traffic spikes.
Example using Qwen3-32B and TPU slices
Google's worked example uses Qwen3-32B in bfloat16, with a step time of approximately 6.2 seconds and P=H=65. Standard data parallelism exchanges about 65.5 GB of gradients on every step. Completing that transfer within roughly six seconds requires at least approximately 85 Gbps of sustained cross-slice bandwidth, according to the company's calculation.
On a constrained 10 Gbps link, Google says the same transfer would take more than 50 seconds. Vanilla DiLoCo sends the full payload every 65th step and reduces total traffic by 65x, but can still stall during that transfer. Streaming DiLoCo sends approximately 1.0 GB per step, or one 65th of the model, while maintaining the same total traffic over 65 steps. Google calculates that this requires approximately 1.3 Gbps of bandwidth.
In a benchmark, the teams trained Qwen3-32B across 2× TPU v5p-32 slices, using 64 decoder layers and 65 fragments. They tested unthrottled traffic and aggregate inter-slice bandwidth limited to 30 Gbit/s and 10 Gbit/s. Google reports that Streaming DiLoCo reduced cross-slice traffic over 65 steps from 4,258.8 GB for the data-parallel baseline to 67.0 GB, a reduction of 64 to 65 times.
For users of MaxText and teams planning distributed LLM training, the work describes a way to use geographically separated compute while limiting the synchronization stalls caused by narrow links. The results presented by Google support Streaming DiLoCo as a method for making lower-bandwidth, multi-slice training more practical.
Google for Developers: Distributed LLM Training Across Metros: Streaming DiLoCo in MaxText- Google Developers Blog