Hugging Face highlights 180B MoE inference with 32GB of RAM
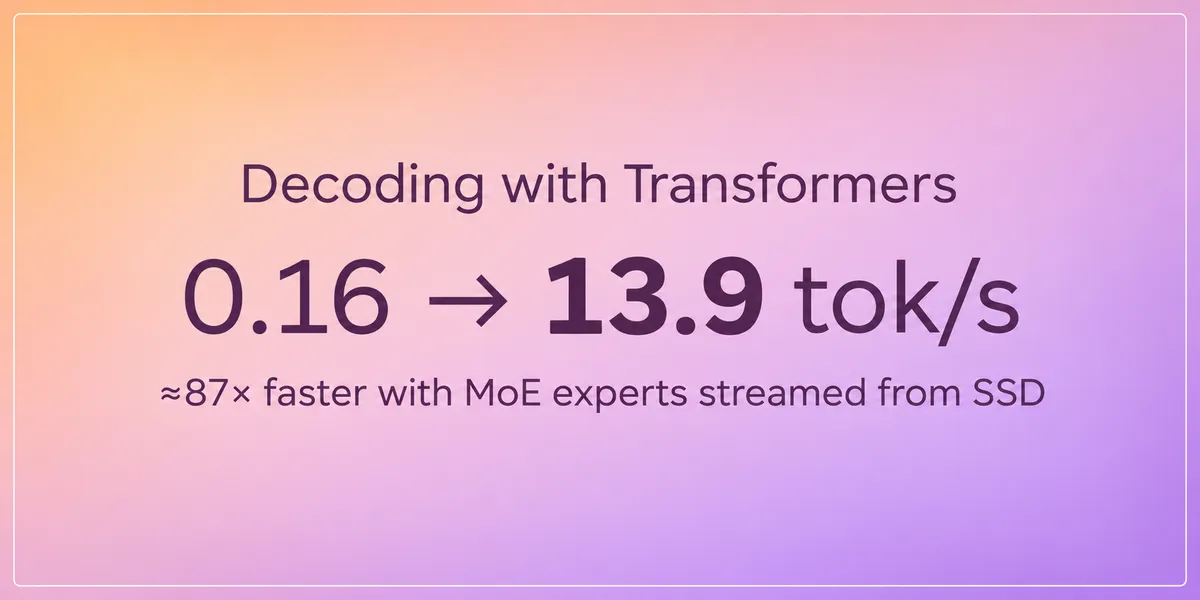
Hugging Face is highlighting a Transformers approach called MoE expert streaming, with a page titled “180B Parameters, 32GB of RAM: Pushing MoE Inference to the Limit with Transformers.” The page also points readers to text generation with Qwen3.8 using streamed experts.
- Hugging Face published a page about MoE expert streaming in Transformers.
- The title refers to 180B parameters and 32GB of RAM.
- The page links to text generation with Qwen3.8 using streamed experts.
- The source does not provide benchmarks, implementation details, or availability information.
A focus on large MoE models
The Hugging Face page, dated November 18, 2026, focuses on mixture-of-experts, or MoE, inference in Transformers. Its title centers on a model with 180B parameters and a system with 32GB of RAM.
The page describes the work as “MoE expert streaming in Transformers,” presenting expert streaming as the subject of the article. The available source text does not provide further implementation details, benchmark results, or hardware information.
Qwen3.8 is listed as an example
Hugging Face links the article to a text-generation experience described as “Generate text with Qwen3.8 using streamed experts.” This is the only specific usage example identified in the source.
The page also lists models mentioned in the article and shows one Space associated with it. The source does not state whether the approach is available through a particular product, service, or hardware configuration beyond the 32GB figure in the title.
Why the announcement matters
The announcement draws attention to the gap between a model's total parameter count and the memory available on the system running inference. By pairing 180B parameters with 32GB of RAM in its headline, Hugging Face is presenting expert streaming as a way to investigate the limits of running large MoE models with Transformers.
For users and developers, the immediate significance is that Hugging Face is documenting an approach around streamed experts and linking it to Qwen3.8 text generation. The source does not claim a specific speed, quality improvement, release date, or broader availability.