Microsoft's Agent Lightning v1.0 Trains Agents With Their Real Harnesses
Microsoft Research Asia has open-sourced Agent Lightning v1.0, a rebuilt reinforcement learning framework of about 3,500 lines of code that lets the same harness used in deployment take part directly in agent training. According to Microsoft, an end-to-end coding agent example raised Qwen3.5-9B from 41.8% to 56.4% Pass@1 on SWE-bench Verified.
- Microsoft Research Asia open-sourced Agent Lightning v1.0, a rebuilt framework of about 3,500 lines of code.
- Harnessed Agentic RL lets the deployed agent harness take part directly in training via an LLM proxy, without reimplementing the agent.
- Agents run as standard Kubernetes jobs, with no dependency on paid commercial sandbox services.
- Collocated Async RL achieved about a 2x end-to-end speedup over synchronous RL while using fewer GPUs than conventional asynchronous RL, per Microsoft.
- Qwen3.5-9B rose from 41.8% to 56.4% Pass@1 on SWE-bench Verified using about 6,000 training samples.
Training the agent that actually gets deployed
Reinforcement learning (RL) is an approach in which AI systems learn through trial and error, guided by rewards and penalties. Microsoft Research says most agent RL systems require developers to reimplement the agent inside the training framework. That is costly, and it means the agent being trained is not quite the agent that gets deployed.
Early RL systems such as verl, AReaL and slime were built on the assumption that the training framework owns the interaction loop with the environment. Real harnesses have outgrown that, the researchers argue. Coding agents such as mini-SWE-agent, OpenHands, OpenCode, Claude Code and Codex each bring their own context management, tool protocols, execution logic and dependencies. Rebuilding one for training is expensive, and the rebuilt version may behave differently from the deployed one.
Agent Lightning places an LLM proxy between the agent and the model. The agent keeps running as before: the endpoint that previously called the model API is simply pointed at Agent Lightning, and the training framework can observe and record the model calls. In v1.0, the researchers formally define this as Harnessed Agentic RL, where whichever harness is used in deployment is the one that takes part in training.
Architecture: three components in 3,500 lines
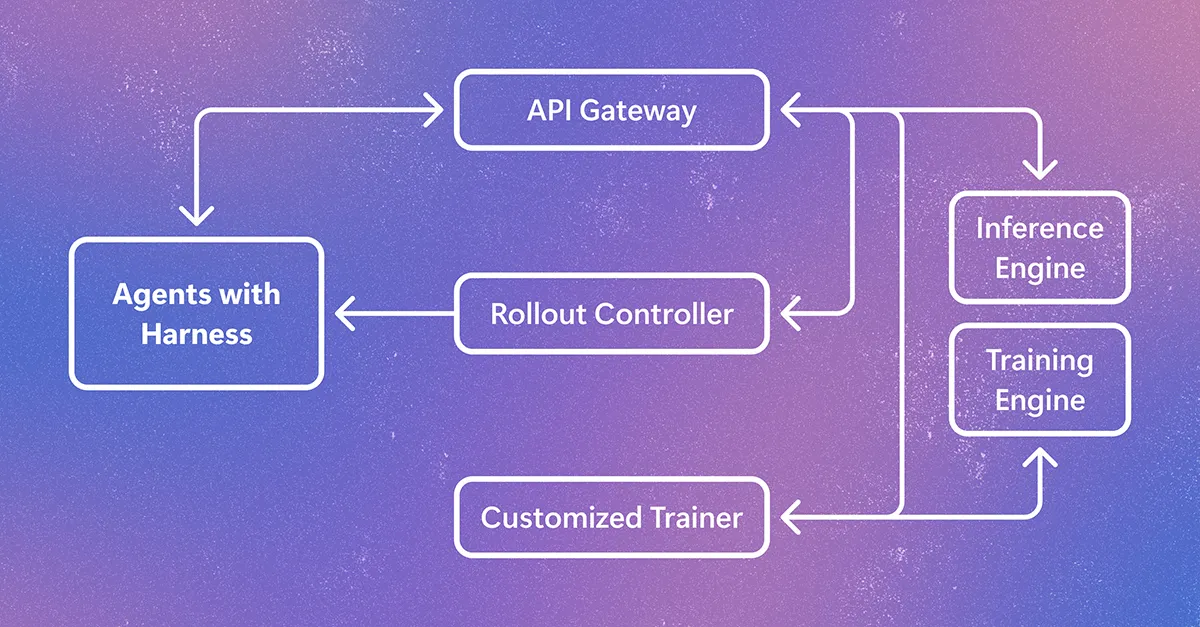
Microsoft says simplicity was the first design principle. The framework has three core components:
- API Gateway: stores rollouts, models and events, and serves as an OpenAI-compatible LLM proxy. It links each model call to its rollout and records the prompts, responses and log probabilities needed for training.
- Rollout Controller: starts and manages agent execution, either as local processes or as standard Kubernetes jobs, keeping execution separate from the trainer.
- Customized Trainer: built on verl, it creates rollouts, waits for them to finish, collects samples and assembles the final training samples through a sample adapter.
For an existing harness, pointing the model endpoint at the Agent Lightning proxy is usually enough to connect to RL training, according to the researchers.
The team also lists four challenges that arise when the harness, not the trainer, runs the loop. The training system only sees pairs of LLM requests and responses, so one rollout can be split into a variable number of samples. This affects retokenization and sample merging, advantage calculation, loss normalization and training backend scheduling. Re-running text through a chat template and tokenizer can shift token boundaries, and rollouts that produce more samples can end up counted more heavily unless baselines, advantages and loss are handled at the rollout level.
Collocated Async RL and Kubernetes support
Rollout times vary widely across agents. Synchronous RL waits for the slowest agent in a batch and leaves GPUs idle, while fully asynchronous RL raises utilization but needs separate GPU pools for rollout and training. Agent Lightning v1.0 introduces Collocated Async RL, in which rollout and model updates share the same GPUs. Once enough rollouts are collected, the API Gateway pauses new requests, waits for those in progress to finish, and resumes rollout after the update. The harness does not see this transition. In experiments, Microsoft reports about a 2x end-to-end speedup over synchronous RL while using fewer GPUs than conventional asynchronous RL.
Running many agents at once consumes substantial CPU, memory and compute. The researchers say other Harnessed Agentic RL frameworks often host agents on commercial sandbox services such as Modal Sandbox or E2B, where cost climbs quickly with scale. Agent Lightning v1.0 instead runs agents as standard Kubernetes jobs on self-managed clusters, cloud Kubernetes or local infrastructure, with no dependency on paid sandbox services.
Coding agent result and what it means
As a complete example, Microsoft built an end-to-end coding agent pipeline on Qwen3.5-9B. It raised Pass@1 on SWE-bench Verified from 41.8% to 56.4%, an absolute gain of 14.6 percentage points, using only about 6,000 training samples based on an open-sourced dataset.
For teams that train agents, the pitch is less reimplementation work and a training setup that matches what runs in production. Because the framework is small, Microsoft says it is clear enough to understand, modify and extend, and the Kubernetes approach is meant to lower the cost of large rollouts while keeping the pipeline open source and reproducible. The figures above are Microsoft's own reported results.