Jev misses subtle errors in harder LLM judge test, MLflow finds
TypeSafe's Jev judge model agreed with human labels on 64 of 72 answers in a harder MLflow test, while GPT-OSS-120B matched all 72. Jev was far faster and cheaper, and routing its uncertain verdicts to GPT-OSS closed the gap on this dataset.
- Jev agreed with human labels on 64/72 answers in each of two runs, while GPT-OSS-120B agreed on all 72.
- Jev's median latency was 0.20 seconds versus 1.44 seconds for GPT-OSS-120B.
- Estimated Jev cost was about $0.020 per 1,000 judgments, excluding credit-purchase fees.
- Sending judgments with probabilities from 0.2 to 0.8 to GPT-OSS gave 72/72 agreement, though the range was chosen after seeing the data.
- MLflow 3.17, not yet released, will support Jev through the typesafe:/ model URI.
A harder test set built from near-miss answers
In Part 1 of the series, MLflow compared Jev with GPT, Claude and DeepSeek as judges for MLflow QA answers. According to that post, Jev matched all 30 human labels, with the lowest measured latency and estimated cost. Part 2 asks whether it still catches errors in answers that are almost right.
Jev is TypeSafe's model for structured decisions. Given a question, relevant documentation and a candidate answer, it returns the probability that the answer is correct, without a written explanation. In this test, a probability of at least 0.5 counted as correct.
The team built 12 questions, each with one correct answer and two subtly incorrect ones, in English and Japanese, for 72 answers in total. The wrong answers included incorrect API names, reversed source and target roles, missing permissions, and correct statements followed by a false qualification. For three questions, the correct answers were also paraphrased to check whether different wording would trigger a rejection. The comparison was between typesafe/jev-1.13 and gpt-oss-120b.
Results: Jev accepts some almost-correct answers
The full dataset was run twice. Jev agreed with human labels on 64 of 72 answers in each run, scoring 32 of 36 in each language. GPT-OSS-120B agreed on all 72. Jev accepted every correct answer, including the paraphrases, and caught errors such as a wrong retention period or a reversed yes/no conclusion. Its mistakes were almost correct answers with one material error.
MLflow quoted three incorrect English answers that Jev accepted:
- Reversed meaning: the answer used WHEN NOT MATCHED THEN INSERT but said it applies to target rows with no match in the source. In fact it inserts source rows that have no match in the target.
- Missing permission: the answer said CREATE SECRET and USE SCHEMA on main.default are enough, but for a user who does not own the schema, the required USE CATALOG permission was omitted.
- Wrong command: asked whether a DELETE on a table with deletion vectors immediately rewrites the Parquet files, the answer correctly said no, but named VACUUM ... APPLY (PURGE). According to the documentation excerpt, rows are removed when files are rewritten, for example by OPTIMIZE or REORG TABLE ... APPLY (PURGE).
Speed, cost and routing uncertain cases
Jev's median latency was 0.20 seconds, compared with 1.44 seconds for GPT-OSS-120B, about seven times faster in this setup. The figures come from two runs with 144 measurements per judge. Jev's estimated inference cost was about $0.020 per 1,000 judgments, excluding credit-purchase fees. GPT-OSS produced an average of 224 output tokens per judgment, including reasoning.
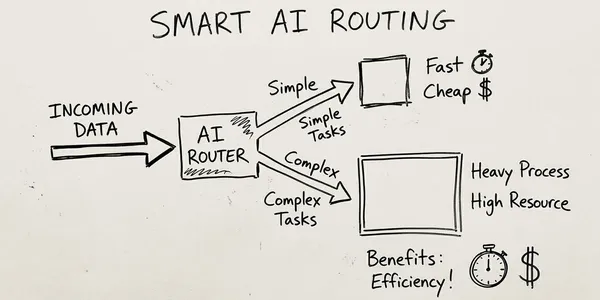
The team then looked at whether Jev's probabilities could flag judgments needing a second check. In both runs, every false acceptance scored roughly 0.5 to 0.8, while every correct answer scored at least 0.91. Had judgments in the 0.2 to 0.8 range gone to GPT-OSS for a second opinion, fewer than 20% would have needed it, and the combined verdicts would have matched all human labels. In run 1, 12 of 72 judgments were sent on, and in run 2, 13 of 72. Both reached 72 of 72 agreement.
MLflow cautions that the range was chosen after looking at the same data, so it should be treated as a starting point rather than a rule. In repeated calls on identical inputs, one false acceptance scored 0.82 and would have fallen outside the range.
Using Jev with make_judge and what to do next
MLflow 3.17 has not been released yet. According to the post, it will support Jev in built-in scorers and custom judges through the typesafe:/ model URI. The example in the post defines a boolean judge with make_judge and the model typesafe:/jev-latest, requiring TYPESAFE_API_KEY in the environment. MLflow records the true/false verdict as jev_correctness and the probability in the feedback metadata under typesafe.probability. The example will not run on the current stable release, and because it uses jev-latest and slightly different instructions from the benchmark (which used typesafe/jev-1.13), its results may differ.
For teams considering a switch, the post's advice is practical: an answer can sound right and still give a user the wrong command or incomplete permissions, so such cases belong in any judge evaluation. MLflow suggests starting with an existing correctness criterion and a small labeled dataset, running Jev alongside the current judge, inspecting false acceptances, and testing any routing threshold on new examples.