NVIDIA CUDA 13.4 Brings Memory-Enforced GPU Sharing to Kubernetes
NVIDIA's CUDA 13.4 can now enforce a memory boundary for each workload sharing a GPU, and a new open-source Kubernetes operator called gpu-fractioning lets clusters use it. KAI Scheduler v0.18.0 is the first scheduler to integrate with the operator.
- CUDA 13.4 enforces per-workload GPU memory limits, transparent to applications, with a new time-sharing mode alongside sm-sharing.
- The open-source gpu-fractioning operator runs MPS on each GPU node, applies memory limits and compute modes, and measures use per fraction.
- KAI Scheduler v0.18.0 is the first scheduler integrated, through its NvFractions mode enabled with a Helm flag.
- Workloads can request exact memory or a GPU portion, with optional burst limits and a choice of time-slicing or sm-sharing.
- Any Kubernetes scheduler that writes the required Pod annotations can use the operator, according to NVIDIA.
Why GPU sharing matters
According to NVIDIA, many AI workloads need only a fraction of a GPU, and giving each one an entire device can leave capacity idle. Sharing GPUs lets platform teams serve more workloads with the infrastructure they already have.
NVIDIA GPUs already support several sharing approaches. Multi-instance GPU (MIG) splits a GPU into hardware-isolated instances that are transparent to the application. Time-slicing lets several processes take turns without memory enforcement. Multi-Process Service (MPS) lets processes run concurrently in separate address spaces, a mode called sm-sharing.
CUDA 13.4 adds a memory boundary that is transparent to the application, together with a new time-sharing mode. The sm-sharing compute mode that already existed in MPS remains available.
What CUDA 13.4 enforces
NVIDIA lists four capabilities in the release:
- An exact memory amount: a workload asks for a memory size and CUDA holds it there. An allocation above that size fails, just as it would on a smaller GPU.
- A range: a workload gets a guaranteed minimum plus a maximum it can grow into when memory is free.
- A compute mode: each workload can choose sm-sharing instead of the default time-sharing mode.
- A transparent memory limit: each workload sees only a fraction of the GPU memory.
CUDA provides the enforcement, but a Kubernetes cluster cannot use it on its own. On every GPU node, something has to run and supervise the daemons these features depend on, apply each Pod container's memory limits and compute mode before the process starts, and report what each fraction actually uses rather than what the whole GPU uses.
The GPU Fractioning Operator
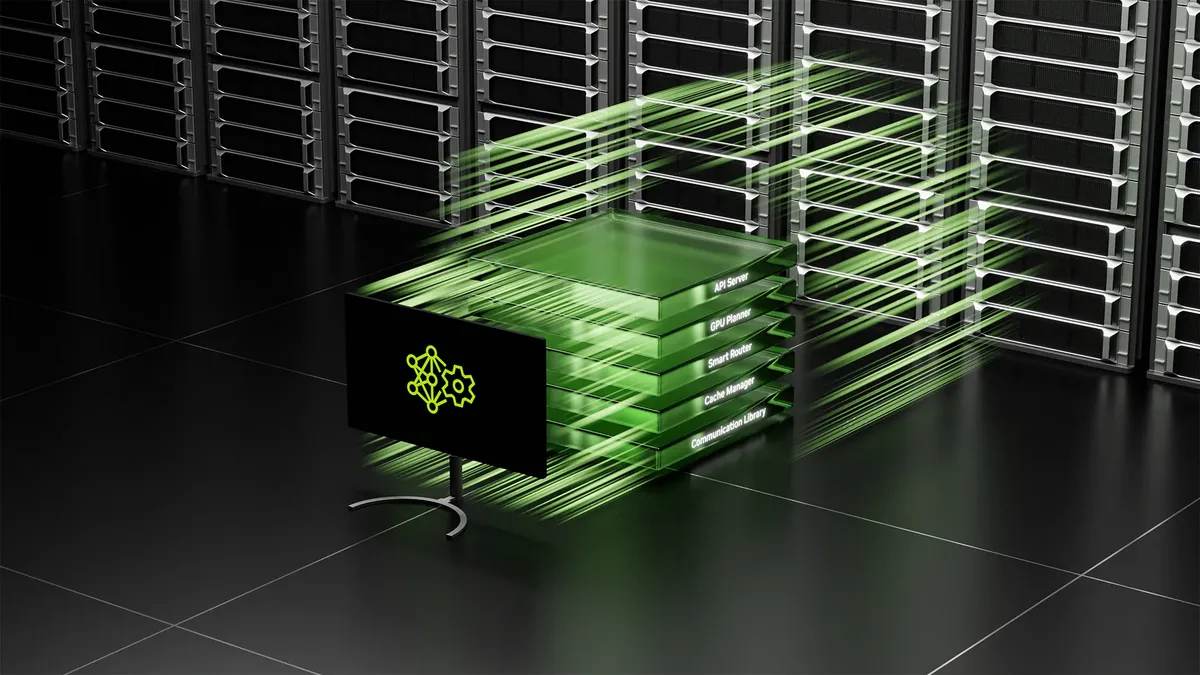
The gpu-fractioning operator is hosted under the KAI Scheduler organization on GitHub. It runs next to the NVIDIA GPU Operator, which provides the driver and the container runtime setup. It sets up and runs MPS on every GPU node, applies each workload's memory limits and compute mode, and measures memory and compute use per fraction rather than per GPU.
The operator reads per-container Pod annotations written by the scheduler. These include a guaranteed memory request, a maximum memory limit, the compute mode (time-slicing by default, or sm-sharing) and the GPUs assigned to the container. According to NVIDIA, any Kubernetes scheduler that can write these annotations can enforce GPU fractions with CUDA. The scheduler still has to choose a GPU with enough free memory and never mix compute modes on one GPU.
KAI Scheduler integration
Starting with v0.18.0, KAI Scheduler has a GPU-sharing mode called NvFractions. The scheduler picks which slice of which GPU each workload gets and writes the annotations, and gpu-fractioning enforces them on the node. Other KAI sharing modes stay available, and administrators choose one per cluster. NvFractions is enabled at install time with the Helm flag --set global.nvFractions.set=true, which also installs gpu-fractioning as a dependency.
Workloads can request memory as an absolute size using standard Kubernetes units, or as a portion of a GPU using the existing gpu-fraction annotation, for example 0.5. An optional limit lets a workload burst beyond its request. If it is omitted, the limit equals the request and the workload is capped at exactly what it asked for. A portion limit must be greater than the gpu-fraction and less than 1. The gpu-fraction-num-devices annotation spreads a request across several GPUs, and the request applies to each device. A 40Gi request with four devices gets 40Gi on each of four GPUs.
On compute, time-slicing is serial: workloads take turns on the whole GPU, each runs in its own error domain, and it is the default. SM-sharing splits the streaming multiprocessors between workloads that run at once, and they share a single error domain. A shared GPU runs one compute mode at a time, so KAI Scheduler never places both kinds on the same GPU. It tracks this per GPU, so one node can host both modes on different GPUs.
What it means for platform teams
For teams running shared GPU clusters on Kubernetes, the change gives a way to cap each workload's memory without relying on MIG hardware partitions. NVIDIA points readers to the GPU Fractioning Operator repository for installation and configuration, to admin and user guides, and to a Slack channel and bi-weekly community meetings.
NVIDIA Developer: Memory-Enforced GPU Sharing in Kubernetes with NVIDIA CUDA 13.4