NVIDIA cuPhoton Keeps Science Images on the GPU From Sensor to Decision
NVIDIA has released cuPhoton, an open-source CUDA-X toolkit that keeps image data on the GPU from sensor read through classification. According to NVIDIA, this turns processing jobs that take months on CPU-first pipelines into minutes on representative multi-GPU workloads.
- NVIDIA cuPhoton is an open-source CUDA-X toolkit that keeps image data on the GPU from sensor read through classification.
- NVIDIA reports up to 14,900x faster image loading and up to 14,550x faster signal processing versus an x86 CPU baseline on representative multi-GPU workloads.
- The speedups apply to individual operations, not to an end-to-end pipeline.
- Vera C. Rubin Observatory's LSSTCam yields up to 20 TB of images and 10 million candidate objects per night.
- cuPhoton 0.1.3 supports Python 3.12 to 3.14 and CUDA 13 on Linux.
A GPU path for the whole pipeline
NVIDIA argues that the bottleneck in high-throughput science is rarely a single slow kernel. It is the whole path from sensor to decision: reading raw data, matching point-spread functions or detector responses, subtracting or reducing, fitting, classifying and alerting. Observatories, telescopes, lasers and X-ray light sources produce image data faster than CPU-bound pipelines can handle it. With CPU-first implementations, NVIDIA says, it can take hours to months, sometimes a year or more, to get useful results from data an instrument produced in seconds.
cuPhoton is meant to cover every stage rather than speed up one step. It spans use cases from spectral and optical astronomy to time-domain laser and X-ray analysis. The toolkit includes xDataReader for direct FITS loading, xRep for image alignment, xPois for PSF matching and subtraction, xFit for dipole fitting and xScan for candidate review. It also includes xRay for time-domain X-ray detector analysis.
The Vera C. Rubin Observatory example
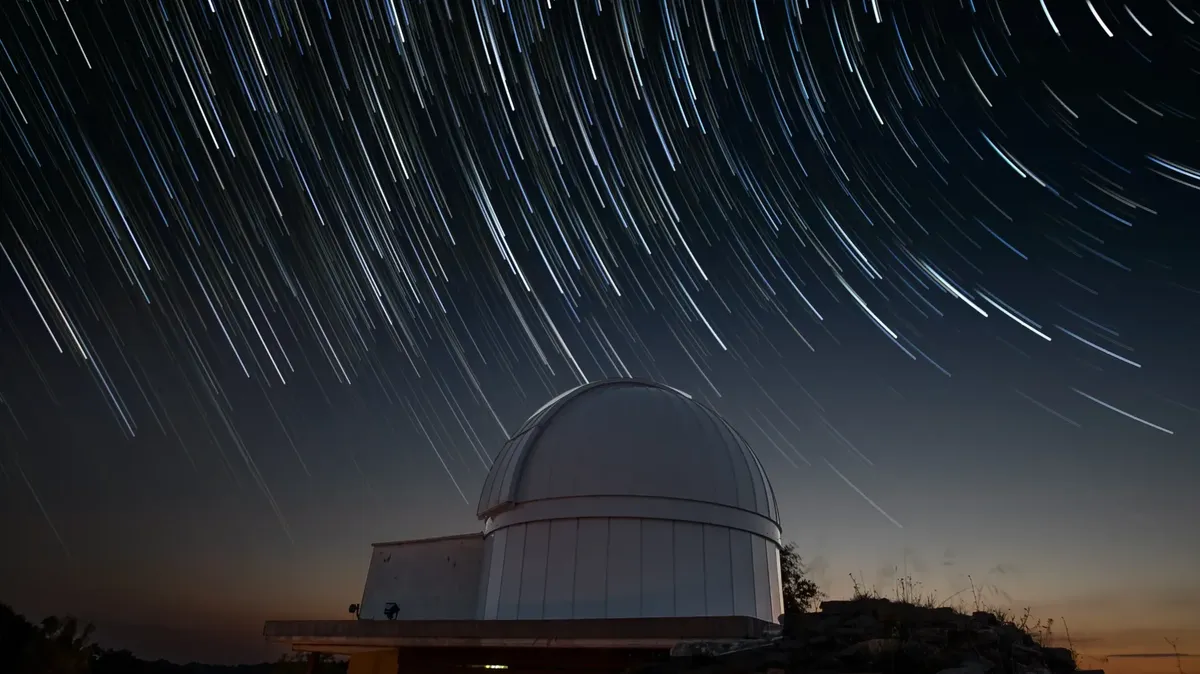
NVIDIA uses the NSF-DOE Vera C. Rubin Observatory as its showcase. Every 39 seconds after dark, the LSSTCam records a new 3.2-gigapixel exposure of the southern sky. The Prompt Processing pipeline compares each frame with a reference template of the same sky region. Within about 60 to 120 seconds, it must classify roughly 10,000 detections as astrophysical transients or artifacts such as cosmic rays, satellite trails and processing errors. Across a night, that adds up to as much as 20 terabytes of images and 10 million candidate objects.
cuPhoton scales across multi-GPU, multi-node NVIDIA Grace Blackwell and NVIDIA Vera Rubin systems. On representative workloads involving hundreds of terabytes of data on multiple GPUs, NVIDIA says it has accelerated image loading and reading by up to 14,900x and signal processing by up to 14,550x. The company also says data analytics that previously took nine months have been demonstrated in four hours on GPU-accelerated Python. For datasets on the order of kilobytes, the whole pipeline runs on millisecond or even microsecond timescales.
NVIDIA stresses a caveat: the speedups compare individual operations against an x86 CPU baseline, measured on NVIDIA GB200 NVL72 across 1, 32 and 64 GPUs. They are not an end-to-end pipeline speedup, and peak figures vary by workload, dataset, implementation and hardware.
Trying the workflow
The accompanying walkthrough uses a physically motivated synthetic pair of astronomical images, small enough to run on NVIDIA DGX Spark or a single-GPU workstation. The stages are:
- Load the current exposure and reference data into GPU memory.
- Align both visits on a shared sky grid so the same star falls on the same pixel.
- Match the point-spread functions of the two images, then subtract the reference. A moving object leaves a paired pattern of positive and negative pixels called a dipole.
- Fit a dual-PSF model to the dipole to estimate the moving object's positions.
- Visualize the PSF-matching kernel, subtraction residual and recovered dipole.
cuPhoton 0.1.3 supports Python 3.12 to 3.14 and CUDA 13 on Linux. The setup command provisions a locked environment built on CuPy, PyTorch, Numba-CUDA, KvikIO and NVIDIA nvCOMP, plus the Bokeh and Pillow visualization libraries. The FITS reader needs a native extension, which requires a C++17 compiler, CUDA and cuFile development headers, and a reentrant CFITSIO installation. The repository includes the cuPhoton CLI and a script that generates synthetic inputs.
What it means for researchers
NVIDIA's pitch is a tight loop that researchers can run interactively, shortening time to insight and letting facilities keep pace with what their instruments produce. The same workflow scales from a single-GPU workstation to multi-GPU clusters, with complete image pairs and candidate coordinates distributed across GPU workers while arrays stay on the device. Teams with large imaging datasets can test the claims on their own hardware, keeping in mind that the headline figures describe individual operations rather than whole pipelines.
NVIDIA Developer: Faster Scientific Image Analysis with NVIDIA cuPhoton