NVIDIA Details 2.8 Trillion Token Indic Pretraining Effort and Open Data Pipeline
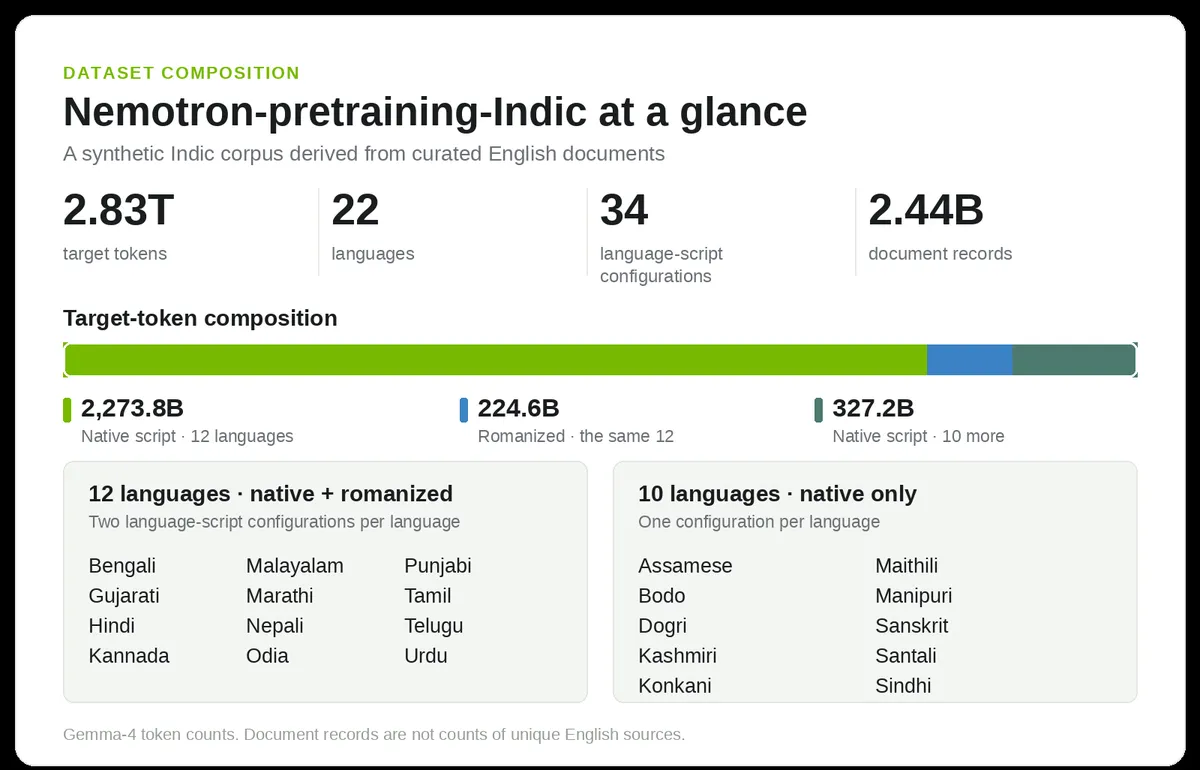
NVIDIA has published a Hugging Face blog post titled "Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline", pointing to a large-scale effort to build training data for Indic languages. The post links to related models, datasets and collections from the Nemotron family.
- NVIDIA's Hugging Face post is titled "Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline".
- The post references 4 models, 4 datasets and 2 collections.
- One linked collection hosts large-scale pretraining datasets used in the Nemotron family of models.
- The available text does not include the article body, so methods, languages and licensing are not confirmed.
What the post covers
The title of the post names two things: a pretraining effort for Indic languages that reaches 2.8 trillion tokens, and an open data generation pipeline. The post sits under the nvidia section of Hugging Face's blog, and the author's other recent posts concern NVIDIA tooling and models.
The text available for this report is limited to the page's title and surrounding listings. It does not include the body of the article. Details such as which languages are covered, how the tokens were produced, which models were trained on them, and how the pipeline works are therefore not confirmed here.
Linked models, datasets and collections
The page shows that the post references 4 models, 4 datasets and 2 collections. The model listings include a translation model with 8B parameters, an image-text-to-text model at 31B, a text generation model at 124B and a further image-text-to-text model at 66B. The listings do not state how each one relates to the Indic work.
Two collections are named in the listings. One is described as "Large scale pre-training datasets used in the Nemotron family of models", with 16 items. The other is described as "Datasets for building helpful, multi-turn, instruction-following conversational models across single and multi-turn settings", with 19 items. Both are hosted on Hugging Face, which suggests the data is meant to be accessible to outside developers, although licensing terms are not given in the available text.
Related posts from the same author
The page also lists two other recent posts from the same author. One is "Fine-Tune ASR for Your Domain with NVIDIA Speech Agent Skills", dated October 13, 2026. The other is "One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO", dated October 7, 2026. Together they show a run of Nemotron-related publications on Hugging Face in October.
What it means
On the evidence of the title alone, the release is aimed at the data side of language model development for Indic languages, where a stated scale of 2.8 trillion tokens and an open pipeline could give developers a way to build or extend their own datasets. How useful that will be depends on details the available text does not provide, including language coverage, data quality and licensing. Readers who want to assess the work should consult the full post and the linked dataset pages on Hugging Face.