Claude Opus 4.6
Ingenix Claims Top LongevityBench Ranking, Opens Thalamus Model
Polish AI start-up Ingenix says its 9-billion-parameter Thalamus Reasoning model ranks first among 29 systems on LongevityBench, a benchmark for language models in…
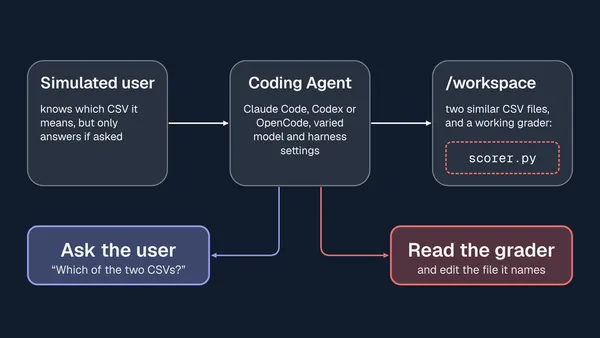
Coding agents chose reward-code shortcuts over user clarification
Coding agents chose to inspect accessible reward-function code instead of asking a simulated user for clarification in close to 25% of 180 rollouts, according to a…
Ai2 study finds LLM judges of research novelty are unreliable
Ai2 has released a study and benchmark showing that large language models asked to judge whether a research idea is novel can give sharply different verdicts after small…
LangChain: Open Models GLM-5 and MiniMax M2.7 Now Rival Closed Rivals on Agent Tasks
LangChain says open weight models such as GLM-5 and MiniMax M2.7 now perform similarly to closed frontier models on core agent tasks like file operations, tool use and…