GB200
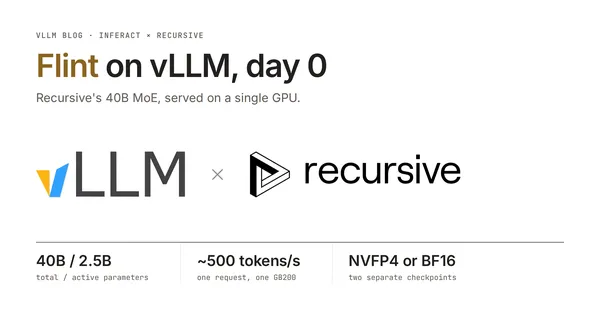
vLLM adds day-0 support for Recursive's Flint, hitting about 485 tokens/s on one GB200
The vLLM inference engine now supports Recursive's Flint from day 0, with both the NVFP4 and BF16 checkpoints running on a single GPU. According to the vLLM team, a…
vLLM cuts Elastic EP scaling pause from 100 seconds to 0.82 seconds
The vLLM project says it has reduced the serving pause during Elastic Expert Parallelism reconfiguration to under two seconds. In its DeepSeek V4 Pro benchmark, scaling…
CoreWeave Adds Self-Service and SUNK Anywhere to Its AI Training System
CoreWeave is expanding SUNK, its Slurm-on-Kubernetes training system, with self-service deployment and a new option called SUNK Anywhere that extends the system to…