Inferact
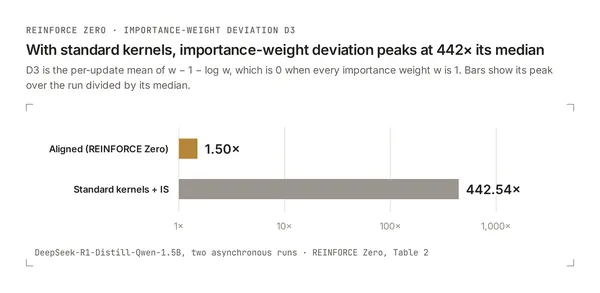
vLLM says aligned kernels make asynchronous RL stable at lag 64
vLLM says aligning the numerical kernels used by rollout and training removes a source of instability in asynchronous reinforcement learning. Its REINFORCE Zero recipe…
Google brings PyTorch-native vLLM and SGLang inference engines to TPU
Google has launched native PyTorch backends for vLLM and SGLang on TPU, built on a new runtime called TorchTPU. According to Google, the engines were developed with…
vLLM TorchTPU brings vLLM model serving to Google Cloud TPUs
The vLLM project has released vLLM TorchTPU (vllm-torchtpu), a new backend that runs vLLM on Google Cloud TPUs. According to the project, most models that already work…
vLLM Adds Support for NVIDIA Vera Rubin NVL72, Cites 7.8x Throughput Gain
The open-source inference engine vLLM now runs on NVIDIA Vera Rubin NVL72, with daily container builds and support for models from DeepSeek, Moonshot AI, Z.ai and…
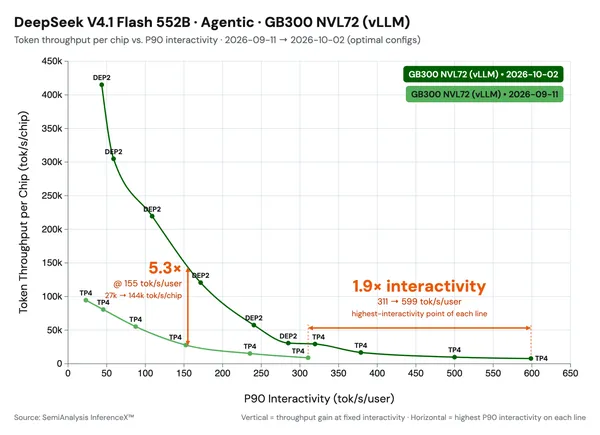
vLLM Gets DeepSeek-V4.1-Flash to 5.3x Throughput in Three Weeks
Inferact and the vLLM community say they have sped up DeepSeek-V4.1-Flash by 1.9x at low concurrency and raised throughput 5.3x under a 150 TPS constraint, within three…