NIXL
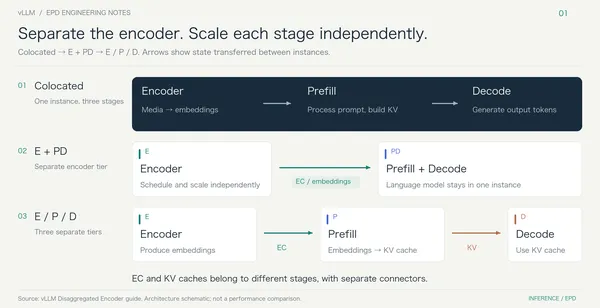
vLLM Expands Encoder Disaggregation for Multimodal AI Serving
vLLM has detailed engineering work that separates multimodal encoding from language-model prefill and decode, allowing operators to scale those stages independently. The…
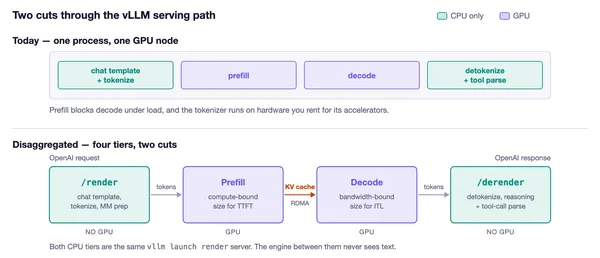
vLLM Guide Shows When Splitting Prefill and Decode Pays Off
The vLLM project has published a practical guide to disaggregated serving, which separates prompt processing, token generation and CPU-side work into different tiers.…