NVIDIA Inference Xfer Library
Push-based KV transfer in vLLM cuts TTFT up to 3x in AWS benchmark
AWS has contributed a push-based NIXL connector to vLLM that moves KV cache transfer coordination off the critical path in disaggregated prefill-decode inference. In…
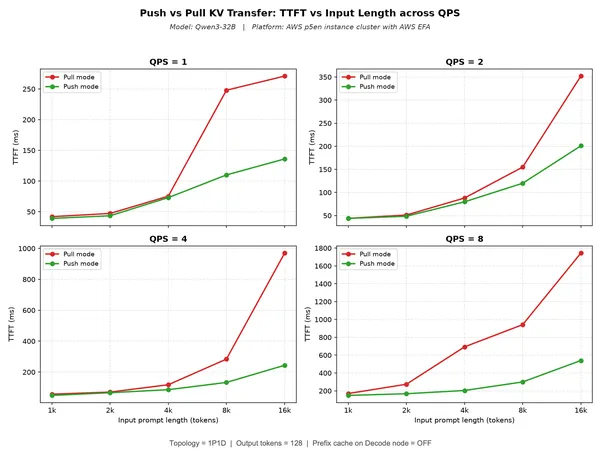
vLLM adds push-based KV transfer to cut TTFT in disaggregated inference
vLLM has introduced a push-based mode for its NIXL connector that moves post-prefill transfer coordination off the critical path in disaggregated inference. In a…