SemiAnalysis AgentX

NVIDIA Details Full-Stack Approach to AI’s Growing Memory Pressure
NVIDIA is detailing a full-stack codesign strategy aimed at easing the memory pressure created by larger AI models, longer contexts and agentic applications. The company…
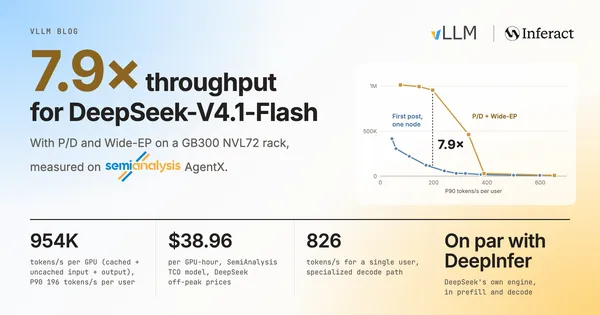
vLLM Hits 954K Tokens/s per GPU on DeepSeek-V4.1-Flash with GB300 NVL72
The vLLM team reports that its engine, running with P/D disaggregation and Wide-EP on one NVIDIA GB300 NVL72 rack, serves DeepSeek-V4.1-Flash at 954K tokens/s per GPU on…
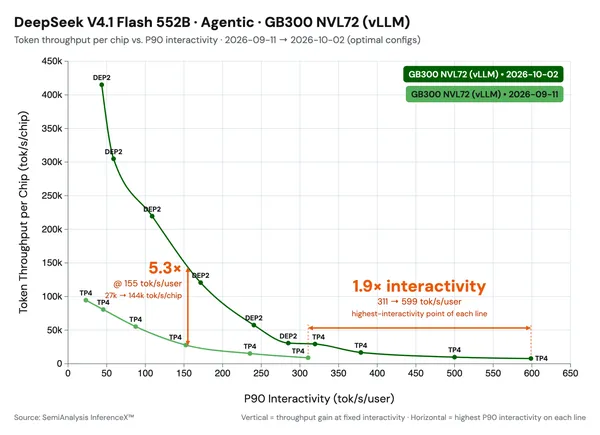
vLLM Gets DeepSeek-V4.1-Flash to 5.3x Throughput in Three Weeks
Inferact and the vLLM community say they have sped up DeepSeek-V4.1-Flash by 1.9x at low concurrency and raised throughput 5.3x under a 150 TPS constraint, within three…