SWE-bench Pro
Open models cut filler from reasoning, but terser thinking is not cheaper
Newer releases from DeepSeek, GLM and Kimi use substantially less filler in their reasoning, according to a Patronus AI analysis of open models on coding tasks. The…
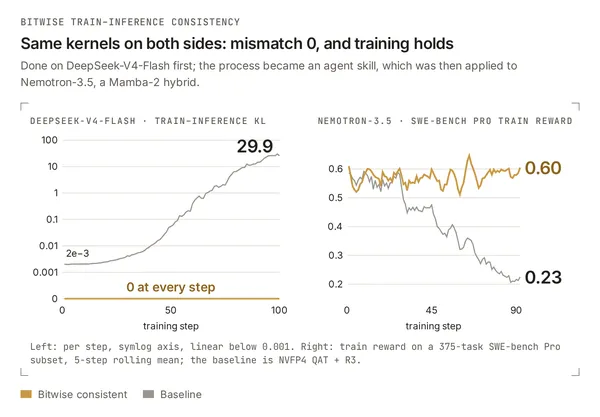
vLLM Makes RL Training and Inference Bitwise-Identical on DeepSeek-V4-Flash
The vLLM team says it has made reinforcement learning training and inference produce bitwise-identical logprobs for every sampled token on DeepSeek-V4-Flash, while…