tracelint checks agent traces for provable failures without an LLM judge
A guest post on the Arize AI blog introduces tracelint, a small open-source linter that checks OpenInference agent traces for failures the trace itself can prove, and returns an exit code for use in CI. The author, Ashwin Govind Ugale, a contributor to the Arize Phoenix observability platform, argues that many agent defects need no LLM judge.
- tracelint is an open-source linter that checks OpenInference agent traces, including those collected by Arize Phoenix.
- Hard defects, such as a failed tool result reused in a side-effecting call, make the tool exit with code 2 and fail CI.
- Candidates like repeated calls are shown for review but never fail the build.
- Rules that lack evidence are reported as not checked instead of passing.
- The tool does not judge semantic correctness, which remains a task for agent evals.
A successful-looking run with a broken trajectory
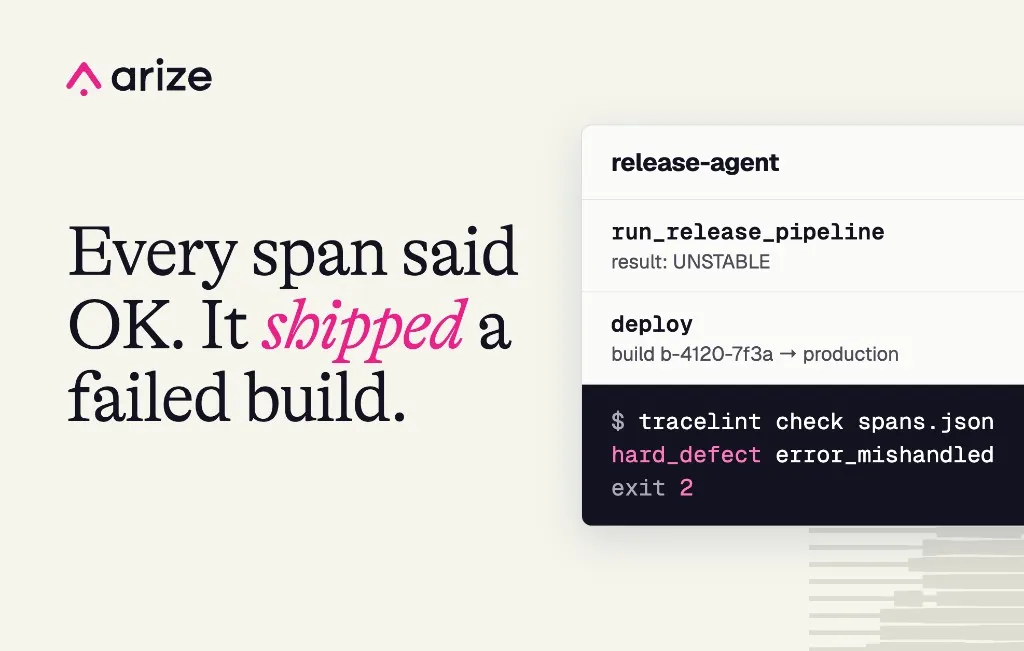
The post starts with a small experiment. Ugale asked a LangGraph release agent (gpt-4o-mini) to ship release 4.12.0. The stubbed pipeline tool returned HTTP 200 with a Jenkins result of UNSTABLE, with 3 of 215 tests failing. The agent deployed the build to production anyway and replied that the release had been shipped, adding that the Jenkins result was UNSTABLE.
According to the author, every span reported success. The agent noticed the failure and shipped regardless. With "deploy only if its pipeline passes" in the system prompt, it never deployed in ten runs. With that sentence removed, it deployed in all ten. The post calls this the kind of regression CI exists to catch.
Where the line between a lint rule and an eval falls
The post offers a rule of thumb. If a verdict depends on what the agent was supposed to do or what it meant, it is an eval. If it depends only on what the trace records, plus facts declared about the tools, it can be checked deterministically.
- Deterministic: arguments that violate a tool's JSON Schema, a call to a tool that does not exist, and a result declared as failed that is fed into a side-effecting action.
- Candidate only: the same call repeated with no apparent progress, since it might be polling or a legitimate retry. It is surfaced for review.
- An eval question: whether the agent picked the wrong strategy.
tracelint reports a defect only when the trace provides enough evidence to prove it. It does not judge whether a final answer is semantically correct.
Running it on a Phoenix trace
Teams already tracing agents with Arize Phoenix can feed the collected OpenInference spans to tracelint without changing the agent. The post shows a Python snippet that pulls spans from a Phoenix project and prints one report per run.
Run as-is, tracelint does not fail the release trace, and the author says that is correct: nothing in the trace states that UNSTABLE means failure. Two facts must come from the user in a tools.json file. First, UNSTABLE, like FAILURE and ABORTED, means the pipeline failed. Second, the deploy tool is side-effecting because it changes production.
With those declared, tracelint reports two findings and exits with code 2. One is a declared failure from run_release_pipeline. The other is a hard defect: the build ID b-4120-7f3a from the failed run was reused as an argument to deploy. The command tracelint init can draft a tools.json from a trace, including tool schemas where the instrumentation records them.
Hard defects, candidates and not checked
Every finding falls into one of three buckets. Hard defects are proven by the trace and make tracelint check return exit code 2, failing the CI job. Candidates, such as possible loops, are shown for review but never fail the build. The author calls this deliberate, because one noisy heuristic is enough to make engineers disable a linter.
The third bucket, not checked, covers rules that lacked the evidence they needed. In the example, tools.json does not say what a failed deploy looks like, so tracelint reports it cannot verify that the deploy did not fail, rather than counting it as a pass.
For teams without saved traces, the project provides a capture helper and a pytest fixture that record a run through a framework's OpenInference instrumentor, plus a GitHub Action for CI.
Limits and how it fits with evals
The post lists limits. Some checks rely on declarations such as which tools have side effects, and wrong declarations produce wrong verdicts. Repetition and unexplained argument values stay candidates because retries and value transformations can be legitimate.
The author sees three complementary layers. Deterministic trace checks suit explicit structural rules provable from a single run. Evals suit application-specific quality, behavior, grounding, tool choice and policy. Production investigation suits recurring or previously unknown failure patterns across many traces. A recurring problem found in production can, if expressible as a structural rule, become a deterministic regression check.
tracelint installs with pip install tracelint and runs with tracelint check spans.json --format openinference. The author welcomes feedback, especially traces the tool handles poorly.
Arize AI: What agent traces can tell you without an LLM judge