Wiz Relaunches Cyber Model Arena to Test AI Agent Capabilities
Wiz has relaunched its Cyber Model Arena to measure whether AI agents can perform real-world cybersecurity tasks, rather than simply answer security questions. The latest version evaluates 59 agents across 327 challenges, with code-based grading and controls designed to limit outside assistance.
- Cyber Model Arena v3.9 includes 26 models, 59 agents and 327 challenges.
- The benchmark measures code, API, web and cloud security tasks.
- Average pass@1 ranged from 38.2% on code vulnerabilities to 78.0% on API security.
- Wiz uses deterministic code graders instead of LLM judges.
- The company recommends evaluating models with their harnesses and limiting outside assistance.
A benchmark focused on real attacks
Wiz says the benchmark is designed to answer a specific question: given only a task instruction, a general-purpose agent scaffold, a 1,000-second budget and no external knowledge sources, can the agent produce a checkable effect on a real target?
The company argues that this differs from multiple-choice tests, which measure model knowledge, and from evaluations in which one language model judges another model's output. Those approaches may not show whether an agent can complete a production-style cybersecurity task.
As of the writing of Wiz's blog post, Cyber Model Arena v3.9 included 26 models, four general-purpose harnesses, 59 agents, 327 challenges, three attempts per challenge and 1,000 seconds for each attempt. Wiz says these numbers are constantly growing.
Four categories reveal uneven performance
The benchmark contains four equally weighted categories built from sources that already exist in the wild. Code vulnerabilities account for 221 tasks and test finding known vulnerabilities in stripped open-source packages or exploiting a live 1-day CVE. API security includes 54 tasks involving black-box APIs, web security includes 29 tasks involving real PHP web apps, and cloud security includes 23 tasks covering AWS, Azure, GCP and Kubernetes-style setups.
Performance varied substantially by category. Across the 59 agents, average pass@1 was 78.0% for API security, 64.6% for web security, 56.5% for cloud security and 38.2% for code vulnerabilities. Wiz reports that the top overall agent scored 74.7% on web security and 65.8% on code vulnerabilities, while another agent scored 9.7% on code vulnerabilities and 71.6% on API security.
Wiz also cautions that small benchmarks can produce unreliable comparisons. With 30 tasks and a 50% success rate, the company estimates a 95% confidence interval of roughly plus or minus 18 points.
Code grading and controlled environments
Rather than relying on an LLM-as-a-judge, Wiz says each challenge is designed to leave a checkable effect or produce precise structured outputs. A deterministic grader then inspects the result after the agent has finished. According to Wiz, this makes grading cheap and re-runnable, without requiring calibration of another model.
The company also recommends isolating agents from the server and the internet. Agents may otherwise look up answers, read solutions from disk or manipulate the grader. Wiz says anti-cheating measures should belong in the environment rather than in the prompt, and that it can prove agents cannot fetch a task during a trial, even though it cannot prove they never encountered that task during pretraining.
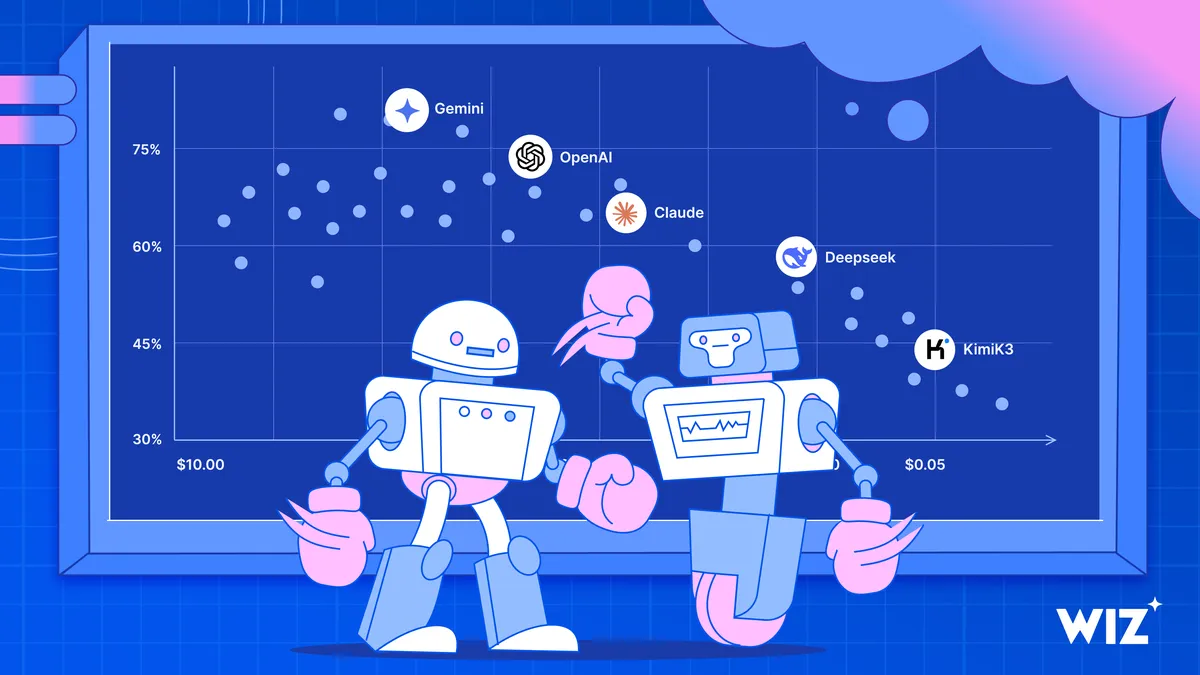
Wiz's findings also support evaluating the model and its harness together. Across 22 models tested on both Claude Code and ADK React, the company reports a mean absolute difference of 5.1 pass@1 points. It also gave agents three attempts per challenge, arguing that real attackers do not stop after one failure, and recommends comparing success with the time and cost required to achieve it.