Arize Benchmarks AI Agents With Harbor and Phoenix Plugin
Arize AI has described how it benchmarks its PXI coding agent, along with MCP servers, skills and CLIs, using the open-source Harbor framework and a plugin that records results in Arize Phoenix. According to Arize, the setup replaces a pile of mocks with a realistic, reproducible environment.
- Arize uses the open-source Harbor framework to benchmark its PXI coding agent in fresh, reproducible sandboxes.
- A Phoenix plugin records Harbor tasks as versioned datasets, agent configurations as experiments, and verifier rewards as annotations.
- The same tasks and verifiers can test PXI, Claude Code, Codex, an MCP server and the Phoenix CLI.
- In Arize's test, almost every answer was correct, but traces exposed differences in turns and tool calls, such as a Codex workflow that ran longer than needed.
Why simple agent evals fell short
Arize says offline experimentation is one of the hardest parts of agent development. Once an agent is deployed, its behavior can be observed in the wild. Before that, benchmarking needs the same tasks, data, tools and environment for every version, with state reset between runs.
The company ran into this while evaluating PXI, the coding agent built into Phoenix. Its first evals tested PXI's tool calling on single turns, but the team hit limits. Fixtures lacked context that the frontend normally supplies, such as the current page and time. Some tools needed the frontend to run at all. Adding an MCP server for skills and docs meant yet another component to mock. Without a real Phoenix database, the team could check whether PXI called a tool, but barely test what it did with the result.
Arize says expanding that suite meant rebuilding or mocking more of the system, and it became harder to trust that this "Frankenstein version of PXI" behaved like the production one.
How Harbor works
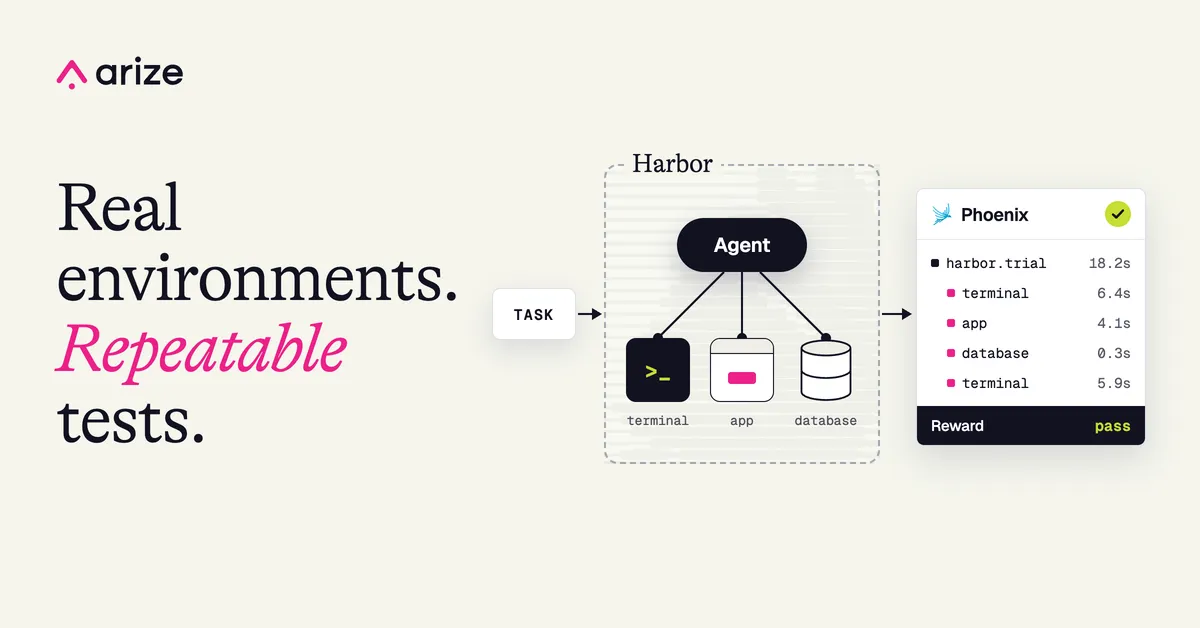
Harbor is the open-source framework behind coding-agent benchmarks such as Terminal-Bench. Users provide a task, an environment containing their application and data, and a verifier that checks success. Each attempt runs in a fresh sandbox, using local Docker or a supported cloud sandbox provider. After the agent finishes, the verifier runs tests to produce rewards.
For PXI, this meant running the real agent endpoint against a Phoenix server pre-seeded with traces. The team could then test what PXI did with real tool results and inspect the database afterwards.
Harbor also supports coding agents such as Claude Code and Codex alongside custom agents. Arize reuses the same tasks to test PXI, its MCP server and the Phoenix CLI. If an agent is asked to annotate failing traces, the verifier can check that annotations landed on the right database records. The agent's trajectory can also be inspected to count turns and tool calls. According to Arize, the same verifiers work across agents, measuring correctness and efficiency without prescribing how each agent must do the job.
Recording results in Phoenix
The Phoenix plugin for Harbor stores tasks as versioned datasets, each agent configuration as an experiment, and verifier rewards as Phoenix annotations. It converts Harbor's recorded trajectory into Phoenix traces, so teams can see the model calls, tool use and available usage data behind a reward without instrumenting the agent.
- All rewards from Harbor's verifiers are recorded as annotations.
- An infra_ok annotation is added to every run to flag execution errors.
- When tasks change, a new dataset version is created, while earlier experiments stay tied to the version they ran against.
Arize says the versioning helps separate an agent improvement from a change to the test. Results are also available through the Phoenix MCP server and CLI, so a coding agent can compare experiments or investigate traces while humans review the evidence.
What the traces revealed
Arize tested PXI, Claude Code and Codex on the same questions about a Phoenix project. Almost every answer was correct, but the traces showed meaningful differences in how each agent got there. In one trial, Codex correctly diagnosed a failing tool but followed Arize's error-analysis skill into a much longer workflow than the question required. The takeaway, per Arize, was to help the agent tell a quick diagnosis from a full investigation. The benchmark can now check whether such a change cuts turns and tool calls without hurting correctness.
What it means for teams building agents
Arize recommends a simple loop: pick one task users care about, give the agent a realistic environment, check the outcome, run a baseline, inspect the trace, then change a prompt, skill or tool and rerun. The company adds that optimizers such as GEPA, which use evaluation feedback to propose and test prompt changes, could automate parts of this, with Harbor tasks measuring the changes and Phoenix traces helping track their effects.
Teams that ship an MCP server, skills or a CLI can use the same approach to see whether agents use them effectively. Arize points to the Harbor integration guide and its internal benchmark suite as references, and says it will walk through the setup, including the PXI benchmark, in a live session on Oct 8, 2026.