CoreWeave to offer cloud instances with NVIDIA HGX H100 supercomputers
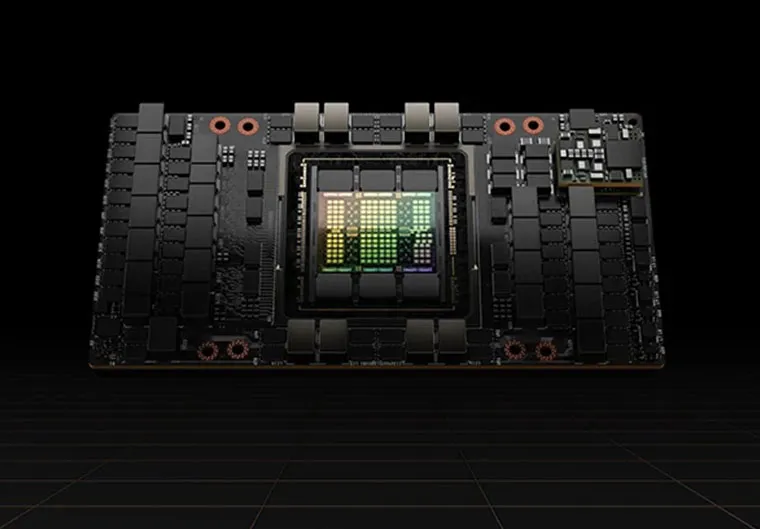
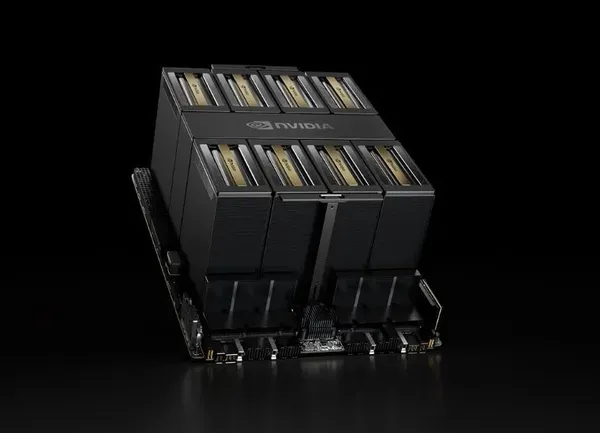
CoreWeave says it will be among the first providers to offer cloud instances built on NVIDIA HGX H100 supercomputers. The GPU cloud company is targeting AI and machine learning firms that train, scale and deploy large models.
- CoreWeave plans to offer cloud instances with NVIDIA HGX H100 supercomputers and says it will be among the first providers to do so.
- NVIDIA's platform is described as up to 9x faster for AI training and up to 30x faster for AI inference than the HGX A100.
- CoreWeave claims its pricing saves clients up to 80% versus large, generalized public clouds, with no payment for idle time.
- The service runs on Kubernetes-native infrastructure and supports open-source models such as Stable Diffusion, GPT-NeoX-20B and BLOOM.
- Customers can reserve H100 capacity now, but the source gives no prices or dates.
What CoreWeave is offering
CoreWeave announced plans to offer NVIDIA HGX H100 supercomputers to support what it calls cutting-edge AI and ML companies. According to the company, the offering is aimed at training, scaling and deploying next-gen models.
The H100 instances join a lineup that, according to CoreWeave, already includes A100s, A5000s, VMs, flexible storage and high performance networking. All of it is delivered through CoreWeave's Kubernetes-native infrastructure. The company describes itself as purpose-built for large-scale GPU-accelerated workloads and specialized for the most demanding AI and machine learning applications.
Customers can learn more about the HGX H100 or reserve capacity through the CoreWeave site.
Performance claims for the HGX H100
The performance figures in the announcement describe NVIDIA's platform, not CoreWeave's own benchmarks. The source says the HGX H100 enables up to seven times better efficiency in high-performance computing (HPC) applications, up to nine times faster AI training on the largest models and up to 30 times faster AI inference than the NVIDIA HGX A100.
The post also points to the lowest NVIDIA GPUDirect network latency in the market, delivered through the NVIDIA Quantum-2 InfiniBand platform. Together, the source says, these features reduce the training time of AI models to "days or hours instead of months."
Dave Salvator, Director of Product Marketing, NVIDIA Enterprise Infrastructure, is quoted in the post: "CoreWeave's new offering of instances featuring NVIDIA HGX H100 supercomputers will enable customers the flexibility and performance needed to power large-scale HPC applications."
Pricing model and software support
CoreWeave states that its pricing model saves clients up to 80% over large, generalized public clouds. It gives two reasons. First, clients pay only for the highly configurable HPC resources they use and never pay for idle time. Second, its Kubernetes-native infrastructure and networking architecture produce performance advantages, including what it calls industry-leading spin-up times and responsive auto-scaling, which let clients use compute more efficiently.
On the software side, CoreWeave says it uses a range of open-source Kubernetes projects and integrates with technologies such as Determined.AI. It also supports open-source AI models including Stable Diffusion, GPT-NeoX-20B and BLOOM.
What it means for customers
CEO and co-founder Michael Intrator framed the move as validation of the company's direction: "This validates what we're building and where we're heading." He said CoreWeave's success will keep being driven by making GPU-accelerated compute available to startup and enterprise clients alike, and that investing in the HGX H100 platform expands that commitment.
For AI teams, the practical takeaway is access to newer NVIDIA hardware from a specialized cloud provider, alongside older GPU options, with usage-based billing. The cost and speed advantages cited in the post are the companies' own claims, and the source does not give pricing details or availability dates.