CoreWeave Makes NVIDIA HGX B200 Instances Generally Available
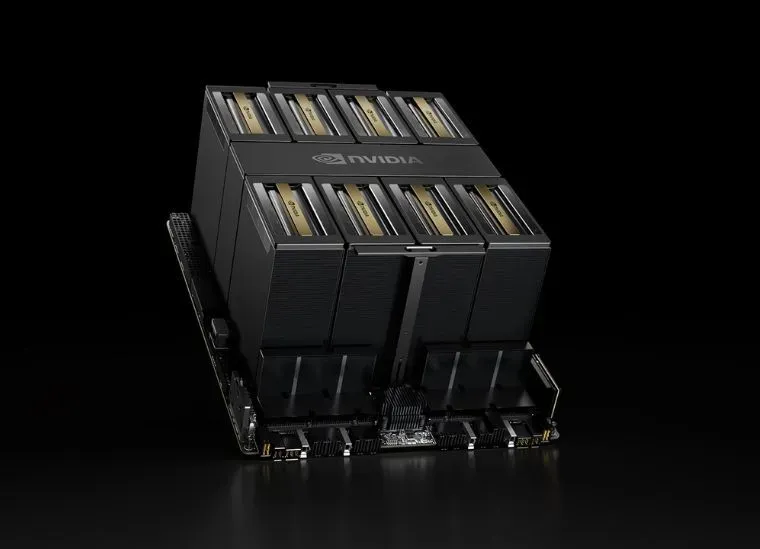
CoreWeave has made its NVIDIA HGX B200-based instances generally available, widening access to Blackwell hardware beyond the initial deployment for a single strategic customer. According to the company, the instances deliver upwards of 2x faster performance per GPU than the previous generation NVIDIA Hopper GPUs.
- CoreWeave has made NVIDIA HGX B200 instances generally available, following an initial deployment in February 2025.
- Each instance has 8 B200 GPUs with 180GB HBM3e each, 2 Intel Emerald Rapids 8562Y+ CPUs and 61.44TB of NVMe storage.
- CoreWeave claims up to 15x faster inference and 3x faster training than H100-based instances.
- Instances are available as b200-8x in the US-WEST-01A Availability Zone starting today.
- SUNK, CKS, Observe and Mission Control handle orchestration, monitoring and reliability.
From one customer to general availability
CoreWeave first deployed NVIDIA HGX B200 instances in February 2025. That deployment supported a strategic customer with more than 10,000 NVIDIA Blackwell GPUs over NVIDIA Quantum-2 InfiniBand networking. The new launch, the company says, "significantly broadens access" to the hardware.
CoreWeave positions the instances for AI training and real-time inference in enterprise AI workloads. Customers can provision them using the Instance ID b200-8x in the US-WEST-01A Availability Zone, starting from the day of the announcement. The company asks interested enterprises to contact it to reserve instances.
Hardware and performance claims
Each instance combines 8 NVIDIA B200 Blackwell GPUs, with 180GB of HBM3e memory each, linked through NVIDIA NVLink and NVLink Switch. It also includes 2 Intel Emerald Rapids 8562Y+ CPUs and 61.44TB of NVMe local storage.
For networking, each instance uses an NVIDIA BlueField-3 DPU and 8 NVIDIA ConnectX-7 InfiniBand host channel adapters. They connect to a 400G NDR non-blocking NVIDIA Quantum-2 InfiniBand fabric.
CoreWeave cites the following performance figures, compared with Hopper-generation systems:
- Up to 15x faster inference on models such as GPT-MoE-1.8T, versus H100-based instances.
- 3x faster training than H100-based instances.
- 2x faster query benchmarks than NVIDIA Hopper GPUs, helped by a dedicated decompression engine.
The platform supports FP4 and FP8 precisions through the second-generation Transformer Engine. These are vendor figures and the source does not describe the test conditions.
Software stack around the hardware
CoreWeave highlights several of its own tools for running the B200 systems. CoreWeave SUNK integrates Slurm and Kubernetes so customers can train and serve large models on the same B200 cluster. According to the company, it scales resources dynamically, shares compute between workloads and uses topology-aware scheduling to place jobs for GPU interconnect and data locality, which it says boosts Model FLOPs Utilization (MFU).
CoreWeave Kubernetes Service (CKS) is a managed Kubernetes offering for AI workloads. It runs the instances directly on bare metal servers, which CoreWeave says aims to deliver the lowest possible latency and highest throughput. Each HGX B200 cluster runs in its own private Virtual Private Cloud, and dedicated BlueField DPUs offload networking, security and storage tasks.
For monitoring, CoreWeave Observe provides per-GPU insight into metrics such as GPU XID errors, memory usage, GPU utilization, power and temperature. CoreWeave Mission Control combines automated monitoring with expert human oversight for reliability and resilience.
What it means for customers
For enterprises that want Blackwell capacity, the launch moves the B200 from a single large deployment to an offering available to more customers. Availability is currently listed for one zone, US-WEST-01A, and the source gives no pricing or details on other regions.
CoreWeave also cites its ranking as the #1 Platinum-rated AI Cloud in SemiAnalysis' ClusterMAX ranking as support for its infrastructure claims. Teams that want to run both training and inference on one cluster are the main audience for the SUNK integration.