Harvey rebuilds Review Tables to load thousands of documents page by page
Harvey has redesigned how its Review Table loads, fetching rows page by page from the server instead of pulling the whole table into the browser. According to the company's engineers, tables that used to break now load, and do so quickly.
- Harvey moved Review Table sorting and filtering from the browser to the server and loads rows page by page.
- Turbopuffer, running on Azure blobs, serves as the read store while Postgres stays the source of truth.
- Harvey built ID-based pagination because Turbopuffer has no built-in pagination.
- Loading happens in phases: skeleton, sort column values, then pages of rows.
- According to Harvey, latency improved across all table sizes and tables that used to break now load.
Why loading the full table stopped working
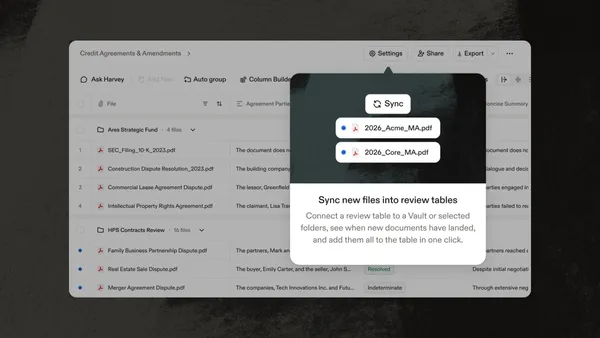
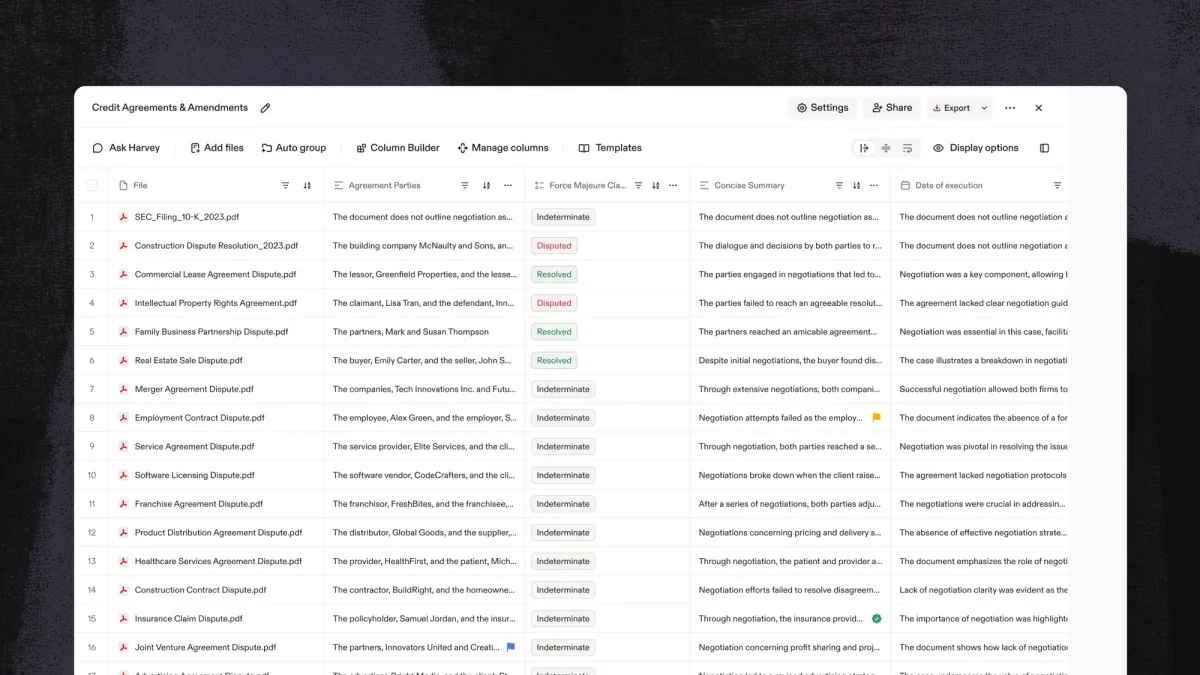
The Review Table is, in Harvey's words, its "largest, most exhaustive inference engine". Lawyers upload documents, ask questions in natural language and get results in a structured table. Rows correspond to individual documents and columns to the questions. Each cell answer includes the model's reasoning and is backed by citations from the source document.
The table is also meant to be collaborative. Rows can be assigned to colleagues, answers can be verified or locked, and users can leave comments. Once verified, a table can serve as a reusable source of truth for a later memo or presentation.
That workflow depends on the table staying responsive. Historically, the browser loaded the entire Review Table from the blob store and did all sorting, filtering and aggregation in memory. This worked for small tables, but problems appeared once a table passed thousands of rows. As teams began querying hundreds of columns across thousands of files, the engineers say the table sometimes lagged or became unresponsive, and in the largest cases browsers could run out of memory or fail to load it.
Two obstacles to simple server-side pagination
Server-side pagination looks like the obvious fix, but Harvey names two things that stood in the way.
- Sensitive data segregation. Only metadata lives in Postgres, while raw customer data lives in Azure blobs. Data therefore has to be fetched from Azure at request time, merged with Postgres data and passed to the client. Supporting pagination with filtering and sorting required a query interface on top of the Azure blob store.
- No suitable grid library. According to Harvey, no existing grid library supports the pagination scheme needed. The team built its own abstractions for page loading, covering grouping by folder path, sorting and filtering. It also rebuilt row selection and expanding or collapsing sections, which it no longer got for free from its current grid library.
Turbopuffer as the read layer
Harvey moved all client-side operations to the server. Postgres remains the source of truth, while a new data store provides the read interface, following a CQRS pattern. The team chose Turbopuffer, a vector data store that runs on top of existing Azure blobs. It supports vector search, full text search (BM25) and filtering through an inverted index, and it organizes data into documents within namespaces that have a strict schema.
Several issues had to be solved first:
- Pagination. Turbopuffer has no built-in pagination, so cursor-based and limit/offset approaches were ruled out. Harvey used ID-based pagination instead. The backend returns row IDs ordered as they would appear in the interface, and the client can request data for any list of row IDs. Sorting or filtering refetches that list.
- Data types. Currencies and dates must be sorted by value, not lexically. Because LLM responses do not always match a data type and Turbopuffer requires strict conformance, Harvey stores each such value twice, once as the strict type and once as a string.
- Schema drift. Failed writes could leave Postgres and Turbopuffer out of sync. When drift is detected, reads fall back to Postgres, and a backfill job repairs the affected namespace.
- Schema evolution. Core attributes such as timestamps and row status are shared by all tables and change over time, so the system needed a way to evolve the schema.
When a table is created, Harvey generates its skeleton of row, column and cell objects in Postgres, with sensitive data going to a segregated Azure blob, and derives the schema in Turbopuffer. Cell writes are batched to Turbopuffer.
A multi-phased loading strategy
The guiding principle is to reduce perceived latency. The frontend first requests a slim skeleton with table status, columns and file metadata. It then loads all values of the sort column, in sorted order, which lets users click anywhere along the scrollbar and jump to that part of the table. The default sort column is file names.
With those two pieces loaded, the table renders an outline with headers in the right order and loading animations in the cells. The frontend then calculates the row range for the current page, and the backend queries Turbopuffer and returns the rows. More pages are requested as the user scrolls, with a cap on how many rows are held in memory. Changing the sort column or adding filters repeats the process.
What it means for users
Harvey reports immediate latency improvements across all table sizes, with gains compounding on larger tables. For legal teams working on reviews of thousands of documents, the practical change is that the largest tables, which previously could fail to open, now load and remain usable while sorting and filtering are preserved.
Harvey: How We Made Review Tables Faster and More Reliable