Liquid AI releases d1.2 decision models with audio and vision tasks
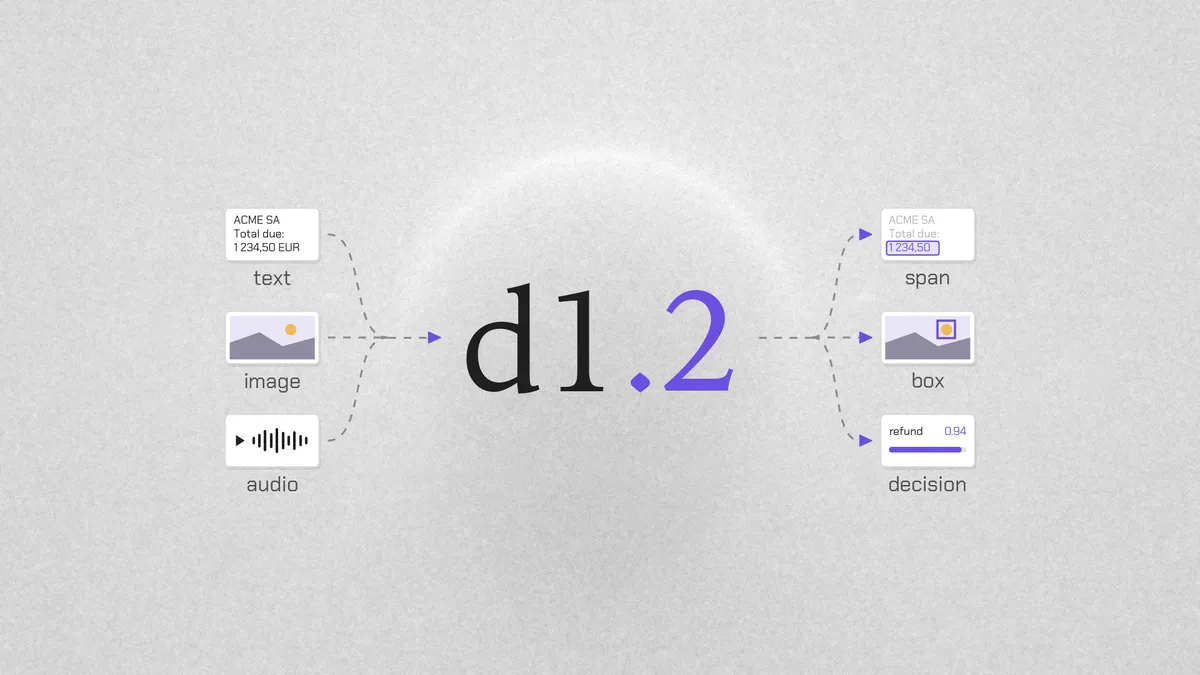
Liquid AI has released d1.2 and d1.2-ultra, updated decision models that add audio input and five new API tasks. The company says d1.2-ultra ranks first among decision models on the Artificial Analysis Decision Index v2.1.
- Liquid AI released d1.2 and d1.2-ultra with audio input.
- The models add five structured decision tasks for text and images.
- d1.2-ultra scored 75 and ranked first on the Artificial Analysis Decision Index v2.1.
- Both models are available today through the Liquid API.
- Liquid AI says the models are coming soon to OpenRouter and Vercel.
Five new ways to extract and assess information
The models can now read a value from text, such as the total on an invoice, and return the characters used to identify it. If the requested value is absent, they answer "not found" instead of guessing.
They can also find every passage of a particular kind in a document, including names, phone numbers and email addresses. For images, the models can locate one or every instance of an object by returning rectangles around the targets. Other new tasks estimate a number with a range, such as the number of people in a photo, and select every applicable option while providing a probability for each choice.
Audio input and benchmark results
d1.2 and d1.2-ultra accept audio as input. Users can ask about the recording, such as which language is spoken or whether a siren is present, and the question itself can also be recorded rather than typed. On held-out recordings, Liquid AI says both models answered 95% to 97% of questions about sounds from ESC-50 or spoken languages from FLEURS, which covers 43 languages.
On the Artificial Analysis Decision Index v2.1, d1.2-ultra scored 75, two points ahead of the previous best decision model. The index evaluates six benchmarks covering tasks such as extraction from resumes, receipts and research papers, tool calling and hard knowledge questions. It also accounts for confidence, making a confident incorrect answer more costly than a hesitant one.
Across 13 benchmarks and 22,505 questions answered by all five models, Liquid AI reports a calibration error of 0.8 points for d1.2-ultra and 1.2 for d1.2. Calibration measures the gap between a model's predicted probability and how often it is correct.
API availability and pricing
Both models are available today through the Liquid API. Users can call them as d1.2 and d1.2-ultra with a key from console.liquid.ai. The new answer types use the existing endpoint and request format, and both models bill input tokens only.
Liquid AI lists pricing at $0.02 for d1.2 and $0.042 per million input tokens for d1.2-ultra. Images are charged at 1.5 tokens per 32x32-pixel patch at the text rate, meaning a 1024x1024 image costs 1,536 tokens. Liquid AI says the models are coming soon to OpenRouter and Vercel.
For users building document, image or audio workflows, the release adds structured outputs for extraction, localization, counting and classification while retaining a single API format. Liquid AI has also provided an interactive trial through Liquid Console and linked to the full decision models documentation.
Liquid AI: d1.2: State-of-the-Art Omnimodal Decision Models | Blog