MedPAIR Tests Whether AI and Physicians Find the Same Medical Facts Relevant
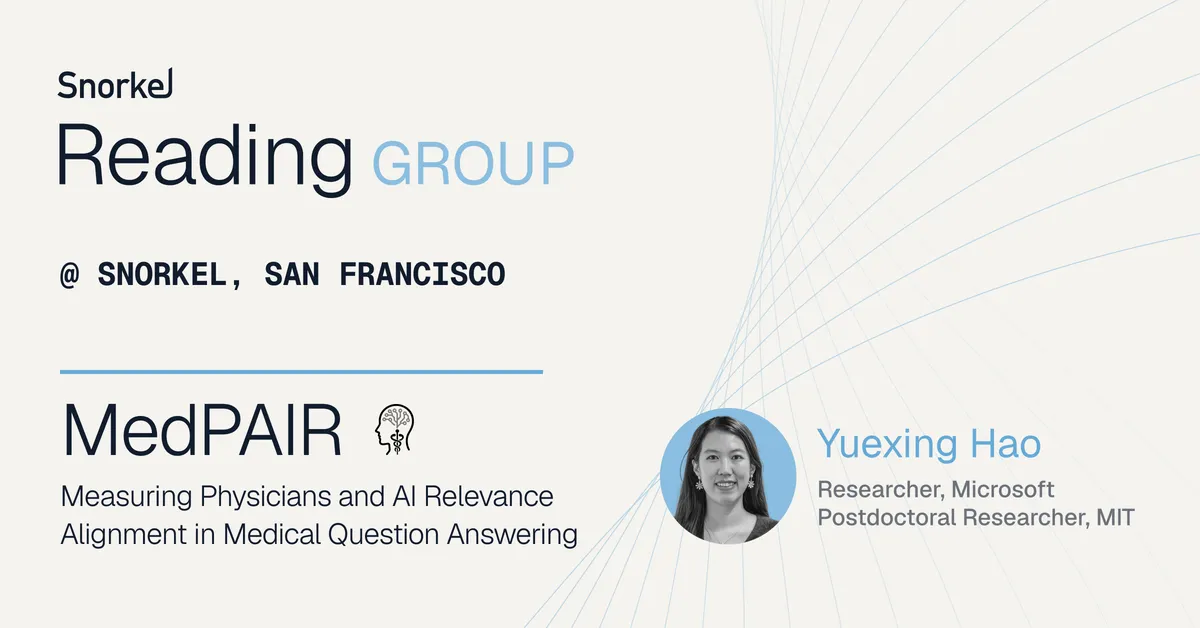
A new dataset called MedPAIR compares which parts of a clinical case physicians and large language models consider relevant. According to a Snorkel AI write-up of a reading group talk, physician trainees and board-certified physicians labeled every sentence in 933 medical exam questions, and six LLMs labeled the same sentences.
- MedPAIR compares which sentences physicians and six LLMs treat as relevant in 933 medical exam questions.
- 52 physician trainees and seven board-certified physicians took part in the annotation, recruited with Snorkel AI.
- Models gave self-reported relevance labels and context scores, computed with ContextCite for open-source models.
- The dataset is available on Hugging Face and was supported by Snorkel's Open Benchmarks Grants program.
- Hao will present a poster at Snorkel's Frontier Data Summit on October 8.
What MedPAIR measures
MedPAIR stands for Measuring Physician-AI Relevance Alignment. It was presented by Yuexing Hao, co-founder and COO of MatrAIx and previously a postdoc in MIT's Healthy ML Group, at a Snorkel AI Reading Group. The project asks a simple question: when a model answers a clinical question correctly, is it reasoning from the same evidence a physician would use?
Hao said the motivation dates to 2024, when she and her collaborators wondered whether large language models are deployable and why they should be trusted. She pointed to a 2024 Nature Medicine paper that found adding patient information, such as laboratory tests, imaging and physical examination results, could sometimes lower diagnostic accuracy. That led the team to ask whether physicians and models focus on the same information when they read the same patient context.
MedPAIR was supported by Snorkel's Open Benchmarks Grants program. Hao is a Cornell PhD, and she said she worked at MIT EECS under Professor Marzyeh Ghassemi during the last two years of her PhD. The collaborators she named also include researchers at Oxford, Google Research and HPI in Germany.
How the study works
The setup resembles USMLE-style multiple-choice questions. Each case has a patient profile, a question and several possible answers. In one example, the profile has six sentences describing a previously healthy 40-year-old man with a three-month history of a slowly enlarging right breast mass and associated pain, and the question asks for a diagnosis.
Judges labeled each sentence in the profile as highly relevant, low relevance or irrelevant. For the human side, Hao said the team worked with Snorkel AI to recruit 52 physician trainees and seven board-certified physicians. Annotators first had to answer the question correctly, otherwise their labels were not used. Labels were aggregated by majority vote.
Six language models, both open and closed source and none fine-tuned, produced two kinds of relevance judgments:
- Self-reported judgments produced from a prompt.
- Context scores showing how much weight the model gave each sentence when making its prediction, computed with ContextCite for the open-source models.
To keep the comparison fair, the team used the same sentence budget per question. It took the top sentences by the physician trainees' majority vote, then the same number of top sentences by each model's context scores.
The study has a second round that asks whether the sentences marked relevant are actually necessary. If only those sentences are kept and the rest removed, can a physician or model still answer correctly? The researchers also define a spurious rate, which looks at whether removing sentences labeled low relevance or irrelevant changes a model's answer.
Dataset and what comes next
The resulting MedPAIR dataset combines original questions from public benchmarks with physician-trainee annotations, model context scores and model self-reported relevance labels. It is available on Hugging Face.
In the talk, Hao tested three hypotheses with the audience: whether highly relevant sentences are consistently longer and more uniform, whether humans and models disagree on relevance, and whether human relevance judgments can improve model performance. The audience answered no to the first and yes to the second, and gave mixed responses on the third. The source text available here ends before the results are presented, so it does not report how the data actually came out.
Hao will present a poster on the work at Snorkel's Frontier Data Summit on October 8. Snorkel is also supporting a workshop at COLM on October 9, called DAIH: LLM/VLM Deployment Opportunities and Risks in Healthcare.
For anyone evaluating medical AI, the project shifts attention from final-answer accuracy to the evidence behind an answer. The dataset gives researchers a way to check whether a correct answer rests on the same sentences a physician would rely on.