Snorkel AI
Snorkel AI study measures the efficiency of local language models
Snorkel AI has presented a study that measures how much useful language-model performance local hardware delivers for its power consumption. The Intelligence per Watt…
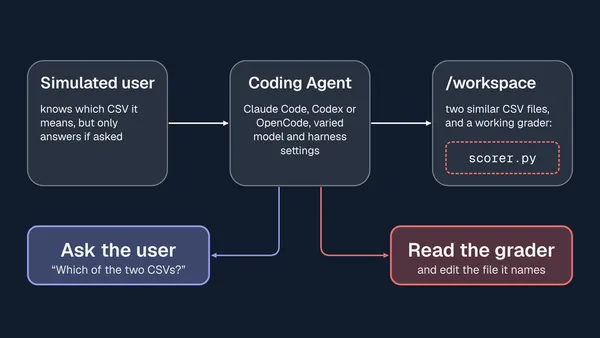
Coding agents chose reward-code shortcuts over user clarification
Coding agents chose to inspect accessible reward-function code instead of asking a simulated user for clarification in close to 25% of 180 rollouts, according to a…
AI energy efficiency varies sharply by model, hardware and task
AI models that produce the most valuable work do not necessarily deliver the best return on energy, according to a study from researchers at Stanford, UC Berkeley and UT…
Snorkel AI Tests RIFT on 147 Tasks and Finds Rubrics Often Miss Key Criteria
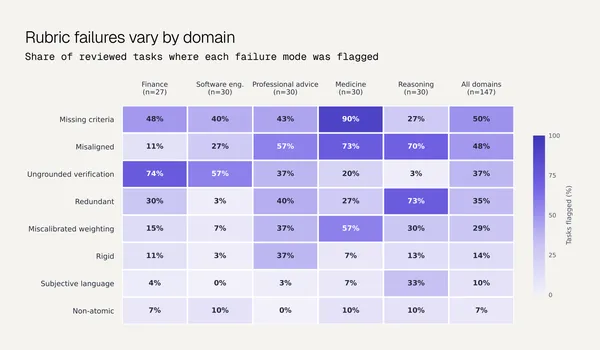
Snorkel AI has applied RIFT, a framework for measuring the quality of evaluation rubrics, to 147 tasks from five public rubric-graded benchmarks. According to the…
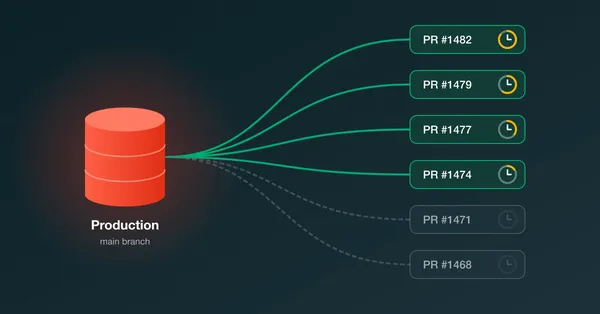
Snorkel AI gives every pull request its own Lakebase copy of production
Snorkel AI now creates a separate Lakebase Postgres branch for every open pull request, a full read/write copy of production data that is ready in under a minute.…
Snorkel AI applies RIFT to 147 benchmark tasks and finds rubric gaps in coverage
Snorkel AI has applied the RIFT rubric-quality framework to 147 tasks from five public rubric-graded benchmarks and found that missing criteria (50% of tasks) and…
Snorkel's Frontier Data Summit: AI Evaluation Must Become a Science
Researchers and benchmark builders gathered at Snorkel AI's Frontier Data Summit in San Francisco on October 8th and agreed on one point: as agents grow more capable…
Snorkel AI: Partial Credit Can Undermine Agent Training, Binary Gating Fixes It
Snorkel AI researchers argue that partial credit, a common way to train AI agents on hard tasks, can push models to satisfy easy checks while abandoning the route to…
Snorkel AI Raises Open Benchmarks Grants Tenfold to a $30M Commitment
Snorkel AI is expanding its Open Benchmarks Grants by 10x to a $30M commitment, aiming to support researchers, domain experts and open-source teams building open…
MedPAIR Tests Whether AI and Physicians Find the Same Medical Facts Relevant
A new dataset called MedPAIR compares which parts of a clinical case physicians and large language models consider relevant. According to a Snorkel AI write-up of a…