Meta's Muse Spark Open Debuts on Fireworks With US-Only Serverless
Fireworks AI has made Meta's open weights model Muse Spark Open available from day zero on its serverless platform, running on US-only capacity with no US premium. According to Fireworks, the 816B-parameter model leads a legal agent leaderboard and holds up well against much larger closed rivals on finance and clinical tasks.
- Fireworks offers Meta's Muse Spark Open from day zero on US-only serverless capacity with no US premium.
- The model has 816B parameters, 42B active per token, and a 1M-token context window.
- It ranks first of 75 models on Vals AI's Harvey Legal Agent Benchmark at 25.4%, versus 6.7% for Claude Opus 5.
- On AA-Omniscience it has a 33% hallucination rate, compared with 59% for Claude Opus 5.5.
- Zero Data Retention is the default, and fine-tuning is available via serverless LoRA training.
A large mixture-of-experts model built for long sessions
Muse Spark Open is an 816B-parameter mixture-of-experts model with 42B parameters active per token and a 1M-token context window, according to Fireworks. The company says it is built for long-horizon coding and agent work that has to stay coherent across very long sessions.
Fireworks calls it one of the most capable US open weights models to date and the strongest open weights model it has seen for regulated professional work. The model was trained and developed in the US, and Fireworks runs it with Zero Data Retention by default.
Results on legal, finance and clinical work
Fireworks highlights regulated fields, where accuracy matters most. The figures come from independent evaluators and from Fireworks' own Specialized Intelligence Index, where every model runs on the same harness.
- Legal: On Vals AI's leaderboard for Harvey's Legal Agent Benchmark, Muse Spark Open ranks first of 75 models at 25.4%, nearly 4x Claude Opus 5 (6.7%).
- Finance (Rogo): On Rogo's Big Finance Bench, it beat Claude Opus 5.5 at every difficulty level in Fireworks' runs. On the hardest tasks it edged out GPT-6 Astra (17.3% vs. 16.5%) and scored more than 2.5x Opus 5.5 (6.6%).
- Finance Agent: On Vals AI's Finance Agent v2 it scored 60.6%, within a point of Gemini 3.8 Flash at about 60% lower cost per test.
- Clinical documentation: It scored 90.1% on Vals MedScribe, within a point of Claude Opus 5 (91.0%), at 75-83% lower token prices.
Rogo reported its own run on Big Finance Bench, a set of 928 real financial workflow questions. There, Muse Spark Open scored 53.3%, the top open weights model on its board and ahead of Claude Opus 5 at 49.2%. Fireworks notes that third-party results from Vals AI and Artificial Analysis were measured on Meta's API release of the model.
Standard benchmarks and validation
On Artificial Analysis' AA-Omniscience, the model has a 33% hallucination rate, lower than Claude Opus 5.5 (59%) and GPT-6 Astra (51%). Fireworks attributes this to the model declining to answer when unsure instead of guessing.
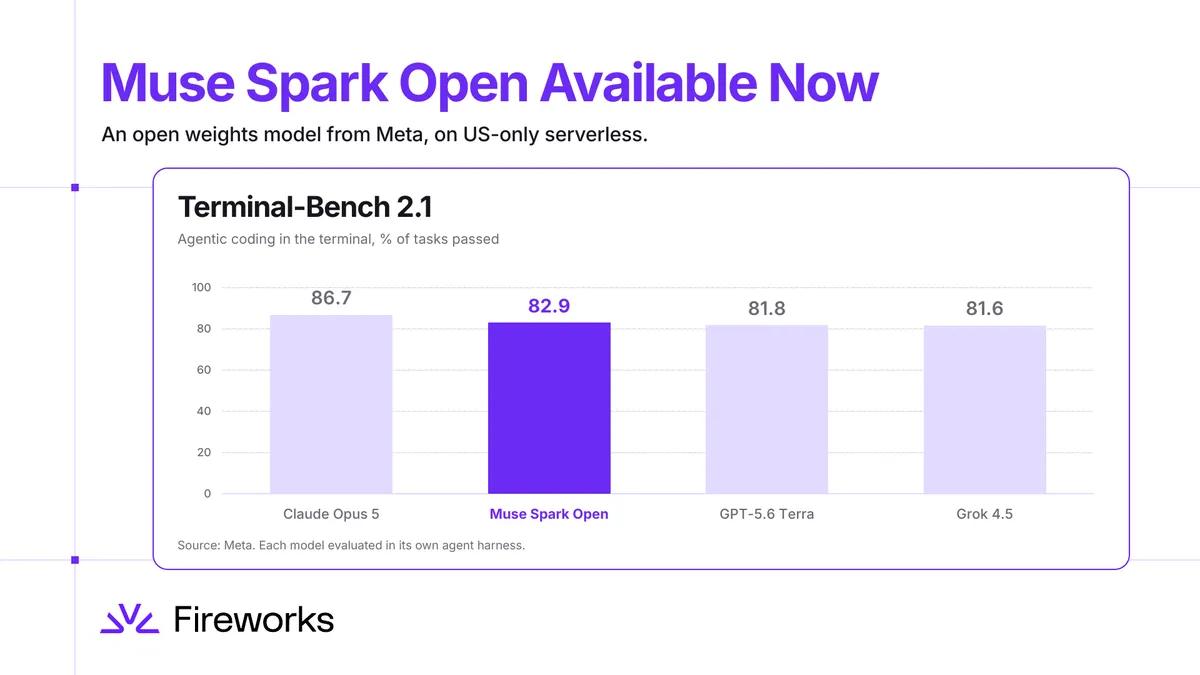
For agentic coding, Meta's own evaluations show 82.9% on Terminal-Bench 2.1, ahead of GPT-5.6 Terra and Grok 4.5. Each model there was evaluated in its own agent harness.
Fireworks also ran the final open weights through its launch validation suite on its production serving stack. The model scored 91.1% on AIME26, 89.7% on GPQA Diamond and 84.3% on SWE-bench Verified, and stayed above 80% on image understanding with OCRBench and MMMU Pro. The same weights run on SGLang, an open-source inference engine, produced matching scores. Fireworks cautions that agentic results depend on the harness and are not directly comparable to Meta's reported figures.
How to use it and what it means for builders
Muse Spark Open is available on the Fireworks serverless API today on US-only capacity, with no US premium. Teams can move to reserved throughput for production workloads, and fine-tune the model with the Serverless Training API. Fireworks points readers to the model page for current pricing and offers help through Fireworks Lab.
For organizations in legal, finance and healthcare that want US-developed open weights, the release pairs data retention defaults with customizable weights. Customers quoted by Fireworks, including Rogo, Filevine, Factory and Decagon Labs, describe the model as a foundation for tailoring and post-training. Most of the headline numbers are vendor-reported or come from Fireworks' own runs, so teams will want to test it on their own workloads.