Microsoft's StudentSim Simulates Individual Learners to Train AI Tutors
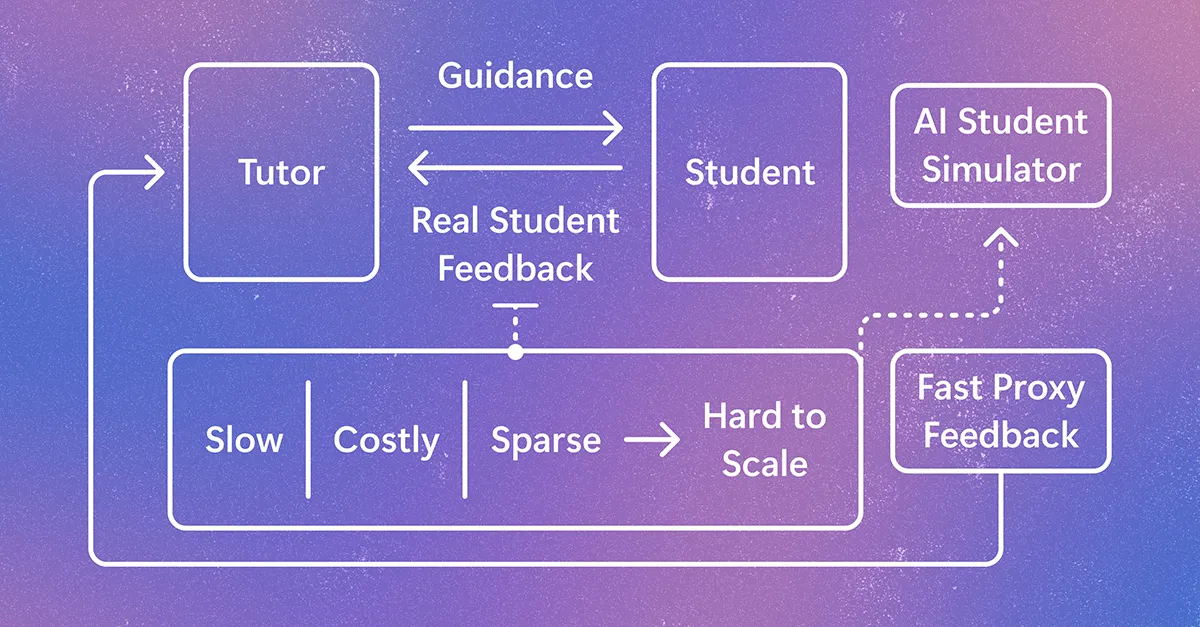
Microsoft Research has introduced StudentSim, a system that builds personalized simulators of individual students so AI tutors can be evaluated and trained before they are tested with real learners. According to Microsoft, it is a research system, not a product, and is not deployed in classrooms.
- Microsoft Research's StudentSim builds a personalized simulator for each student from de-identified, publicly available learner records.
- It is a research system, not a product, and is not deployed in classrooms or meant to replace teachers.
- StudentSimEval covers chess, second-language English writing and mathematics, scoring behavioral fidelity and guidance responsiveness.
- In chess, StudentSim scored 0.5150 and 0.9067, against 0.2316 and 0.7186 for GPT-5.4.
- A tutor trained with StudentSim rewards reached 90.5% accuracy, versus 75.7% without RL and 71.6% with a GPT-5.4 reward.
Why tutor research needs simulated students
Microsoft Research says AI tutoring tools need feedback from students to improve, but gathering it through human studies is slow, costly and hard to scale. The quality of teaching, the researchers argue, cannot be judged from the tutor's answer alone. What matters is what happens after the guidance reaches the student: whether the learner fixed the original mistake, whether a hint helped them reason toward the answer or gave away too much, and whether a different student would need different support.
StudentSim models how individual students answer questions and how those answers change after a tutor's guidance. The goal, according to Microsoft, is to make student feedback available during fast model iteration. The company stresses that the aim is not to replace teachers or classroom learning.
The work also introduces StudentSimEval, a benchmark and evaluation protocol covering chess, second-language English writing and mathematics. Microsoft says it uses only publicly available learner datasets released for research use, with de-identified records and no personally identifying information at any stage.
Two measures: behavior and responsiveness
A simple approach is to prompt a large language model to role-play a learner, for example as an elementary-school student who struggles with math. The researchers say the harder problem is keeping the learner's actual ability boundary. A model may sound like a young student while relying on knowledge far beyond that level, which can make a tutor look more effective than it is. Traditional knowledge tracing and behavior prediction models are grounded in real records, but many were not designed to take natural-language tutor guidance as input.
Drawing on Vygotsky's zone of proximal development, the gap between independent performance and performance with support, StudentSim defines two goals:
- Behavioral fidelity: whether a simulator matches a specific student's recorded responses on held-out problems.
- Guidance responsiveness: whether the simulator updates its response after reading tutor guidance.
Microsoft describes the two as complementary. A simulator that only matches past behavior may predict well but cannot show whether teaching helped, while one that always follows the tutor may fail to represent a particular student's likely mistakes.
Two-stage training and benchmark results
Because individual student records are sparse, training a separate model from scratch for each learner would risk overfitting. StudentSim instead trains in two stages. The first stage uses records pooled across many students in a domain to learn common response formats, errors and ways of revising after guidance. The second stage specializes the model on one student's own records.
In chess, the simulator predicts a player's next move and how they may revise after coaching. In second-language English writing, it generates essays with a learner's error patterns and predicts corrections after teacher feedback. In mathematics, it predicts a multiple-choice answer and whether the student updates after an explanation. All methods are compared on the same per-student training records and held-out evaluation records.
Microsoft reports that StudentSim outperforms leading baselines across the three domains. In chess, it reaches behavioral fidelity of 0.5150 and guidance responsiveness of 0.9067. GPT-5.4 scores 0.2316 and 0.7186, and Maia2, a chess-specific human move prediction model, scores 0.4535 and 0.2721. Microsoft says GPT-5.4 can respond to guidance but does not reliably match a specific student, while Maia2 predicts human moves more closely but has no natural-language guidance pathway.
Training a chess tutor with simulated feedback
The researchers also tested whether a simulator can supply a reward signal for tutor reinforcement learning. The tutor sees a position and a real student's earlier wrong move, then writes guidance. The simulator, with its parameters held fixed, reads it and produces a revised move. The reward is the improvement in move quality, measured with the Stockfish chess engine.
Three conditions were compared: a supervised fine-tuned tutor without reinforcement learning, a tutor rewarded using GPT-5.4 as the simulated student, and a tutor rewarded using StudentSim. All used the same tutor policy, starting point and setup. Human chess experts, blind to condition, rated the responses. According to Microsoft, the StudentSim reward produced the highest-rated tutor on all reported dimensions, with 90.5% accuracy versus 75.7% for the no-RL baseline and 71.6% for the GPT-5.4 condition. It also scored higher for guidance quality and personalization.
What it means
Microsoft calls the result a proof of concept that student simulators trained on real learner data can provide a useful feedback signal. The company frames it as an early-stage research signal, not a substitute for testing with real learners. For tutor developers, the approach points to a way to iterate faster before running costly human studies.
Microsoft Research: Simulating student learning for better AI tutoring