MLCommons Updates Its Mission to Standardize AI Measurement
MLCommons has updated its mission statement to "Standardize AI measurement and enable informed decisions", which the organization says reflects what has always been its core focus. It also announced organizational changes meant to support that mission, including a new fee structure and a push to bring AI deployers in as members.
- MLCommons updated its mission to "Standardize AI measurement and enable informed decisions".
- It describes its work as defining, building, operating, certifying, explaining, evolving and connecting benchmarks.
- It says it does not engage in pay-for-play "benchmarketing".
- Planned changes include a refactored fee structure and inviting AI deployers to become members.
- MLCommons is exploring benchmarking for efficiency, healthcare and financial services.
Why measurement matters, according to MLCommons
In a post titled "Our mission, updated," MLCommons argues that measurement is fundamental to responsibly unlocking the potential of AI. It describes modern AI systems as "the ultimate black boxes", saying they use intricate patterns across billions of numbers to generate sophisticated behavior, and that explanations of how they work remain vague and are becoming more complex every day.
The organization also points to cost. Training and operating AI systems is expensive and power-hungry, and MLCommons says better measurements make it possible to characterize both behavior and operational costs empirically. Its stated rule: if a characteristic of AI hardware, software or data matters to the value delivered, whether speed, power, reliability or quality, it aims to measure it.
According to MLCommons, this supports informed decisions about AI systems available today, enables cost-benefit tradeoffs, provides a "north star for innovation" and supports risk management such as assurance and insurance. It says its work benefits academic researchers, hardware and software vendors, deployers, end users and policymakers, and that it does this because it de-risks and grows the AI market.
Industrial-quality benchmarks and seven activities
MLCommons says it aims to develop and operate standardized measurements as industrial-quality benchmarks. These combine detailed protocols with artifacts such as test harnesses, held-out test data sets and evaluation models. The organization argues that, given the complexity and often subjective nature of AI testing, comparable results cannot come from multiple implementations built to a paper standard. Many artifacts must also be technically and legally protected to avoid overfitting, and measurements must evolve with the technology. That, it says, requires a trusted, sustainably operating organization. It positions its work as supporting standards bodies such as ISO, Appia, CoSAI and ADA.
The post lists seven activities: define, build, operate, certify, explain, evolve and connect.
- Define: set what is measured through a transparent community process. MLCommons states that it does not engage in pay-for-play "benchmarketing".
- Build: translate messy real-world use cases into rigorous test scenarios, including maintainable AI-driven evaluations for subjective benchmarks.
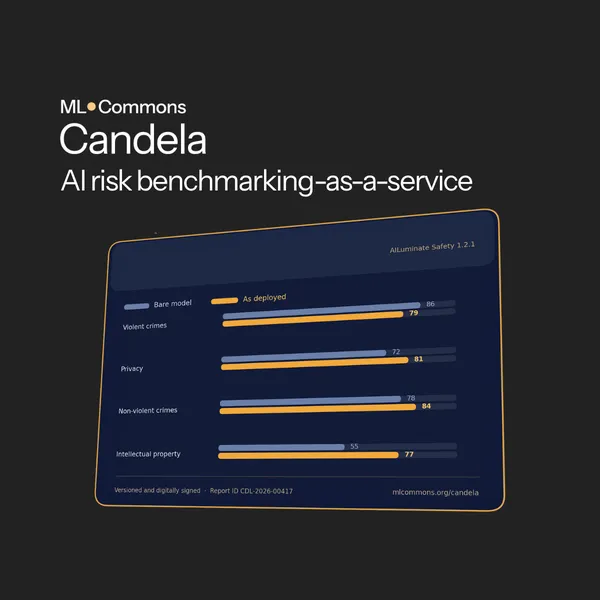
- Operate: turn a GitHub repo and dataset into a living instrument using infrastructure such as Candela and federated evaluation.
- Certify: validate results to provide third-party confirmation of performance claims, supporting purchasing, assurance, insurance and regulatory compliance.
- Explain: provide technical commentary, brief experts who consume the results and work with standards and assurance organizations.
- Evolve: track improving technology and intensifying threats so benchmarks keep showing differences between tested systems as those systems get better.
- Connect: link benchmarks to other standards organizations and emerging policy frameworks worldwide.
Planned organizational changes and what they mean
MLCommons says it will make organizational changes in the coming days and months. The list in the post:
- Improving its website and providing more supporting resources so consumers of results can find and use them more easily, as it is doing with MLPerf Endpoints.
- Promoting its benchmarks in new ways by adding product and marketing thinking to its board and staff and building out the Candela service.
- Aligning its work on performance and reliability at organizational and technical infrastructure levels, to help AI vendors and deployers deliver higher quality at lower cost and power consumption.
- Encouraging AI deployers, who are its members' customers today, to join as members, and refactoring its fee structure so costs scale more proportionately with benefits.
- Exploring benchmarking for critical markets such as efficiency, healthcare and financial services.
The announcement signals a shift in emphasis toward the people who buy and run AI systems, not only the vendors that build them. The invitation to deployers and the planned fee changes point to a broader membership base. The exploration of healthcare and financial services suggests possible new benchmark areas, though the post gives no timelines, prices or specific benchmarks for them. MLCommons says it welcomes ideas and feedback from its community as it carries out the changes.