MLCommons
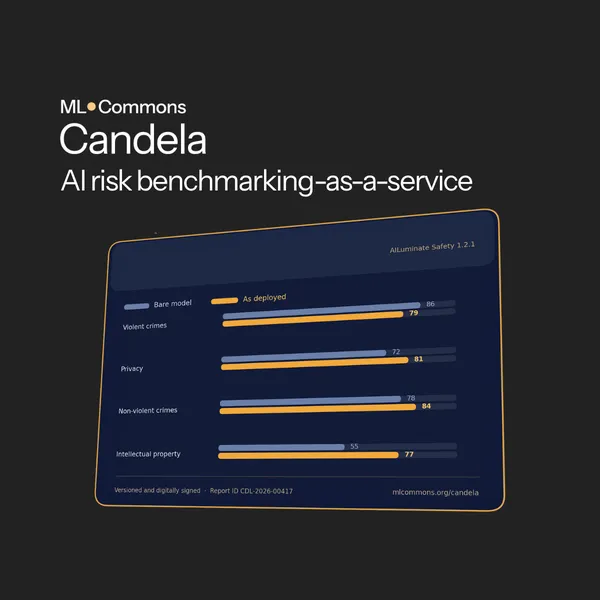
MLCommons Launches Candela, On-Demand AI Risk Benchmarking for Developers and Deployers
MLCommons has launched Candela, a benchmarking-as-a-service for AI risk and reliability that offers its AILuminate benchmarks on demand. The organization says it is…
MLCommons Launches Candela to Test AI Safety and Jailbreak Risks
MLCommons has launched Candela, a benchmarking-as-a-service product that lets developers and deployers run AILuminate Safety 1.2.1 and AILuminate Jailbreak 1.1 against…
MLCommons: Base Model Safety Scores Don't Carry Over to Deployed AI Systems
MLCommons says AI safety evaluation should stop assuming that a base model's safety score still applies once teams add system prompts, retrieval layers or fine-tuning.…
MLCommons to Build MLPerf Agents Benchmark With $3.5 Million NSF-Backed Award
MLCommons has been selected as the Benchmarking Team for the STRIDE Ventures AI Efficiency Challenge, a program supported by the U.S. National Science Foundation.…
MLCommons Updates Its Mission to Standardize AI Measurement
MLCommons has updated its mission statement to "Standardize AI measurement and enable informed decisions", which the organization says reflects what has always been its…
MLPerf Named Yardstick in EU AI Gigafactories Tender as Endpoints v1.0 Opens
MLPerf has been chosen as the performance standard for bids in the European Union's call for AI Gigafactories, according to MLCommons. The organization also said MLPerf…
MLCommons Releases Taxonomy of Five Privacy Risks Specific to AI Agents
MLCommons has released v0.1 of its Agent Privacy Risk Taxonomy, a framework that sorts the data protection risks specific to AI agents into five areas. The group says…