NVIDIA Vera Rubin NVL72 Leads MLPerf Agentic Inference Tests
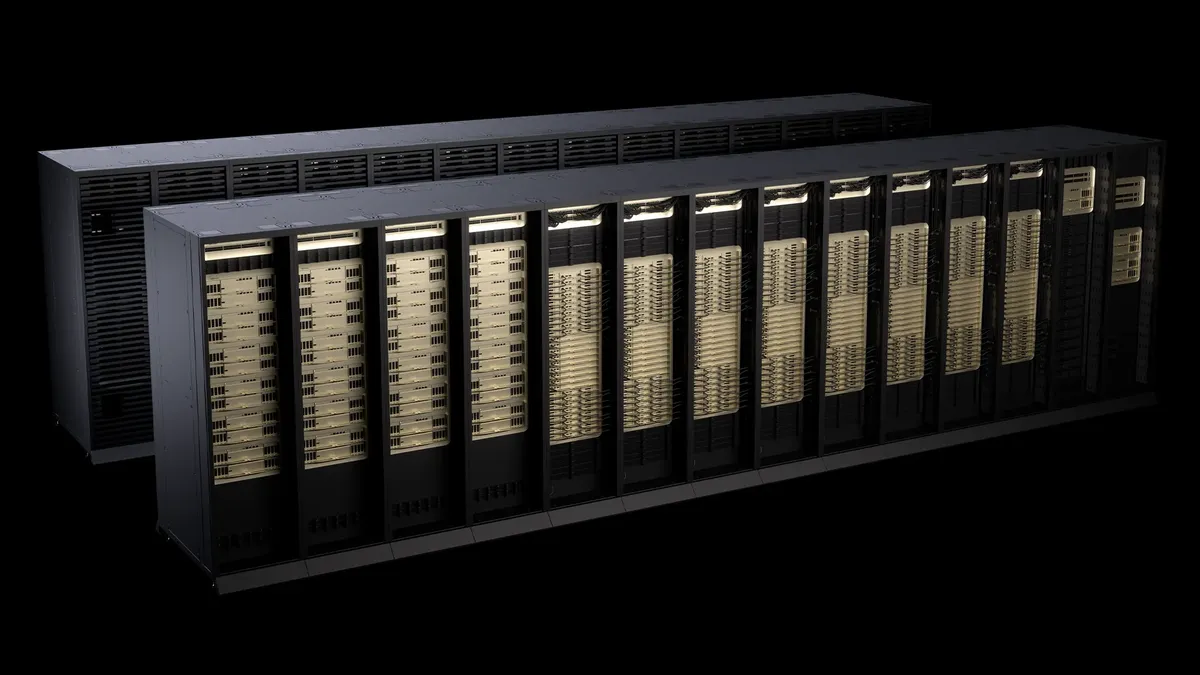
NVIDIA says its Vera Rubin NVL72 delivered 5x to 10x higher throughput per kilowatt than GB300 NVL72 across three agentic AI models in provisional MLPerf Endpoints v1.0 results. The comparisons also show 3x to 5x higher end-to-end interactivity at matched concurrency.
- Vera Rubin NVL72 posted 5x to 10x higher throughput per kilowatt across three models.
- End-to-end interactivity was 3x to 5x higher at matched concurrency.
- The tests covered Kimi K3, DeepSeek-V4.1-Flash and Qwen3.6-35B-A3B.
- Vera Rubin results are provisional and pending MLCommons Association verification.
Vera Rubin leads across three models
The results cover Kimi K3, DeepSeek-V4.1-Flash and Qwen3.6-35B-A3B. NVIDIA reports a 10x throughput-per-kilowatt ratio for Kimi K3, 9x for DeepSeek-V4.1-Flash and 5x for Qwen3.6-35B-A3B, compared with NVIDIA GB300 NVL72.
The comparison uses each platform’s best throughput per provisioned kilowatt at a stated minimum end-to-end average interactivity threshold. For Kimi K3, both platforms were compared at a shared minimum of 50 tokens per second per user. NVIDIA says Vera Rubin also achieved 3x to 5x higher end-to-end interactivity at matched query concurrency: 3x for Kimi K3, 5x for DeepSeek-V4.1-Flash and 3x for Qwen3.6-35B-A3B.
A workload designed for agentic systems
MLPerf Endpoints v1.0 evaluates the balance between serving capacity and responsiveness through coding and enterprise workflows accessed through API endpoints. The dataset reflects the demands of multi-turn agents, including growing conversation histories, reasoning, tool calls and responses.
During performance runs, generated tool calls and workflow intent are checked against reference values. Separate SWE-bench Verified evaluations assess end-to-end task-solving capability, according to NVIDIA. These checks are intended to evaluate whether faster serving preserves model quality.
In one Kimi K3 result, Vera Rubin NVL72 used 32 accelerators and recorded system throughput of 41,414.2 tokens per second at 100.89 kW. The GB300 NVL72 result used 48 accelerators and recorded 2,210.4 tokens per second at 60 kW. The reported Vera Rubin result had 50.4 tokens per second per user in end-to-end average interactivity, while the GB300 result had 56.2.
Hardware and software optimizations
NVIDIA says Rubin GPUs combine HBM4 memory, NVIDIA Tensor Cores and sixth-generation NVIDIA NVLink for agentic inference. HBM4 provides access to model weights and conversation state, Tensor Cores accelerate matrix operations, and NVLink supports communication across GPUs.
The company also points to context-aware serving techniques, including prefix caching, state reuse and NVIDIA Dynamo routing. These methods reuse prior computation and balance serving load across agentic workloads. Model-specific optimizations include DeepSeek’s MegaMoE kernel and Qwen’s multi-token prediction with Tensor Core verification, which NVIDIA says reduce data movement and sequential decoding steps.
The results remain provisional
The Vera Rubin figures were published as provisional results and are pending verification by the MLCommons Association. NVIDIA says they are subject to change pending peer review. The GB300 results were verified by the MLCommons Association.
For organizations running agents, the reported efficiency could allow more simultaneous agents within the same power budget while meeting a similar responsiveness requirement. The benchmark results therefore position Vera Rubin NVL72 as a platform aimed at the growing serving demands of multi-turn coding and enterprise workflows, although the final status of its MLPerf results remains unresolved.
NVIDIA Developer: NVIDIA Vera Rubin NVL72 Leads Agentic Inference Performance on MLPerf Endpoints v1.0