DSpark
EAGLE-4 speeds up prompt enhancement for image and video models
fal, working with Fireworks, has published a technical analysis of EAGLE-4, a speculative decoding method, together with a public benchmark for creative tasks. In the…
vLLM Speeds Up Kimi K3 Decoding on GB300 With Agent-Written Kernels
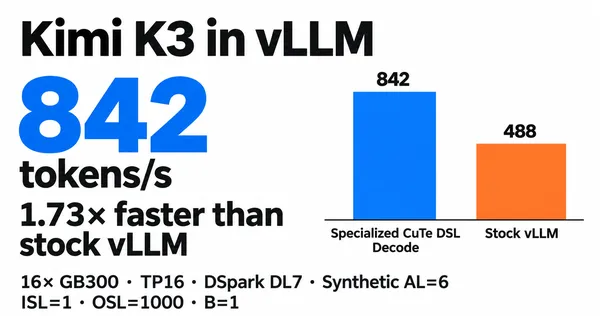
The vLLM team has published an optimized decode path for Kimi K3 on NVIDIA GB300 GPUs, built with help from coding agents. According to vLLM, it delivers over 840…
vLLM adds Adaptive Verification for draft models without a confidence head
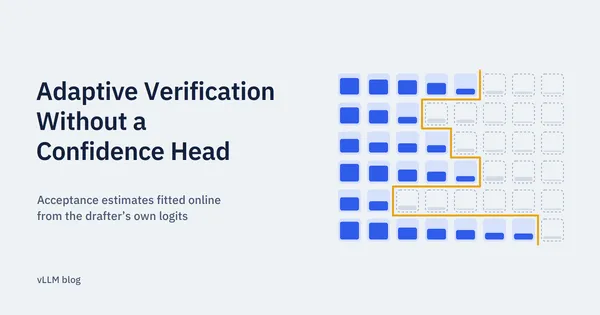
vLLM now supports confidence scoring for all draft-model-based speculator types, so Adaptive Verification no longer depends on a trained confidence head. An…