vLLM adds Adaptive Verification for draft models without a confidence head
vLLM now supports confidence scoring for all draft-model-based speculator types, so Adaptive Verification no longer depends on a trained confidence head. An online-fitted estimator predicts whether the target model will accept each draft token, according to the vLLM team.
- vLLM now supports confidence scoring for all draft-model-based speculator types, extending Adaptive Verification beyond DSpark drafters with a confidence head.
- A logistic regression on the log-odds of the drafter's top token needs K + 1 parameters and is fitted online from the target model's accept/reject decisions.
- The feature landed in PR #52228 and is enabled with enable_adaptive_verification.
- The shipped logit(q max) feature reached 0.8336 AUC and 0.0100 ECE on about 4.5M labeled drafts.
- Features based on the sampled token's probability scored higher AUC but were rejected because they bias the output distribution.
What changed in vLLM
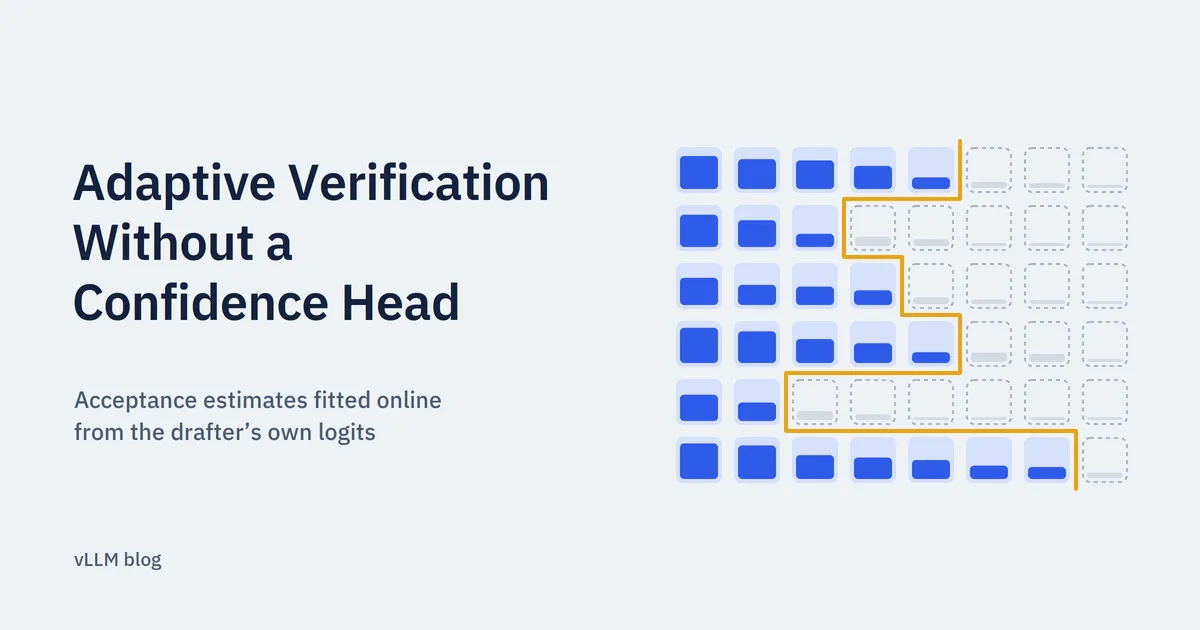
Adaptive Verification (AV) lets vLLM verify only a subset of the drafted tokens during speculative decoding. Draft tokens with a low probability of acceptance are trimmed from the batch before the target model's forward pass, which saves compute. According to vLLM, this is particularly useful at large batch sizes, where the GPU becomes compute-bound.
Until now, AV needed a per-token estimate of acceptance probability, so it only worked with DSpark drafters. Those models often ship with a confidence head, a small linear layer over the drafter's hidden state for each position, trained as a binary classifier for whether the target will accept a token.
The new feature landed in PR #52228 and is enabled with enable_adaptive_verification for draft models without a confidence head.
The problem with existing checkpoints
Drafters such as EAGLE, MTP, DFlash and some DSpark checkpoints have no confidence head and therefore missed out on AV entirely. Adding a head would mean retraining the drafter, which vLLM says is not an option for the many existing checkpoints people already serve.
Earlier work already used the drafter's own confidence as a proxy for acceptance. EAGLE-2 showed that EAGLE's draft probabilities closely track acceptance rates, and Draft & Verify stops drafting when probability falls below a fixed threshold. SpecDec++ trains a dedicated acceptance-prediction head. In each case the mapping from confidence to acceptance is either used as-is or learned offline. The vLLM team argues AV needs more than good ranking: its budget decision sums predicted acceptance probabilities and weighs them against measured costs, so the predictions must be calibrated for the specific model pair and workload.
How the online estimator works
The solution is a lightweight logistic regression that estimates each draft token's acceptance probability from a single scalar: the log-odds of the drafter's most likely token. It uses one shared slope and one intercept per draft position, so a drafter producing K tokens needs K + 1 parameters. The parameters are fitted online from the accept/reject decisions the target model already produces during normal verification, and they keep adapting to incoming traffic.
The team evaluated candidate features on four criteria:
- Losslessness: the feature must not bias the output distribution, which the team calls non-negotiable.
- AUC: how well the feature separates accepted from rejected drafts.
- Log-loss: how well predicted probabilities match true acceptance.
- Expected Calibration Error (ECE): how closely predictions match observed frequencies.
Measurements covered about 4.5M labeled drafts from serving DeepSeek-V4-Flash with DSpark (temp=1, top-p=0.95, conc=64), without AV, across SPEED-Bench 2k low/high-entropy, GSM8K, HumanEval and MT-Bench. The shipped logit(q max) feature scored 0.8336 AUC, 0.4284 log-loss and 0.0100 ECE. The trained confidence head scored 0.8191 AUC, 0.4449 log-loss and 0.0052 ECE.
Why some better-scoring features were rejected
Features based on q sampled, the probability of the token the drafter actually drew, reached higher AUC, for example 0.8553 for logit(q sampled). They were not used because trimming on them makes the verification decision depend on the drawn token itself. According to vLLM, this biases the emitted distribution toward the drafter's higher-confidence tokens and breaks the guarantee that speculative decoding outputs the target model's exact distribution.
The team also explains why it fits at all rather than using the drafter's top-token probability directly. Used as-is, that probability ranks drafts slightly better than the trained confidence head (0.8259 vs 0.8191 AUC), but it is poorly calibrated. Its mean prediction was 0.784 against an observed acceptance rate of 0.723, and its ECE of 0.0736 is 7x worse than the shipped feature's 0.0100.
What it means for users
For operators running EAGLE, MTP, DFlash or confidence-head-less DSpark checkpoints in vLLM, AV becomes available without retraining. In the team's words, "Any existing draft checkpoint gets AV for free." Because the coefficients are fitted from live traffic, the estimator is calibrated to the model pair and workload actually being served.
vLLM: Adaptive Verification Without a Confidence Head