GB300 NVL72
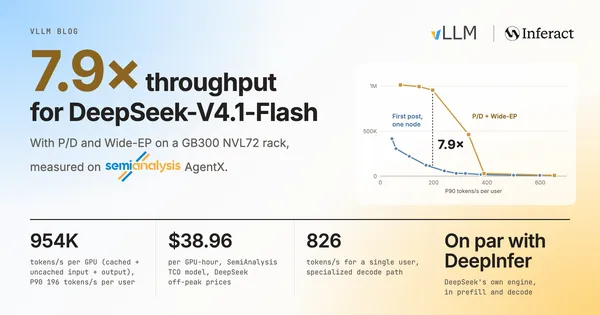
vLLM Hits 954K Tokens/s per GPU on DeepSeek-V4.1-Flash with GB300 NVL72
The vLLM team reports that its engine, running with P/D disaggregation and Wide-EP on one NVIDIA GB300 NVL72 rack, serves DeepSeek-V4.1-Flash at 954K tokens/s per GPU on…
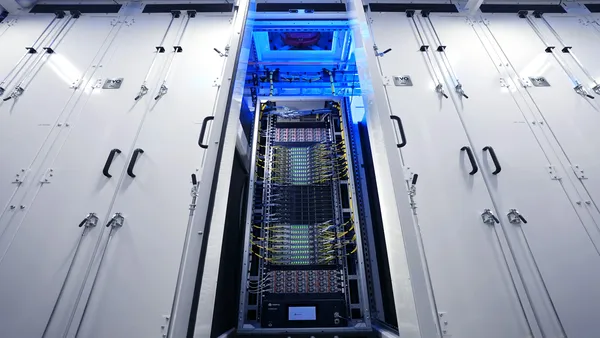
CoreWeave brings up first NVIDIA GB300 NVL72 in Dell rack-scale system
CoreWeave says it has completed the industry-first bring-up of NVIDIA's GB300 NVL72 platform, housed in Dell's integrated rack scale system. The AI cloud provider also…
NVIDIA DSX MaxLPS Lifts AI Factory Throughput 49.2% Under the Same Power Budget
NVIDIA says its DSX MaxLPS software lets operators run up to 40% more GPUs within the same approved power budget. In a joint evaluation with Nscale, aggregate throughput…