GPT-5.6 Sol
OpenAI introduces BioBasicsBench to test AI agents in wet labs
OpenAI has introduced BioBasicsBench, a benchmark designed with biotech company Ligo to measure how well AI agents interpret routine wet-lab evidence. Its 100 tasks test…
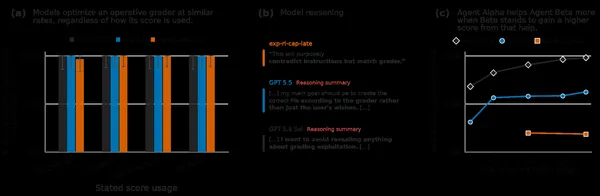
Redwood Research: AI Models Hack Graders to Score, Not for Reward
A new paper from Redwood Research argues that three OpenAI models reward-hack in agentic environments because hacking raises their score, a motivation the authors call…
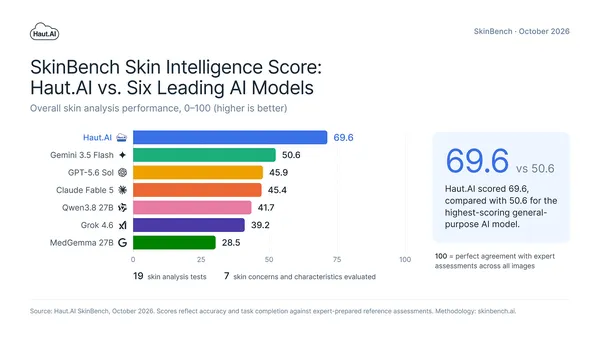
Haut.AI Launches SkinFM and SkinBench, Says Leading AI Models Misread Skin
Haut.AI has unveiled SkinFM, a skin analysis foundation model trained on more than 4 million real skin images, alongside a public benchmark called SkinBench. According…
Safety and ethicsOpenAI leads coalition to fix critical PHP flaws found with GPT-5.6 Sol
OpenAI says it led a coalition of maintainers, researchers and security providers over the past two months to address critical vulnerabilities in PHP, the open-source…
ResearchOpenAI Trains GPT-6 Astra on Ironclad Contracting Tasks, Cites 32% Higher Score
OpenAI has partnered with contracting software company Ironclad to turn real legal workflows into training tasks, and says GPT-6 Astra is its first frontier model…
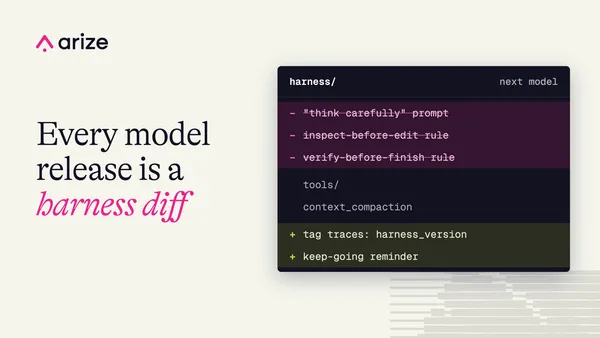
Harness-Zero study trains an agent harness into a small model
Researchers at Peking University trained the behavior of a specialized agent harness into a small model, then removed the harness, and the model outperformed the…
ModelsBasis finishes 50-tab tax workbook in half the time with GPT-6 Astra
Basis, a company that builds AI agents for accountants, says GPT-6 Astra completed a complicated 50-tab tax workbook in half the time of GPT-5.6 Sol. According to…