H100
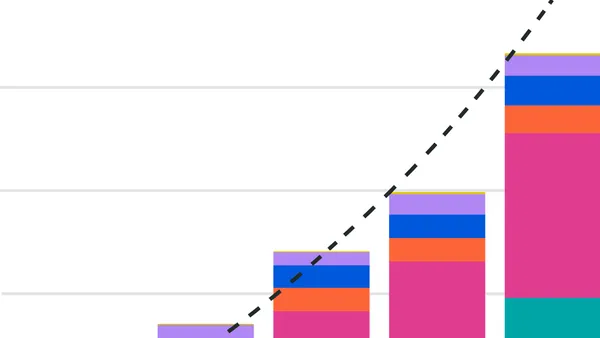
New AI computing capacity is doubling every 9 months, Epoch AI finds
The computing capacity of AI chips sold worldwide each quarter has grown about 2.5× per year since 2024, according to research group Epoch AI. That equals a doubling…
Aleph Alpha distills its parsing harness into Parsy, a single-pass model
Aleph Alpha has trained a specialized model called Parsy to replace its own multi-pass agentic parsing harness. According to the company, Parsy scores 87.9 on ParseBench…
Chips and infrastructureCoreWeave claims up to 20% higher GPU cluster efficiency than public benchmarks
CoreWeave says its AI cloud platform achieves Model FLOPS Utilization (MFU) above 50% on NVIDIA Hopper GPUs, which the company describes as up to 20% higher performance…
Ai2 replaces priority scheduler with GPU time budgets to fund high-impact research
Ai2 has replaced the priority-based scheduler on its GPU clusters with a system built on GPU time budgets, hierarchical fair-share allocation and a time-slicing…
Chips and infrastructureCoreWeave: Distributed File Storage Sustains 1 GiB/s per GPU in Tests
CoreWeave says benchmark tests of its Distributed File Storage show that one GiB/s per GPU can be sustained when scaling up to hundreds of NVIDIA GPUs in simulated AI…
Modal Clusters reach general availability with one-line multi-node GPU access
Modal has made Modal Clusters generally available, letting developers run multi-node GPU workloads through a single decorator, @modal.clustered. According to the…