vLLM
PyTorch Foundation adds nine members, including Nebius, Nscale and Shopify
The PyTorch Foundation, the Linux Foundation-hosted hub for open source AI, has added nine new members, with Nebius, Nscale and Shopify joining at the Platinum tier. The…
Nebius joins PyTorch Foundation as Platinum member, gets a board seat
Nebius, the Amsterdam-based AI cloud company, has joined the PyTorch Foundation as a Platinum member, according to a foundation announcement. The membership comes with a…
Google brings PyTorch-native vLLM and SGLang inference engines to TPU
Google has launched native PyTorch backends for vLLM and SGLang on TPU, built on a new runtime called TorchTPU. According to Google, the engines were developed with…
vLLM TorchTPU brings vLLM model serving to Google Cloud TPUs
The vLLM project has released vLLM TorchTPU (vllm-torchtpu), a new backend that runs vLLM on Google Cloud TPUs. According to the project, most models that already work…
Push-based KV transfer in vLLM cuts TTFT up to 3x in AWS benchmark
AWS has contributed a push-based NIXL connector to vLLM that moves KV cache transfer coordination off the critical path in disaggregated prefill-decode inference. In…
vLLM cuts Elastic EP scaling pause from 100 seconds to 0.82 seconds
The vLLM project says it has reduced the serving pause during Elastic Expert Parallelism reconfiguration to under two seconds. In its DeepSeek V4 Pro benchmark, scaling…
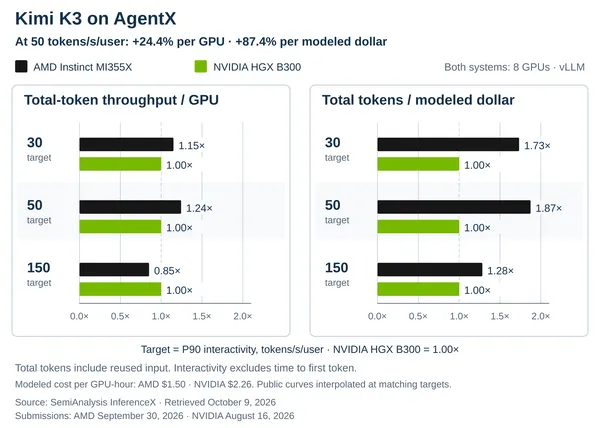
AMD MI355X Beats NVIDIA B300 per GPU on Kimi K3 AgentX Benchmark
An eight-GPU AMD Instinct MI355X system serving Kimi K3 with vLLM delivers 24.4% more total tokens per second per GPU than NVIDIA HGX B300 at 50 tokens/s/user P90…
vLLM Supports Reflection's 501B-Parameter Beam Model From Day 0
The vLLM inference engine now supports Reflection's Beam from day 0. Beam is a 501B-parameter mixture-of-experts model with 23B active parameters per token, and vLLM…
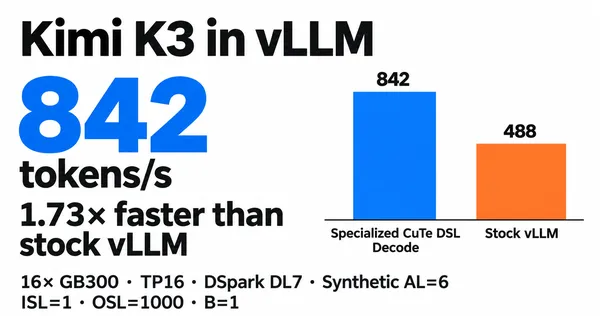
vLLM Speeds Up Kimi K3 Decoding on GB300 With Agent-Written Kernels
The vLLM team has published an optimized decode path for Kimi K3 on NVIDIA GB300 GPUs, built with help from coding agents. According to vLLM, it delivers over 840…
vLLM Adds Day 0 Support for NVIDIA's Nemotron 3.5 Super VL Multimodal Model
The vLLM project has announced Day 0 support for NVIDIA Nemotron 3.5 Super VL, an open multimodal model built for long-running agents that must read documents, images…
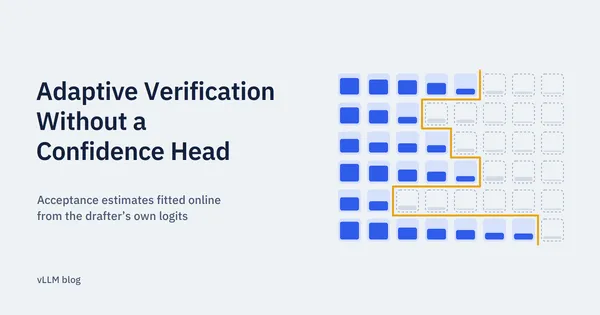
vLLM adds Adaptive Verification for draft models without a confidence head
vLLM now supports confidence scoring for all draft-model-based speculator types, so Adaptive Verification no longer depends on a trained confidence head. An…
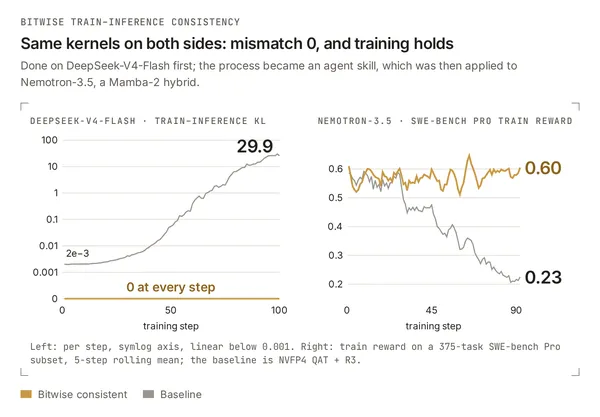
vLLM Makes RL Training and Inference Bitwise-Identical on DeepSeek-V4-Flash
The vLLM team says it has made reinforcement learning training and inference produce bitwise-identical logprobs for every sampled token on DeepSeek-V4-Flash, while…
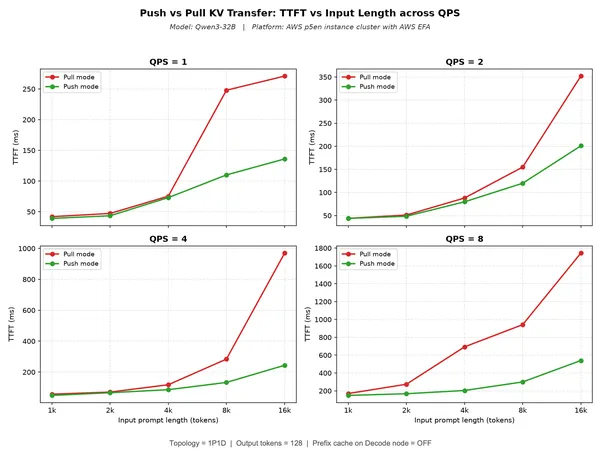
vLLM adds push-based KV transfer to cut TTFT in disaggregated inference
vLLM has introduced a push-based mode for its NIXL connector that moves post-prefill transfer coordination off the critical path in disaggregated inference. In a…
ReplaySSM Caches Inputs Instead of State to Speed Up Hybrid-Model Decoding
NVIDIA and the Dao AI Lab at Princeton University have detailed ReplaySSM, a technique that stores state-space model (SSM) state as a checkpoint plus a buffer of recent…
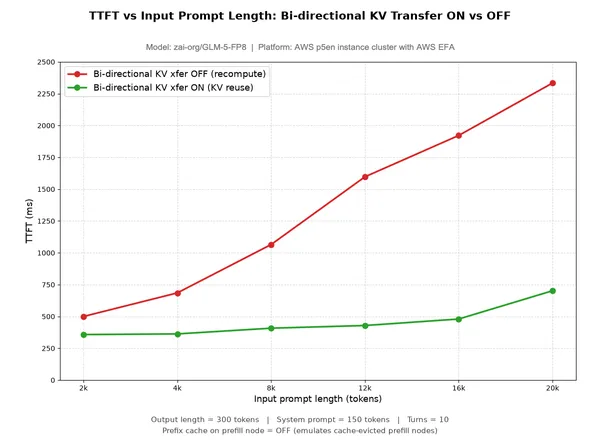
vLLM adds bi-directional KV transfer to cut TTFT in multi-turn agent workloads
vLLM has added bi-directional KV cache transfer for prefill-decode disaggregated serving, letting decode nodes send previously computed context back to prefill nodes on…
vLLM Adds Support for NVIDIA Vera Rubin NVL72, Cites 7.8x Throughput Gain
The open-source inference engine vLLM now runs on NVIDIA Vera Rubin NVL72, with daily container builds and support for models from DeepSeek, Moonshot AI, Z.ai and…
NVIDIA Dynamo adds session IDs so inference servers can follow AI agents
NVIDIA Dynamo now ties an agent's many model calls together with a single session-level identifier, so the inference server can treat them as one program rather than…
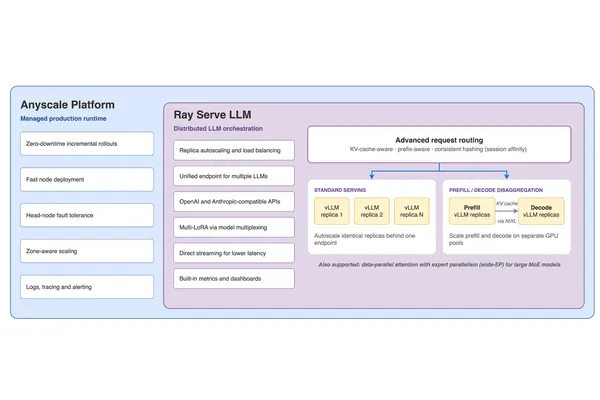
Anyscale: Self-Hosted Coding Agents on Ray and vLLM Cost a Fraction of API Pricing
Anyscale says teams can run coding agents on their own GPUs for a fraction of per-token API pricing, using vLLM, Ray Serve LLM and the Anyscale platform. In a new guide…
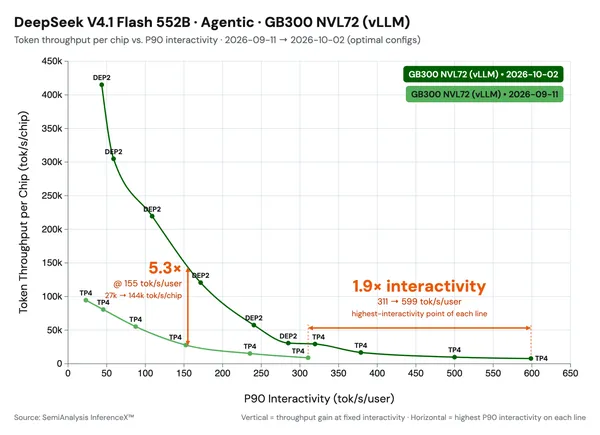
vLLM Gets DeepSeek-V4.1-Flash to 5.3x Throughput in Three Weeks
Inferact and the vLLM community say they have sped up DeepSeek-V4.1-Flash by 1.9x at low concurrency and raised throughput 5.3x under a 150 TPS constraint, within three…
Baseten's AI-built inference engine beats vLLM by up to 90% on Qwen decode
Baseten says an inference engine generated by an AI agent outperformed vLLM 0.25.1 by up to 90% on single-stream decode speed for Qwen-3.6-35B-A3B in NVFP4 precision on…
For developersHelion Brings Autotuned GEMM Kernels to vLLM, Beating CUTLASS and DeepGEMM on Hopper
The PyTorch team has integrated Helion, its Python-based kernel DSL, into vLLM's linear backend. According to the team, on NVIDIA Hopper GPUs it outperforms the vLLM…
Red Hat backs OpenClaw Enterprise as open control plane for AI agents
Red Hat says it is contributing to OpenClaw and the newly announced OpenClaw Enterprise, an open source control plane for deploying and operating persistent AI agents…
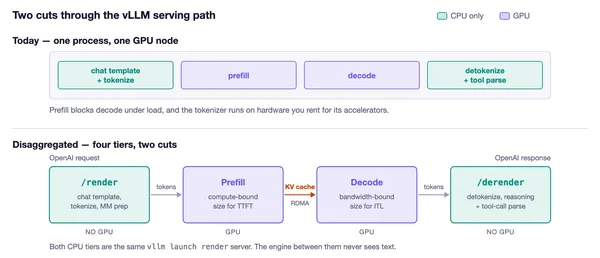
vLLM Guide Shows When Splitting Prefill and Decode Pays Off
The vLLM project has published a practical guide to disaggregated serving, which separates prompt processing, token generation and CPU-side work into different tiers.…