CoreWeave Rolls Out Large-Scale NVIDIA Blackwell Clusters for AI Customers
CoreWeave says it is among the first providers to bring large-scale NVIDIA Blackwell clusters to market, with two configurations: the NVIDIA HGX B200 and the NVIDIA GB200 NVL72. Both are connected with NVIDIA Quantum-2 InfiniBand networking, according to the company.
- CoreWeave says it is among the first to deliver large-scale NVIDIA Blackwell clusters to market.
- Two configurations are offered: NVIDIA HGX B200 and NVIDIA GB200 NVL72, linked by Quantum-2 InfiniBand.
- GB200 NVL72 connects 36 Grace CPUs and 72 Blackwell GPUs and is liquid-cooled.
- CoreWeave claims up to 30X faster real-time trillion-parameter LLM inference for GB200 NVL72 and 15X for HGX B200.
- The company positions its fully managed infrastructure as a way to cut DevOps overhead.
Two Blackwell configurations
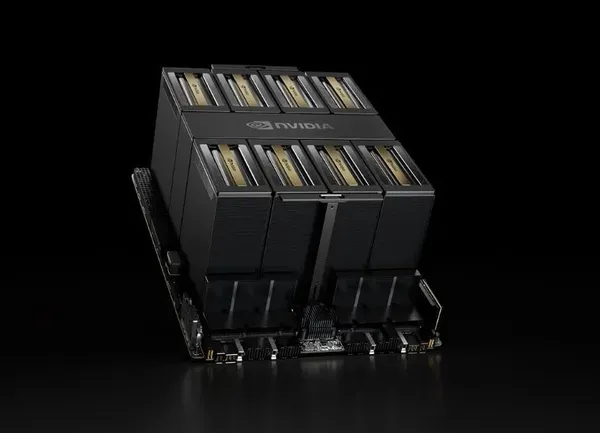
CoreWeave describes its offering as large-scale NVIDIA Blackwell clusters in two forms. The first is the NVIDIA HGX B200, which the company says is designed for the most demanding AI, data processing and high-performance computing workloads. It is an x86 platform powered by NVIDIA Blackwell GPUs and, according to CoreWeave, features 15X faster real-time inference on trillion-parameter models.
The second is the NVIDIA GB200 NVL72, a liquid-cooled, rack-scaled solution. It connects 36 NVIDIA Grace CPUs and 72 NVIDIA Blackwell GPUs and delivers up to 30X faster real-time trillion-parameter LLM inference, the company says. All systems are interconnected with ultra-fast NVIDIA Quantum-2 InfiniBand networking.
Why CoreWeave says the gap exists
CoreWeave frames the launch against what it sees as a gap in the cloud market. In its view, customers running large-scale AI and machine learning workloads on legacy hyperscalers spend valuable time building and retrofitting their stack on general-purpose clouds just to get started. Alternative clouds, it argues, tend to focus on smaller projects and cannot supply the compute scale needed to deploy enterprise-grade large language models.
The company says this is why it began building what it calls the first-ever AI Hyperscaler, focused on high-performance, scalable and secure fully managed infrastructure for AI/ML customers. It points to tools its teams built for automated node health-checking, fast model copying and loading, and streamlined workload management. CoreWeave also says customers get unprecedented visibility into their clusters and that its engineers work with customer teams to resolve issues quickly.
Beyond training and inference
The post notes that NVIDIA introduced its Blackwell architecture at NVIDIA GTC earlier this year. Blackwell can link up to 72 GPUs in a single NVIDIA NVLink domain, which CoreWeave says brings greater GPU-to-GPU communication bandwidth for training and deploying massive models.
According to the company, this opens up use cases far beyond AI training and inference, such as quantum computing, drug discovery and fusion energy. CoreWeave adds that scientific computing and physics-based simulations are positioned to make large strides as AI powers the next breakthroughs.
What it means for customers
CoreWeave pitches the clusters to teams that want to avoid infrastructure overhead. With its fully managed approach, the company says customers can spend less time on DevOps and more time deploying workloads and taking their products to market faster. It also says customers get more control and visibility over their clusters, and that its proprietary software, purpose-built for AI, is meant to ensure maximum resource performance and efficiency.
The source does not give pricing, availability dates or customer names. Interested companies are directed to contact CoreWeave to discuss a partnership. The performance figures cited are claims from CoreWeave's post.