NVIDIA Blackwell
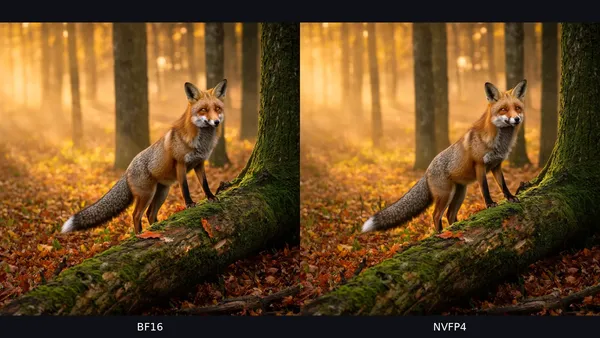
NVIDIA reports up to 4.45x faster FLUX 3 image generation
NVIDIA says its TensorRT LLM VisualGen runtime can accelerate FLUX 3 Image Klein generation by up to 4.45x for image-to-image workloads on a single Blackwell GPU. The…

PyTorch 2.15 makes rewritten NCCL backend the default and adds FP8 on Apple Silicon
PyTorch 2.15 is out, and the rewritten NCCL backend now runs every nccl process group by default. The release also adds one-sided transports to torch.distributed, finer…
C-BRAIN and NVIDIA Use Open Source AI to Speed Up Dementia Research
The Consortium for Biomedical Research and AI in Neurodegeneration (C-BRAIN) is working with NVIDIA to apply AI to Alzheimer's research, using open source tools that…
CoreWeave Makes RTX PRO 6000 Blackwell Server Instances Generally Available
CoreWeave has made instances based on the NVIDIA RTX PRO 6000 Blackwell Server Edition generally available, and says it is the first cloud provider to do so. The…
Chips and infrastructureCoreWeave Rolls Out Large-Scale NVIDIA Blackwell Clusters for AI Customers
CoreWeave says it is among the first providers to bring large-scale NVIDIA Blackwell clusters to market, with two configurations: the NVIDIA HGX B200 and the NVIDIA…
CoreWeave Makes NVIDIA HGX B200 Instances Generally Available
CoreWeave has made its NVIDIA HGX B200-based instances generally available, widening access to Blackwell hardware beyond the initial deployment for a single strategic…
vLLM Supports Reflection's 501B-Parameter Beam Model From Day 0
The vLLM inference engine now supports Reflection's Beam from day 0. Beam is a 501B-parameter mixture-of-experts model with 23B active parameters per token, and vLLM…
BusinessDigi Power X Gets $200M Debt Commitment for Alabama AI Data Center
Digi Power X Inc. says it has received a commitment letter for US$200 million in debt financing to support its 40 MW AI data center in Columbiana, Alabama. The financing…
Baseten Explains How to Pick Which Layers Run at 4 Bits in NVFP4
A high-quality NVFP4 quantization depends on deciding which layers of a model can run at 4 bits and which need more precision, according to a Baseten blog post published…
CoreWeave Outlines How Its AI Data Centers Tackle Power, Scale and Uptime
CoreWeave has published its capacity plans for its data centers, arguing that purpose-built, liquid-cooled facilities are needed to meet the demands of AI megaclusters.…