CoreWeave Makes RTX PRO 6000 Blackwell Server Instances Generally Available
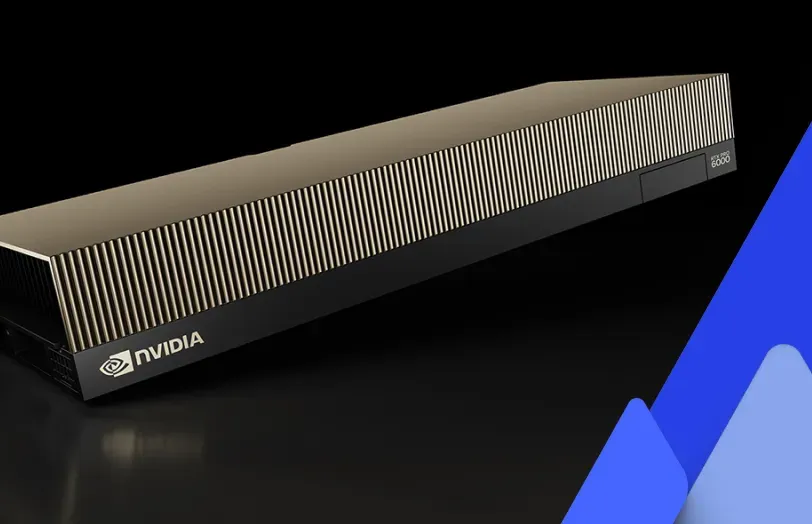
CoreWeave has made instances based on the NVIDIA RTX PRO 6000 Blackwell Server Edition generally available, and says it is the first cloud provider to do so. The instances target AI, graphics and high-performance computing workloads and are offered in the US-EAST-04 region.
- CoreWeave says it is the first cloud provider to offer generally available NVIDIA RTX PRO 6000 Blackwell Server Edition instances.
- The instances are available in the US-EAST-04 region, with up to 8 GPUs, dual Intel Emerald Rapids CPUs and BlueField-3 DPUs.
- CoreWeave cites up to 5.6x faster LLM inference and 3.5x faster text-to-video generation than the L40S, based on NVIDIA preliminary projections.
- Each GPU has 96GB of GDDR7 memory at 1.6TB/s, and instances include over 7TB of local NVMe storage.
- Access is via CKS and SUNK; no pricing was given in the announcement.
What CoreWeave is offering
According to CoreWeave, the new instances are aimed at enterprises and startups working on generative AI, real-time rendering and large language model (LLM) development. The company describes its infrastructure as purpose-built to let customers get the most out of the NVIDIA Blackwell architecture.
Each instance supports configurations of up to 8 GPUs. They are paired with dual Intel Emerald Rapids CPUs and NVIDIA BlueField-3 DPUs. CoreWeave says the DPUs provide more secure VPC isolation and low-latency networking in multi-tenant environments, and that they offload network tasks from the CPU so that compute resources remain free for AI and GPU-heavy workloads.
The instances also include over 7TB of high-speed local NVMe storage. CoreWeave says this gives rapid access to large models, datasets and assets and reduces data retrieval latency for inference and graphics-intensive jobs.
Performance claims versus the L40S
The RTX PRO 6000 Blackwell Server Edition is presented as a substantial step up from the previous NVIDIA L40S generation. CoreWeave cites up to 5.6x faster LLM inference and 3.5x faster text-to-video generation. The listed hardware includes 96GB of GDDR7 memory at 1.6TB/s bandwidth, fifth-generation Tensor Cores for FP4 precision and fourth-generation RT Cores.
- 3.8 PFLOPS of FP4 AI performance for agentic AI, LLM inference and generative workflows
- Over 5x LLM inference throughput compared with the L40S
- Over 2x faster fine-tuning compared with the L40S
A footnote in the announcement says the inference comparison is based on NVIDIA preliminary performance projections from April 2025, using Llama3 70B at 8K/256, 20 t/s/usr, 2s FTL on 8 GPUs, with the RTX PRO 6000 at FP4 against the L40S at FP8. These are vendor figures, not independent benchmarks.
An earlier CoreWeave post announcing the instances as coming soon cited up to 5.3x faster LLM inference, so the figure has changed between the two announcements.
Platform and software integration
CoreWeave says the instances are available through both CoreWeave Kubernetes Service (CKS) and Slurm on Kubernetes (SUNK), which it describes as working together to simplify orchestration of containerized applications. CoreWeave AI Object Storage (CAIOS) and Local Object Transport Accelerator (LOTA) integrate with the instances to provide high-throughput data access and intelligent caching for large-scale training and inference pipelines.
The instances are also supported by CoreWeave's Observability services, which offer granular monitoring of GPU utilization, system errors, temperatures and other logs so customers can detect and resolve problems quickly.
The company points to its earlier work with NVIDIA HGX H200 and NVIDIA GB200 NVL72 deployments as part of its record of bringing new compute online quickly. It also says SemiAnalysis ranks it as the #1 AI Cloud, including the exclusive Platinum ClusterMAX rating.
What it means for customers
Customers who want RTX PRO 6000 Blackwell capacity can now request it from CoreWeave in the US-EAST-04 region. The company says enterprises can use it to accelerate AI training, reduce latency and scale deployments for AI and graphics workloads. The announcement does not give pricing or details on capacity in other regions, and it directs interested customers to contact CoreWeave to deploy the instances.