Baseten
Baseten cuts GLM-5.3 delta weight sync from 36 to 15 seconds
Baseten says a delta weight sync for a roughly 770 GB GLM-5.3 checkpoint now takes 15 seconds with a 0.8-second request pause, down from 36 seconds and 6 seconds in its…
Baseten adds autoscaling schedules to cut cold-start delays
Baseten has introduced autoscaling schedules, a feature that raises the minimum number of replicas ahead of predictable traffic so that requests do not wait on cold…
Baseten and Postman Team Up to Help Enterprises Run Agents in Production
Baseten has announced a partnership with Postman to help enterprises ship AI agents to production. Postman supplies the tools to build and operate agent workflows, while…
Baseten launches joey-1, a 2B decision model with 20 ms latency
Baseten has released joey-1, a 2B-parameter decision model that, according to the company, serves an average 2,000-token request at a P50 end-to-end latency of 20 ms. It…
Baseten Serves Qwen3-ASR 7x Faster for Batch Transcription
Baseten says its optimized serving stack for Qwen3-ASR 1.7B transcribes 7x more audio per second than out-of-the-box vLLM at high concurrency on a single RTX PRO 6000.…
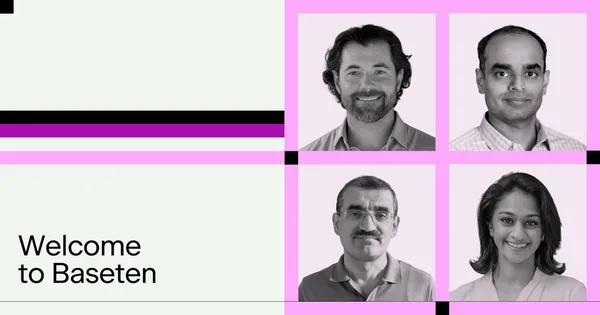
Baseten hires four engineering leaders from Google, Meta, Anyscale and Databricks
Baseten has brought on four engineering leaders: Bryan Vann, Ilina Mitra, Jaikumar Ganesh and Rahmi Marasli. According to the company, they will help grow its…
Baseten Launches BDN Sealed Volumes to Keep Model Data Consistent
Baseten has released BDN Sealed Volumes, a feature that lets teams publish read-only data once and mount it in any deployment. According to the company, it is available…
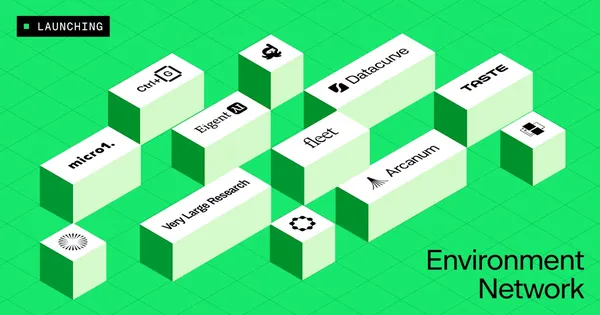
Baseten Launches Network of Vetted RL Environment Companies
Baseten has introduced the Baseten Environment Network, a group of vetted RL environment companies that will build custom reinforcement learning environments for the…
Baseten releases mammoth-1 and elephant-1, open-source decision models
Baseten has released two open-source decision models, mammoth-1 (27B) and elephant-1 (9B), trained by its own research lab. According to the company, mammoth-1 ranks #1…
Baseten's Mammoth-1 and Elephant-1 decision models free on AI Gateway
Vercel has made Baseten's Mammoth-1 and Elephant-1 decision models available for free on AI Gateway for one week, with free access running through October 27. The models…
Reflection's Beam open-weight model launches on Baseten with day-0 support
Baseten has added Beam, the first open-weight model from Reflection, to its platform with day-0 support. Beam is a mixture-of-experts model aimed at coding and agentic…
 Top story
Meta releases Muse Spark Open, an 816B open-weight model for coding agents
Meta has released the weights for Muse Spark Open, an 816B-parameter open-weight omnimodal mixture-of-experts model co-trained with Muse Code for coding agent workflows.…
Baseten adds NVIDIA's Nemotron 3.5 Super VL, an open multimodal model
Baseten has made NVIDIA's Nemotron 3.5 Super VL available for inference and customization. The open multimodal model combines visual understanding, reasoning and tool…
Baseten to host Runway's Gen-4.5 and Aleph 2.0 video models in dedicated environments
Baseten and Runway have partnered to let enterprises deploy Runway's Gen-4.5 and Aleph 2.0 video models, including fine-tuned versions, in single-tenant environments…
Gradium TTS Reaches 155 ms Time-to-First-Audio on Baseten
Gradium's text-to-speech model, designed for real-time AI voice agents, is now available as a dedicated deployment in Baseten's Model Library. According to Baseten, it…
Baseten and Goodfire AI launch Project Beacon for inline safety on open models
Baseten has announced Project Beacon, built with Goodfire AI, to add proactive safety controls directly to model inference. The system reads a model's internal…
Baseten Explains How to Pick Which Layers Run at 4 Bits in NVFP4
A high-quality NVFP4 quantization depends on deciding which layers of a model can run at 4 bits and which need more precision, according to a Baseten blog post published…
Baseten's AI-built inference engine beats vLLM by up to 90% on Qwen decode
Baseten says an inference engine generated by an AI agent outperformed vLLM 0.25.1 by up to 90% on single-stream decode speed for Qwen-3.6-35B-A3B in NVFP4 precision on…
Baseten Claims Fastest GLM-5 Speeds on Artificial Analysis Benchmark
Baseten says its Model API for GLM-5 reached more than 200 tokens per second in a benchmark by Artificial Analysis, with a time to first token of roughly 200ms.…
Baseten joins OpenAI B2B Marketplace as open-model inference provider
Baseten has become one of the first open-model inference providers in the OpenAI B2B Marketplace, including a native integration within Codex. According to Baseten…
Baseten previews Carbon, Blaxel's microVM sandbox for AI agents
Baseten has opened a private preview of Carbon, the fourth infrastructure generation from Blaxel, the sandbox company it acquired. Carbon runs agents in microVM…
Baseten names Sheila Vashee chief marketing officer
Baseten, which builds an inference platform for production AI, has appointed Sheila Vashee as its Chief Marketing Officer. According to the company, she brings more than…